





Just tried @eraserlabs for the first time. Wow - that is some really awesome stuff! Immediately fell in love with DiagramGPT. I've put in my sqlalchemy model and got a perfect entity relationship diagram.
Johannes Hötter retweeted

Über 8000 Leute haben sich bereits für den neuen Kurs von @johoetter und @christianwrmth eingeschrieben 🎉🥳
Du auch? Am 14. Juni geht es los. Wir freuen uns auf Dich!
👉 open.hpi.de/courses/kizukunf…
#ChatGPT #KI #AI #DALLE #Midjourney @HPI_DE @HPI_NYC @SAPLearning
Johannes Hötter retweeted

If you’re not using custom chatbots for the documentation of your product, you are definitely missing out on one of the best use cases for #LLMs.
Check out our latest video to see how it's done in under 20 minutes. Theory and code included.
youtu.be/URYPsgVGDRc


Johannes Hötter retweeted

Oops haven't tweeted too much recently; I'm mostly watching with interest the open source LLM ecosystem experiencing early signs of a cambrian explosion. Roughly speaking the story as of now:
1. Pretraining LLM base models remains very expensive. Think: supercomputer + months.
2. But finetuning LLMs is turning out to be very cheap and effective due to recent PEFT (parameter efficient training) techniques that work surprisingly well, e.g. LoRA / LLaMA-Adapter, and other awesome work, e.g. low precision as in bitsandbytes library. Think: few GPUs + day, even for very large models.
3. Therefore, the cambrian explosion, which requires wide reach and a lot of experimentation, is quite tractable due to (2), but only conditioned on (1).
4. The de facto OG release of (1) was Facebook's sorry Meta's LLaMA release - a very well executed high quality series of models from 7B all the way to 65B, trained nice and long, correctly ignoring the "Chinchilla trap". But LLaMA weights are research-only, been locked down behind forms, but have also awkwardly leaked all over the place... it's a bit messy.
5. In absence of an available and permissive (1), (2) cannot fully proceed. So there are a number of efforts on (1), under the banner "LLaMA but actually open", with e.g. current models from @togethercompute, @MosaicML ~matching the performance of the smallest (7B) LLaMA model, and @AiEleuther , @StabilityAI nearby.
For now, things are moving along (e.g. see the 10 chat finetuned models released last ~week, and projects like llama.cpp and friends) but a bit awkwardly due to LLaMA weights being open but not really but still. And most interestingly, a lot of questions of intuition remain to be resolved, e.g. especially around how well finetuned model work in practice, even at smaller scales.
that moment when you waste one of your 25 GPT-4 messages per 3 hours by replying with "thanks" to a response...
2
97
Johannes Hötter retweeted

This AutoGPT thing is just too powerful.
Task list: 1. Make a todo list. Next task. 1. Make a todo list

Johannes Hötter retweeted

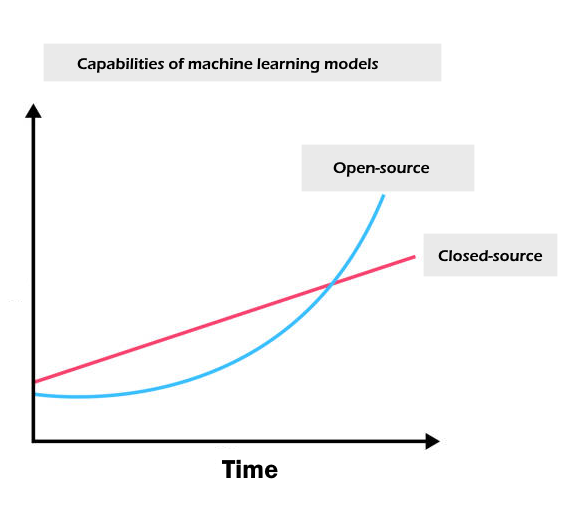
With StableLM initial release (@EMostaque et al. thanks for sharing 🙏),
i think we're at the inflection point on that graph from @abidlabs which i love so much:
Johannes Hötter retweeted

This is not BloombergGPT but our own AskOBB which allows users to interact with the OpenBB Terminal through natural language.
i.e. an open source BloombergGPT.
Still early days, but I'm excited.
Strap in.

Johannes Hötter retweeted

🔥EVERYONE🔥We’re excited to announce the release of OpenAssistant.
The future of AI development depends heavily on high quality datasets and models being made publicly available, and that’s exactly what this project does.
Watch the annoucement video: youtu.be/ddG2fM9i4Kk

ALT OpenAssistant Conversational AI for everyone
Johannes Hötter retweeted
“Give me one example of where NNs outperform GBTs on tabular data. Just one example.”


Johannes Hötter retweeted

Free Dolly! Introducing the first *commercially viable*, open source, instruction-following LLM. Dolly 2.0 is available for commercial applications without having to pay for API access or sharing data with 3rd parties. https://xitter.cf/t.co/HtRVSmArFU
Johannes Hötter retweeted
Event season is about to start! In April you will find us at these events:
#FintechWorld (Berlin, 18th - 19th)
#PyCon (Berlin, 19th)
#LogiMAT (Stuttgart, 25th)
#InsureNXT (Cologne, 26th - 27th)
Come and say hi, we'll be well-equipped with some stickers 😉

As it happened to me again just now: Is there a simple add-on for my GMail that checks if I typed the name of the person I'm writing to correctly (grammarly-style)? That should be super simple, but would be really helpful. E.g. "Johannis" instead of "Johannes" or such.
62
This is 100% what we are seeing at @MeetKern right now. Kudos, very well summarized. And I must say, this perspective is incredibly exciting

Twitter really is its own universe...
All I see here are "ChatGPT/OAI will rule everything!" and "no other model matters!". I think VCs internalize this.
The real world is "I need to control my model's output and want to train/fine-tune my own." "I don't want to copywrited information in my model." "Smaller models are a better app experience." etc.
If the real world speaks, one should listen...it's going to be a lot more complicated. Real apps will be built of bespoke models, APIs, DBs, and code.
1
92
Johannes Hötter retweeted


Introducing Vicuna, an open-source chatbot impressing GPT-4!
🚀 Vicuna reaches 90%* quality of ChatGPT/Bard while significantly outperforming other baselines, according to GPT-4's assessment.
Blog: vicuna.lmsys.org/
Demo: chat.lmsys.org/
With Twitter open-source, the issues of its repository have gone wild. Check out my blog post on this topic here: dev.to/meetkern/twitter-issu…


