
🇨🇿 🇪🇺 Researcher at @ufal_cuni. Working on multilingual NLP and neural machine translation. Views my own. He/him
Prague, Czech Republic
Joined July 2011
- Tweets431
- Following431
- Followers949
- Likes769




Join Mu-SHROOM 🍄, a SemEval 2025 shared task on detecting hallucination spans in multilingual LLM outputs! 🌍 Includes Czech with regional Czech questions 🇨🇿. Do you think you can spot when something isn’t true? 🤔 Try it out! 👉 helsinki-nlp.github.io/shroo… #SemEval2025 #NLProc
Highlights from multilingual #NLProc and machine translation papers I found on arXiv in November are now on my blog: jlibovicky.github.io/2024/12…
This is going to be fun! 🤓 We have three years to spend 6.5M CZK on improving multilingual tokenization. The goal is to make subwords more alignable across languages and help languages that suffer from over-segmentation with current models.

Good news! 🥳 GAČR will fund two of our projects:
👉 @jlibovicky proposes to better tokenization for #LLMs and machine translation
👉 Veronika Kolářová will study syntactic features of Czech non-verbal predicates
➕ Dominik Macháček receives Postdoc Individual Fellowship! 💪
Just shared my takeaways from #EMNLP2024 on my blog: jlibovicky.github.io//2024/1…
There's no clear winner this year's MRL shared task, but we ended up in the cluseer of top-3 teams. I'm so proud of you, folks ☺️
Finally, @kat_haem and Gianluca Vico presented one of the three price-winning 🏆🤑 submissons for the shared task on multilingual named entity recognition and question answering! w/ @AndreiM85400815, @jindra_helcl and @jlibovicky. Congrats! aclanthology.org/2024.mrl-1.…


Thanks to everyone who stopped by the poster ☺️
#EMNLP2024 starts today and @ufal_cuni is here! We start with @jlibovicky presenting work with @jindra_helcl: Lexically Grounded Subword Segmentation aclanthology.org/2024.emnlp-…

This week I am at #EMNLP2024 in Miami 🌴🇺🇸. Find me 🕵️ or message 💌 me if you want to chat about multilinguality or tokenization and stop by our poster on Tuesday at 2 p.m., I'll present our paper on lexically Grounded Subword Segmentation aclanthology.org/2024.emnlp-…

Summaries of #multilingual #LLM and machine translation papers I liked in October are now on my blog jlibovicky.github.io//2024/1… and also on Medium
medium.com/@jlibovicky/highl…
Jindřich Libovický retweeted

... starring @jlibovicky and me as young and perspective scientists with their impeccable movie editing skills
In a week, @jindra_helcl and I will present our paper Lexically Grounded Subword Segmentation at #EMNLP2024 in Miami 🌴🇺🇸. You can already watch our video 🎥 youtube.com/watch?v=NjUmNg6U… or stop by our poster 👋 next Tuesday at 2 p.m...
If you liked the video, read our paper arxiv.org/abs/2406.13560 or check our code github.com/ufal/legros-paper xitter.cf/jlibovicky/status/1842…

In our #EMNLP2024 paper with @jindra_helcl, we present a new subword tokenization method that is more morphologically plausible but maintains the nice properties of existing tokenizers.
Pre-print: arxiv.org/pdf/2406.13560
Code: github.com/ufal/legros
👇🧵1/4

Summaries of a few papers that I noticed on arXiv during summer are now on my blog:
jlibovicky.github.io/2024/10… and on Medium medium.com/@jlibovicky/highl….
In our #EMNLP2024 paper with @jindra_helcl, we present a new subword tokenization method that is more morphologically plausible but maintains the nice properties of existing tokenizers.
Pre-print: arxiv.org/pdf/2406.13560
Code: github.com/ufal/legros
👇🧵1/4
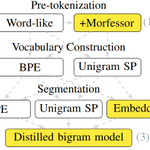
Then, we find segmentations with subwords with the closest embedding closest to the word embedding. We collect bigram stats from those and use them in a bigram-LM-based segmenter (a generalization of SentencePiece).
And we also do some experiments...
🧵3/4
👍 It works great for preserving morpheme boundaries.
👍 Does a good job in POS tagging.
👎 No improvement in machine translation.
And bad news, @zouharvi, our downstream performance does not correlate with Rényi efficiency. 🤷♂️
🧵4/4

📣 We have a dataset!
❓Have you also noticed that language-vision encoders like CLIP do not pay attention to details?
❓ Do you think your model is doing better?
👉 InpaintCOCO dataset huggingface.co/datasets/phiy… is here for you.
Work of @phiyodr, folks from @unibw_m, and myself.

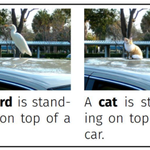
It consists of minimum pairs of images and captions derived from the MS COCO test set. Annotators used object detection and Stable Diffusion Inpanting 👨🎨👩🎨 to get images with either different objects or objects of different colors and sizes. Everything's 100% human-supervised. 💪

In the paper introducing the dataset aclanthology.org/2024.alvr-1…, we also present a method based on hard-negative sampling on the text side of the model that significantly improves the model's ability to distinguish details.
