
Google DeepMind | Prev: @Waymo, @StanfordAILab, CS PhD @GeorgiaTech, Grad @Stanford
Joined April 2020
- Tweets130
- Following144
- Followers1.8K
- Likes962






When LLMs are asked open-ended questions, which cultures do their responses best align with? And can we transparently change that default through inference-time prompt-free interventions?
Excited to share our new COLM '26 work from Google DeepMind: arxiv.org/abs/2603.23301🧵(1/N)

4. Bias is mostly an elicitation problem, not missing knowledge. Steering with CuE beats explicit prompting on cultural faithfulness and surfaces rarer, long-tail cultural concepts that prompting alone tends to miss.
This work was led by our talented past student researcher @simi_97k , supervised by @lunwang1996 , with Hongbin Liu, Shujian Zhang, Mingqing Chen, and Rajiv Mathews.
"Steering LLMs for Culturally Localized Generation" (arxiv.org/abs/2603.23301) COLM 2026

I am hiring a Student researcher at Google DeepMind for Winter/Spring or Summer of 2026!
🛠️ Interested in tool-use and reasoning for LLMs?
🚀 Up-to-date with frontier research?
🔬 Love to understand code & algorithms from first principles?
📚 Currently studying for a BS/MS/PhD?

If so, we want to hear from you! To apply, please follow these two steps:
1️⃣ Fill out the form below to personally express your interest to me:
docs.google.com/forms/d/e/1F…
2️⃣ Fill out the Google DeepMind "Student Researcher 2026" application form:
google.com/about/careers/app…
John Lambert retweeted

After a year of team work, we're thrilled to introduce Depth Anything 3 (DA3)! 🚀
Aiming for human-like spatial perception, DA3 extends monocular depth estimation to any-view scenarios, including single images, multi-view images, and video.
In pursuit of minimal modeling, DA3 reveals two key insights:
💎 A plain transformer (e.g., vanilla DINO) is enough. No specialized architecture.
✨ A single depth-ray representation is enough. No complex 3D tasks.
Three series of models have been released: the main DA3 series, a monocular metric estimation series, and a monocular depth estimation series.
The core team members, aside from me: @HaotongLin, Sili Chen, Jun Hao Liew, @donydchen.
👇(1/n)
#DepthAnything3
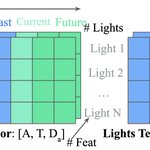
Can a single autonomous driving simulation world model jointly insert, delete, and control the behavior of all agents and traffic lights in a bird's-eye-view scene?
For the first time, we show this is possible in SceneDiffuser++, our CVPR '25 paper, w/ 60+ second simulations.🧵
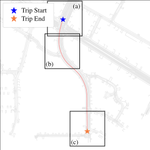
We propose a new task, CitySim, where given a city map and an AV software stack, the simulator can simulate the trip from point A -> B by populating the city around the AV and controlling all aspects of the scene (e.g., vehicles, pedestrians, traffic light states).

Thanks to the team: @maxjiang93 , @stan188249301 , @tanmingxing, @AnguelovDrago, @hongjjeonS, Sakshum Kulshrestha, Yijing Bai, Jing Luo.
- SceneDiffuser++ Paper: arxiv.org/abs/2506.21976
- Watch our video: youtube.com/watch?v=J70R3wxP…
- SceneDiffuser Paper: arxiv.org/abs/2412.12129
Our Gemini 2.5 tech report ✨ is finally out on arXiv -- grateful for the collaboration with brilliant colleagues! arxiv.org/pdf/2507.06261