Focus on Multimodality, a Phd student at @Open_MOSS I am seeking job opportunities now! https://xitter.cf/t.co/JWEcTMulDU
Joined September 2022
- Tweets41
- Following104
- Followers12
- Likes79

Jun Zhan retweeted

Today we’ve raised $52M Seed and we are announcing the public launch of S2.1 Pro.
>It can clone a voice from 5 seconds of audio
>2x faster than Cartesia & 1/6th the cost of Eleven Labs
>most expressive model with word level control over emotion, intonation, pacing etc
We support frontier AI companies including HeyGen, LiveKit, Retell, Sanas, and OpenArt all run our model in production.
If you're a business and we can't cut your voice AI costs by 50%, we'll give you 1 year of Fish Audio for free.
Book a demo: s.fish.audio/tmapke
To celebrate our first birthday, we'll give you 1 month of S2.1 Pro for free. Like, retweet, and comment “Fish” to get it.
What if audio and video could understand each other before generation even begins?
Meet OmniVAE: a joint audio-video VAE that aligns their latent spaces to improve generation quality, Audio/Video sync, and lip sync—without sacrificing reconstruction. @HuggingPapers


『響け!ユーフォニアム』10周年記念公演で、三期の物語をようやく理解できた
京吹十周年演奏会上突然明白了第三季
At the Sound! Euphonium 10th Anniversary Concert, I Finally Came to Understand the Story of Season 3


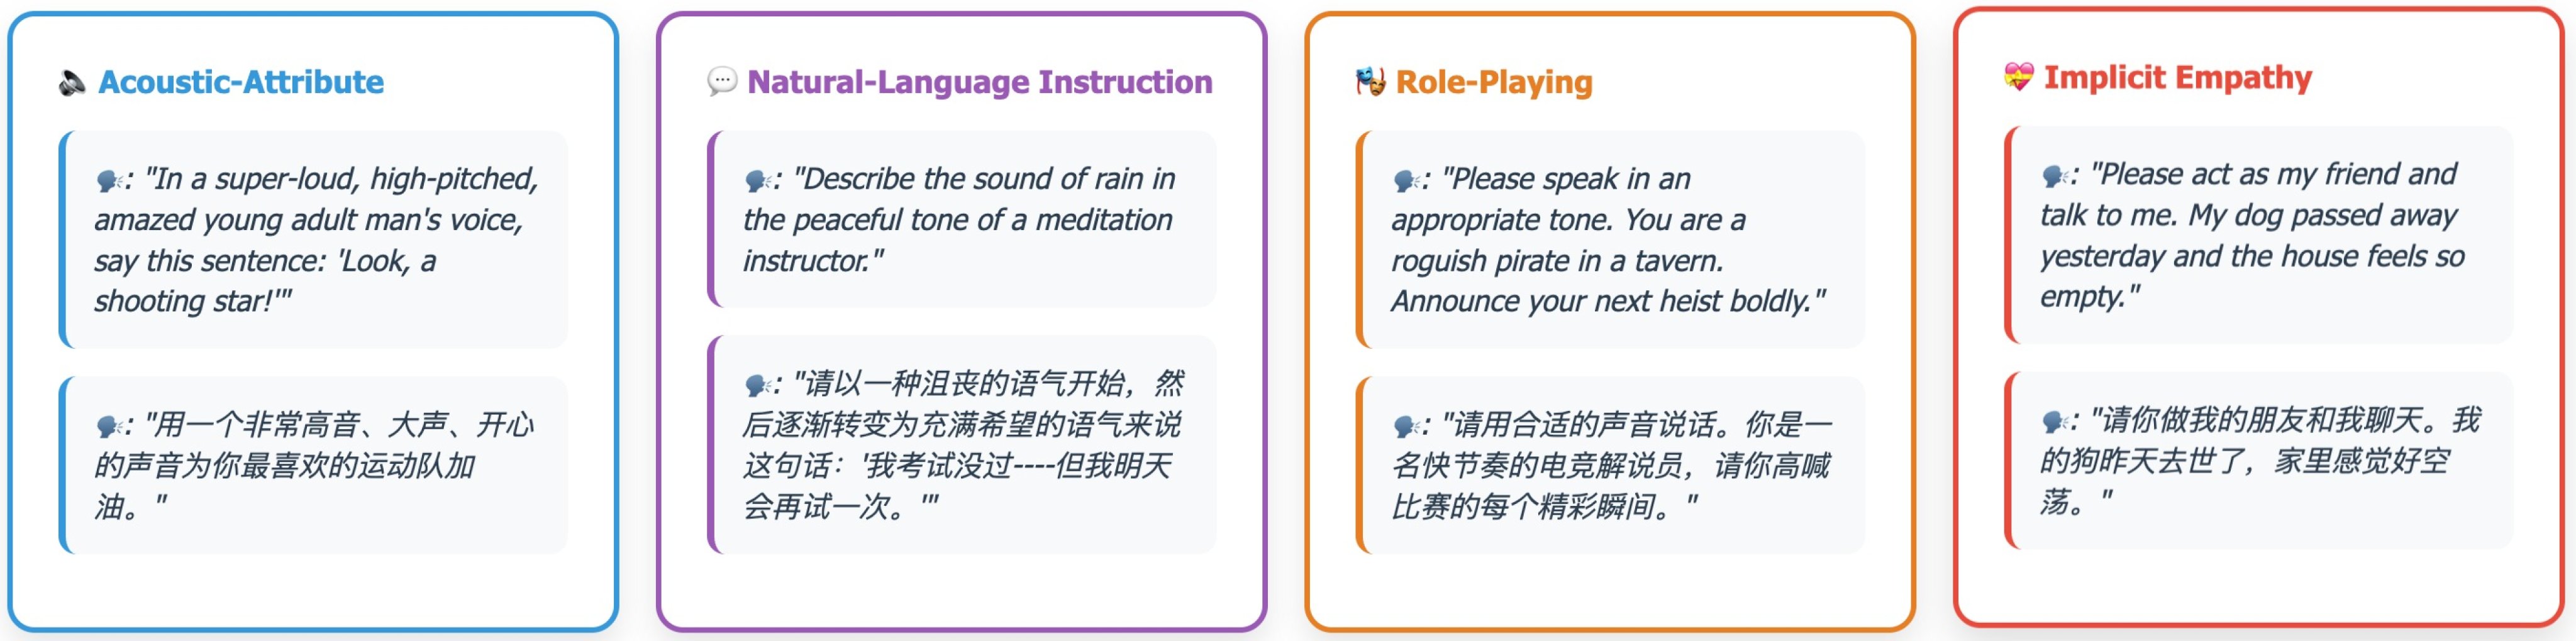
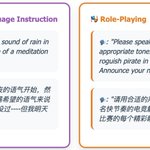
We release VStyle, a benchmark for voice style adaptation in speech language models, with automated evaluation via LALM. Results show closed‑source models still clearly outperform open‑source ones!
📄 arxiv.org/abs/2509.09716
💻 github.com/alibaba/vstyle
🌐junzhan2000.github.io/VStyle…