

Building @KuralitHQ - making every app conversational. 5 yrs production AI. Prev: built @Kuralynx. Shipping in public now.
Chennai, India
Joined August 2025
- Tweets156
- Following566
- Followers27
- Likes430

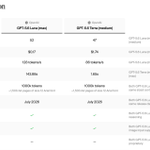


Much expected this, waiting for Fable beating Opus soon!


Can't agree more!! OMP is being my daily driver these days, from my view, multiple ways AI slop get created, one is through lack of human review. OMP is trying to reduce the second part with its great pack of fat harness & multi agents.

Relative preference is not always absolute acceptability. And this changes how we interept Jev's zero hallucination claim.
0% hallucination number is not empirical, it comes from the fact that schema matching is guaranteed. So Choices and State we provide to the JEV should be in align always to expect absolute acceptability.


I keep thinking about this with Jev and i'm no expert or tech guy.
What if I give it 5 options and all 5 are not relevant?
Will it pick one with 60% confidence and technically never “hallucinate”?
But it's still wrong lol.
For agents and UI decisions, I think “none of these are good enough” is actually a pretty important answer.
Am I right here @itskeyans?
btw if anyone wonders we've paper already released 2 years back on RLCD
You are not missing a secret Jev paper. You are looking at two different methods that happen to share the letters RLCD.
@typesafeai JEV is Reinforcement Learning for Calibrated Decisions (*RLCD). This @arxiv paper is Reinforcement Learning from Contrastive Distillation (*it's LLM 🙂).

My whole feed is full of JEV today, really @typesafeai has not exposed any information on what is RLCD, but we got lot of open contributions until JEV opens up about the architecture.
If anyone wants to know reality of building the JEV lookalike models, Sharing the resources I found it useful here:
lilting.ch/en/articles/jev-c…
systemonemodels.org/guides/r…

Admiring @JeffBezos on his writing so cleanly
four element to high standards: they are teachable, they are domain specific, you must recognize them, and you must explicitly coach realistic scope.

In 2 pages @JeffBezos teaches you more about high standards than you'll learn from reading 2 books. The art of summarizing that which resists summary is critical to achieving greatness. The world will forget you, except what you've written down, then what you've written down well.


If you think Terra medium is the best tradeoff between intelligence and cost. You're wrong!
Luna max is best in intelligence scores and cost. Impressive! catching up this lately

Karthikeyan Saravanan retweeted

Teach your agents inference.
The full text of Inference Engineering is now available to LLMs everywhere. No more parsing PDFs.
3,000 tokens | links to each chapter: baseten.co/inference-enginee…
70,000 tokens | full text: baseten.co/inference-enginee…

if anyone wants to build presentations with codex/claude code, here's the gem i found: github.com/zarazhangrui/fron…
@zarazhangrui good curation!!

3 papers we’re discussing at Distill Zero this Saturday in Chennai:
• Self-Harness - agents improving their own harness
• Refuses the Shape, Serves the Substance - why many AI failures aren’t attacks
• Ask, Don’t Judge - a different way to evaluate LLM outputs
If you’re into AI/ML research and like going beyond the abstract, come join the room.
luma.com/wce8rys7

Chennai AI/ML folks - this one’s for you 👀
Distill Zero #02 is happening this Saturday.
A small room of researchers, engineers, builders & students getting together to actually read and discuss AI/ML papers - not just skim the abstract and move on.
We’ve locked the presenters for this edition.
If you’re into:
• LLMs / NLP
• Agents
• ML research
• understanding papers beyond the hype come join us.
📍 Chennai
📅 Aug 29
luma.com/wce8rys7
#Chennai #MachineLearning #AIResearch

Chennai AI/ML folks 👋
We're looking for presenters for the next Distill Zero.
If you’re working on interesting AI/ML research, building something research-heavy, or simply want to break down a paper you found interesting - we’d love to hear from you.
Not your own paper? Totally fine.
If this sounds like you, DM me.
#Chennai #AI #MachineLearning #Research

"Chennai builds services. The real AI research happens elsewhere."
We ran Distill Zero edition #1 on Saturday to start chipping at that.
25 people in one room, on a Saturday evening, reading papers.
4 papers presented:
1. Training LLMs to reason in a continuous latent space - the chain of thought never becomes words
2. From reasoning traces to reusable modules - SFT supplies the raw material, RL carves the skill
3. RoboMorph - an LLM as the mutation operator in an evolutionary loop
4. LLM agents reproducing real web CVEs
But the papers were the excuse.
The good part was people arguing about experimental setups, pulling out laptops mid-talk to check a claim, and disagreeing with the presenter in front of everyone.
That is the whole point. Not another room where people photograph slides and leave.
Edition 2 is already in motion:
- Open call for papers, anyone can present
- A guest session we are locking in now
Recording drops on YouTube this week.
Want to present or attend? Follow Distill Zero
Edition one is distilled. On to the next.


seems like @opencode server's are struggling for the past 3 hrs, with this new model. It's quite a good model, from my run, working up near to fable.

honestly, Ox Alpha model is unreal. super fun to chat with and the limits are surprisingly high. Whatever lab is behind this stealth drop really cooked.


There is no exception for anyone to start building it right now!
zero cost starter options are growing - @Replit free mode, @opencode free model access, but note your code's are being trained on them, so use it with lowkey prototypes.

Replit Free Mode, powered by @OpenAI GPT-5.6 Luna.
Let’s make intelligence accessible to everyone.
Free @opencode Go plan. Going to set DeepSeek V4 Flash on fire and see what happens
