
Deep Learning Researcher @NVIDIA
Israel
Joined September 2020
- Tweets76
- Following3.2K
- Followers387
- Likes3.2K





2/3
The result: 2x higher throughput under the same interactivity constraints, while maintaining strong accuracy across benchmarks.
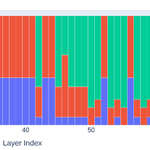
At the core is Iterative Puzzle: a compression recipe that alternates heterogeneous pruning with short recovery phases.
1
11
914
3/3
This lets the architecture search adapt as the model changes, instead of compressing everything in a single step.
Check out our tech report to learn more about heterogeneous pruning, knowledge distillation, RL, quantization, and MTP training.
huggingface.co/nvidia/NVIDIA…

Itay Levy retweeted

We’re releasing Nemotron-Labs-Diffusion - the first Tri-mode LM family (3B/8B/14B) that switches between 1⃣Autoregressive, 2⃣Diffusion, and 3⃣Self-Speculation decoding by simply changing the attention pattern/mask.
One model Three decoding modes. No extra draft models. No architecture changes. Just significantly better efficiency across different concurrency levels.
Up to 4× higher real throughput for a single user.
🤗 HF Collection: huggingface.co/collections/n…, open license
🛜 Project page: research.nvidia.com/publicat…
📰 Tech report: bit.ly/Nemotron-Labs-Diffusi…
Details below 👇

Itay Levy retweeted

Nemotron 3 Super is live! So far the most intelligent agentic reasoning model in the Nemotron family, with world leading efficiency and openness.
Super particularly marks our first infra & research milestone in agentic reinforcement learning scaling up.
Stay tuned for more infra, data and agentic generalization research we will open to the ecosystem.
🤗 Huggingface: lnkd.in/gWfamwwX
📜 Tech Report: lnkd.in/gRFFJxKm
🤸♂️NeMo-Gym (RL env data and orchestration): github.com/NVIDIA-NeMo/Gym
🤸NeMo-RL (RL training): github.com/NVIDIA-NeMo/RL

Itay Levy retweeted

Nemotron 3 Super is here! 🚀
Big capability jump, especially on agentic benchmarks, while staying built for efficient inference. Released the @nvidia way: weights + training recipes + code + datasets.
HF: huggingface.co/nvidia/NVIDIA…
Tech report: research.nvidia.com/labs/nem…

Itay Levy retweeted

My last open-source project before joining xAI is just out today. Megatron Core MoE is probably the best open framework out there to seriously train mixture of experts at scale. It achieves 1233 TFLOPS/GPU for DeepSeek-V3-685B. arxiv.org/abs/2603.07685


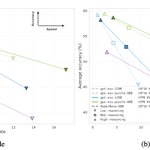
For reasoning models, tok/s isn’t sufficient because trace length can change, so we also measure request-level efficiency. On the accuracy–speed frontier, 88B outperforms 120B across all efforts, with up to 1.29× higher request rates
1
1
156
Paper: arxiv.org/abs/2602.11937
The model will become available on HF soon

1
127
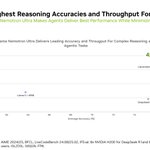
Try Llama Nemotron Ultra 253B, the smartest open reasoning model available today!
🏆 Tops scientific reasoning, complex math and coding benchmarks
⚡️ 4x higher inference throughput over DeepSeek R1. Optimized with neural architecture search and FFN fusion


1
8
384
It has been an honor for us to collaborate on the Llama-Nemotron family, creating open world-class frontier models!
build.nvidia.com/nvidia/llam…
1
119


Itay Levy retweeted

Puzzle: Distillation-Based NAS for Inference-Optimized LLMs
Author's Explanation:
xitter.cf/itayoush/status/186358…
Overview:
Puzzle introduces a distillation-based neural architecture search framework that significantly optimizes LLM inference on specific hardware, achieving a 2.17x speedup with a 98.4% retention of the original model's capabilities via blockwise local knowledge distillation and mixed-integer programming.
The framework's application to Nemotron-51B enables a single NVIDIA H100 GPU to handle large batch sizes, highlighting the efficiency of the approach with only 45B training tokens needed compared to the 15T used for the original model, thus prioritizing inference performance over parameter count for model selection.
Paper:
arxiv.org/abs/2411.19146


Introducing Puzzle: Distillation-Based NAS for Inference-Optimized LLMs
🔗 arxiv.org/abs/2411.19146
🧵

Introducing Puzzle: Distillation-Based NAS for Inference-Optimized LLMs
🔗 arxiv.org/abs/2411.19146
🧵
Puzzle accelerates LLM inference on specific hardware while preserving capabilities. Using decomposed NAS and knowledge distillation, we optimize LLMs under hardware constraints, while requiring only a fraction of the original training compute
1
70