

Currently hacking on the Humane Ai Pin (previously Vision Pro and Analogue Pocket). Mastodon: https://xitter.cf/t.co/BX8F6i31Hu
Joined May 2021
- Tweets1.2K
- Following234
- Followers2.5K
- Likes906




Pinned Tweet
Big Humane Ai Pin milestone: Full preservation of the original experience, entirely on-device.
I've applied Humane's UX work and polish so we can build whatever functionality we want
Video: Ai Mic -> cosmOS -> Gemini -> live search
Powered by PenumbraOS penumbraos.com/

I'm sure people are buying a $2k+ iPhone Duo to... Play 40+ year old Game & Watch games!
Now you can wish your fancy new phone into the 80s hands of a child
Adam Gastineau retweeted
Introducing Super Nt+ and Mega Sg+
The definitive way to play original Super Nintendo, Super Famicom, Sega Genesis, Mega Drive, and Master System.
Beginning with Super Nt in 2017, the originals set a new standard for video game preservation. Nearly a decade later, they return.
Super Nt+ & Mega Sg+. Definitive, all over again.
Now with Bluetooth + 2.4G. Reworked industrial design, OS, packaging, and more.
At the core: an FPGA architecture engineered in-house from scratch, backed by over a decade of development. Purpose-built 1080p for 2D gaming. No emulation. Zero lag. Total accuracy. Plug and play.
Preorder Oct 19, 8am PDT. Ships Dec 2026.
analogue.co

Have people settled on a location for sharing LLM speed benchmarks? The sites I find seem abandoned
It's frustrating not being able to compare. I can't tell if M5 Ultra Q8, 32k, single stream at 185 t/s is good or not. Some places say 6000 Pro isn't typically hitting that at Q4
I wanted to try messing with (prompting) inference improvements with M5 Ultra. I'm rather surprised at the results and after a lot of checking I think they're accurate
M5 Ultra 256GB, 80 core, Qwen3.8 Flash Next Q8
Up to 85% faster decode vs oMLX main: 378 t/s @ 32k, 8 streams


If you found PenumbraOS (the jailbreak for the Ai Pin) to be too cumbersome, Anders' Luma is probably more like the tool you're looking for.

Your Ai Pin. Yours again.
github.com/TheAndersMadsen/l…

If you're an iOS dev, you may have noticed that Device Hub doesn't support multitouch gestures with Option + Mouse, unlike Simulator has for a long long time (maybe forever?).
This simple tool restores the lost behavior. github.com/agg23/DeviceHubMo…

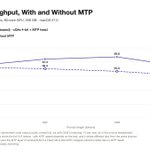
GLM 5.3 Flash, Q4, 1 stream, 128k context, code:
oMLX (latest main): 69.8 tok/s decode MTP (53.3 without), 2288 tok/s prefill
Prefill barely unaffected by context size


Batch 2 of M5 Ultra benches. Things are changing fast
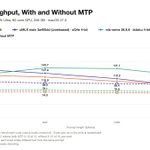
Qwen 3.8 Flash Next, Q4, MTP, 1 stream, 128k context, code:
mlx-serve 26.9.6: 141 tok/s decode, 3783 tok/s prefill
oMLX main (unreleased): 112 tok/s, 5331 tok/s prefill
oMLX 0.7.0rc1: 105 tok/s, 3624 tok/s prefill


Q8 continues to perform just as well with the new changes. I had to submit a small patch to fix a OOM bug, so I imagine few people have tried Q8 on Macs.


Rough M5 Ultra 80 core GPU 256GB benches:
Qwen 3.8 Flash Next, Q4 variants, MTP, 1 stream, 32k context, averaged code/prose:
TensorFold 0.3.4.1: 152 tok/s decode, 2086 tok/s prefill
mlx-serve 26.9.6: 124 tok/s, 3863 tok/s prefill
oMLX 0.7.0rc1: 105 tok/s, 3694 tok/s prefill


Somewhat similar TensorFold numbers against M3 Ultra
xitter.cf/ivanfioravanti/status/…

Long Context Benchmark: TensorFold 0.3.4.1 + PR 29 and PR 30 on M3 Ultra with Qwen 3.8 Flash Next 4bit. 🔥
Now prefill is great and there are no more issues with 64K+ context on first decode request.
Here a comparison 0.3.4, 0.3.4.1 and this version.
Peak:
- 0.3.4.2 130 t/s
- 0.3.4 128 t/s
- 0.3.4.1 119 t/s

It is pretty hard to approach this scientifically, especially since I am not familiar with the field. I would not be surprised if the choice of quants messed up the engine comparisons significantly. TensorFold in particular is built for a very specific model + quant at the moment
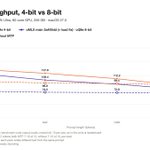
Could only get oMLX to run Q8, so here's a Q4 vs Q8 comparison for oMLX only.
Seems to be a ~12-14% cost to moving to Q8 ad the moment.
95 tok/s Q8 vs 105 tok/s Q4 @ 32k

I'm excited to begin testing the M5 Ultra 256GB Mac Studio
Benchmarks seem rare at the moment. Tell me a good benchmark regimen (test set, models, engines) and I'll attempt to get some comparable numbers
I would like to see numbers taken by the same author in similar scenarios
It's hard to find reliable sources for a given model and quant. My current plan:
Vontra/GLM-5.3-Flash-MLX-oQ4-MTP
Vontra/Qwen3.8-Flash-Next-MLX-8bit-MTP
mlx-community/GLM-5.3-Flash-4bit
mlx-community/Qwen3.8-Flash-Next-oQ6e-mtp
mlx-community/Qwen3.8-Flash-Next-oQ8e-mtp