

Head of Field Marketing & Community, @braintrust Prev. @vercel @digitalocean @netapp
NYC
Joined August 2014
- Tweets435
- Following580
- Followers442
- Likes1.4K


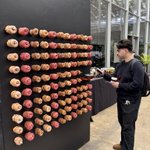

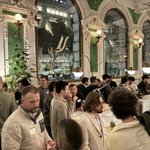
Spent the day with some of NYC’s top GTM operators, swapping stories and hot takes.
Thanks to @Work_Bench for bringing us together!


2
148


Mohan Ram retweeted

After our first edition in NYC, we’re bringing The AI Dev Stack to San Francisco.
Join @FireworksAI_HQ, @braintrust, @browserbase & @antimetal on Aug 18 to see how teams are building the modern development stack beyond coding agents.
RSVP Required.
luma.com/ai-dev-stack

Mohan Ram retweeted

Out of the box, long-horizon agents struggle to accurately perform end to end work in the real economy (outside of coding) because those tasks are not easily verifiable, the data is hard to scale, and going from inputs to real outcomes can actually take many days.
Even if you had a reliable way to verify outcomes at scale (and weren’t bothered by the multi-hour iteration loops), the sheer volume of decisions by the agent that occur in a multi-hour job makes it hard to know whether performing well will generalize to production.
Over the last two years at @trybasis, we've been solving this problem by supervising the process our agents take to get to outcomes, rather than just looking at whether the outcome itself is correct.
We think this is the key to building production agents at scale.
It's what has allowed us to run agents in production that operate for hours, sometimes days, and reliably perform tasks like entire complex tax returns end to end.
Today, alongside @braintrust, we're open sourcing a standard for defining, evaluating, and eventually rewarding agent behaviors.
Thread below with all the details on how we’re scaling behaviors to close the loop for long-horizon agents.

Mohan Ram retweeted

We are super excited for the upcoming @daytonaio HackSprint w/ @braintrust on July 24 at the @WorkOS office in San Francisco!
Can't wait to kick off the hackathon with our amazing partners: @braintrust, @ElevenLabs , @FireworksAI_HQ, @WorkOS, @coderabbitai, and @CopilotKit.
Great prizes are up for grabs for the best projects, including cash, credits, and more. We can't wait to see what everyone builds!
More details and RSVP: luma.com/hacksprint-sf

Mohan Ram retweeted

We ran the 48 Group Stage World Cup matchups through six configurations of @p0 research agents and scored every output in Braintrust.
Here's what we found → braintrustdata.link/knowledg…

Mohan Ram retweeted

If you cannot define “good” and measure it, you are not ready to ship. For long-context LLM systems, “good” does not just mean a bigger context window. It means the model can find the right function, inside the right class, in the right file, and retrieve the exact facts needed to produce accurate behavior.
This needle-in-a-haystack problem gets much harder when the haystack is a million tokens of packages, repos, and docs.
That is what we stress tested with GLM-5.2 on Baseten. (and it was awesome collab-ing with @thealexker @philipkiely and team!)
In this methodology post, we go deeper on how we scoped the eval, generated the benchmark, scored the outputs, and tested the scorers themselves.
Eval methodology: braintrust.dev/blog/glm-52-v…
We're making GLM-5.2 available in Braintrust today with the help of our friends at @baseten.
This means you can run evals on GLM and compare it to other models for specific tasks, which is exactly what we did.
When testing long-context retrieval Opus 4.8 is only modestly more accurate given relative costs.
Opus 4.8 leads GLM-5.2 by about 3.5 points at both 25K and 50K tokens, but at the same context sizes, Opus costs about 4.1x to 4.5x more per trace.
@iz_hurley_ wrote it up here: braintrust.dev/blog/glm-52-v…

RT @alignedai: Still thinking about The Agent Open.
Great panel, people, and vibes, honestly some of the most thoughtful event design @aiD…
Mohan Ram retweeted

ai pickleball tournament was actually so good. they executed the concept perfectly. glad @MehulKalia_ and i showed up from Notion to see some familiar faces :)
@braintrust @modal @browserbase @llama_index @turbopuffer @paralell @cursor_ai


Building agents you can trust in production. Cheering at the FIFA world cup.
Our customers are fluent in both.
@braintrust


4
168
The Agent Open SF 2026 is happening on June 30.
Hosted by @braintrust • @llama_index • @p0 • @cursor_ai • @turbopuffer • @modal • @browserbase
Join us: luma.com/the-agent-open

3
120
Mohan Ram retweeted

One of the most exciting updates from my time so far at @braintrust: Topics is now GA, and every plan includes a monthly credit :)
the flywheel is real. AI observability >> active observability
Mohan Ram retweeted

If you’re scoring 100% on your evals, you’re either building a perfect agent (you aren’t) or something is wrong with your evals. This workshop teaches you how to fix them.
Absolutely PACKED room for Curtis Galione, Solutions Engineer at @Braintrust with many thoughtful questions from the audience.
Evals are clearly top of mind. Great job, Curtis!


If you're going to @Snowflake Summit this year, this is the afterparty you won't want to miss.
We're partnering with our friends at @motherduck @braintrust @_hex_tech @AirbyteHQ to throw a party with drinks, a DJ, and great vibes right around the corner from Moscone at the Contemporary Jewish Museum on 6/1! 🥳
Kick off the first night with us: RSVP at the link in the comments.

Mohan Ram retweeted

If you're heading to #AIAgentConference NYC 🗽 next week and looking for something to take the edge off...
@lancedb, @modal, @braintrust, and @augmentcode are coming together for an evening of conversations & cocktails! Come for the food and drinks, leave with great vibes 💃🏻

Mohan Ram retweeted

agents: easy to build, depreciate fast, failure mode is not to evolve fast enough
evals: hard to build, appreciate with more data, reuse across agent architectures, compounding advantage over time
spend the effort engineering good evals => win over the long term!
Mohan Ram retweeted

HumanX was a blast! Some highlights:
-> @tuhinone and @saranormous took the main stage to discuss what it takes to build a durable AI application
-> @DannieHerz joined the AI Leaders panel with our friends at Braintrust and Hex


We brought together 400+ builders in the @SFMOMA atrium for a fun happy hour with our friends from @browserbase @modal @WorkOS @mintlify @MongoDB @resolveai @augmentcode and @StainlessAPI


2
195
Mohan Ram retweeted
You can't write evals for what you haven't seen yet.
We talked with @braintrust VP Field CTO, Ameya Bhatawdekar, at HumanX about why production observability is what makes evals actually work.
Wrapping up day 1 at @HumanXCo with a panel on ‘building AI that actually works’ with our friends from @baseten and @_hex_tech

