
Research Scientist @GoogleDeepmind. Past: Researcher @Meta, PhD @CarnegieMellon, BSE @Princeton Opinions are my own
Joined September 2023
- Tweets90
- Following122
- Followers62
- Likes141




Charlie Hou retweeted

Excited to share Gemini 4 Argon! I know many people have been curious about what we’ve been building. We are sharing as soon as possible starting with trusted defenders in our Fairwind Program.
We developed Argon with frontier capabilities in coding, knowledge work and cyber security defense. We look forward to making it more widely available as we go through testing.

Importantly Argon has frontier safeguards and we are rolling it out responsibly - it’s with the US gov’t and going to a set of trusted cyber defenders through our Fairwind Program today.
We’re going to make it available as soon as we can and as safely as we can. So hold tight, lots more coming, and you’re going to see us iterating rapidly.
blog.google/innovation-and-a…

Frontier cyber models seem like the perfect solution to this problem, why isn't it being done yet?
reuters.com/world/hack-water…

Fable/Opus are still a lot easier to work with.
My average 5.6 Sol Ultra session is it running 5h straight, billions of tokens wasted, 50% usage gone just to create and run 10000 useless tests


Charlie Hou retweeted

I worked for Peking University for a decade when China was loudly touting it desire to get more Chinese back to China. Let me tell you the dirty secret:
Almost none of the returning Chinese who I counted as friends said or indicated them returning to China had anything to do with geopolitics. A spouse. Simply returning back home. An aging parent. The vast majority of time people moved back to China had zero to do with global politics, US politics, and everything to do with just what they wanted to do in life. I'm very sorry to disappoint whatever narrative you have





Charlie Hou retweeted

Our @initc3org team of over 20 authors spent the last 6+ months wading through a huge body of work to systematize what we know (and what we don't!) in the space of AI x crypto. A few main takeaways:


Charlie Hou retweeted

Almost all animals sleep. Why don’t LMs?
Introducing our new work on language model sleep.
tl;dr : A periodic, recurrent “sleep” phase allows LMs to digest their context and transfer it into their weights, improving recall and reasoning on challenging tasks.
Charlie Hou retweeted

Sharing a super simple, user-owned memory module we've been playing around: nanomem
The basic idea is to treat memory as a pure intelligence problem: ingestion, structuring, and (selective) retrieval are all just LLM calls & agent loops on a on-device markdown file tree. Each file lists a set of facts w/ metadata (timestamp, confidence, source, etc.); no embeddings/RAG/training of any kind.
For example:
- `nanomem add ` starts an agent loop to walk the tree, read relevant files, and edit.
- `nanomem retrieve ` walks the tree and returns a single summary string (possibly assembled from many subtrees) related to the query.
What’s nice about this approach is that the memory system is, by construction:
1. partitionable (human/agents can easily separate `hobbies/snowboard.md` from `tax/residency.md` for data minimization + relevance)
2. portable and user-owned (it’s just text files)
3. interpretable (you know exactly what’s written and you can manually edit)
4. forward-compatible (future models can read memory files just the same, and memory quality/speed improves as models get better)
5. modularized (you can optimize ingestion/retrieval/compaction prompts separately)
Privacy & utility. I'm most excited about the ability to partition + selectively disclose memory at inference-time. Selective disclosure helps with both privacy (principle of least privilege & “need-to-know”) and utility (as too much context for a query can harm answer quality).
Composability. An inference-time memory module means: (1) you can run such a module with confidential inference (LLMs on TEEs) for provable privacy, and (2) you can selectively disclose context over unlinkable inference of remote models (demo below).
We built nanomem as part of the Open Anonymity project (openanoymity.ai), but it’s meant to be a standalone module for humans and agents (e.g., you can write a SKILL for using the CLI tool). Still polishing the rough edges!
- GitHub (MIT): github.com/OpenAnonymity/nan…
- Blog: openanonymity.ai/blog/nanome…
- Beta implementation in chat client soon: chat.openanonymity.ai
Work done with amazing project co-leads @amelia_kuang @cocozxu @erikchi !!
I recently started a new role as a Research Scientist at Google DeepMind!
Before looking ahead, I want to say a huge thank you to my former teammates at Meta. I'm incredibly grateful for the time we spent building together, and I know they will continue to build amazing things.
I’ve always admired DeepMind’s focus on building AI responsibly to benefit humanity. I'm really excited to collaborate with such a brilliant team and tackle some of the hardest foundational problems in our field.
Can't wait to get to work!

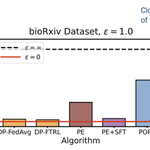
Gave a talk at @OpenAI on our work 🌸 POPri “Policy Optimization for Private Data”. POPri is a huge improvement in synthetic data generation under security+privacy constraints! Learn more:

POPri also sees strong efficiency gains vs prior state-of-the-art like Federated Learning, with much lighter computational burden on the user devices. In exchange, more server compute is used.

Code: github.com/meiyuw/POPri
Paper: arxiv.org/abs/2504.16438
Huggingface papers: huggingface.co/papers/2504.1…
Datasets: huggingface.co/hazylavender
Thanks to the team: Mei-Yu Wang, Yige Zhu, Daniel Lazar, and @giuliacfanti
