




Bogdan Kulynych retweeted
The NeurIPS position paper track was flooded with submissions that substantially used AI. More than other tracks, and despite a requirement otherwise.
I appreciate the chairs' strong action. People are not entitled to reviewers' time, AI makes it exceptionally easy to waste it.

This year, the NeurIPS 2026 Position Paper Track made the decision to require that all papers be substantially human-written, with AI used for only copy-editing or similar peripheral changes to the main text!
For more details, please check our blogpost: blog.neurips.cc/2026/06/02/a…
Bogdan Kulynych retweeted
A Gaussian mechanism with ε = 6 can be less private than one with ε = 8. This points to a problem with how we report privacy guarantees in machine learning. A thread 🧵
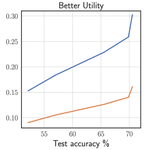
Here's an example for a specific instantiation of DP-SGD in terms of f-DP trade-off curves (an equivalent operational version of privacy profiles). As we see, a non-asymptotic GDP trade-off curve fits the DP-SGD trade-off curve almost exactly.

We've built a new Python package gdpnum to compute non-asymptotic GDP guarantees and estimate their precision for many practical algorithms:
github.com/interpretable-dp/…

Here's a paper with all the details:
arxiv.org/abs/2503.10945
@physics_Felipe presenting it at #SatML on Tuesday March 24.
w/ @physics_Felipe, Borja Balle, Jamie Hayes, @FlavioCalmon, @ahonkela

Many ML algorithms, especially those involving many compositions like DP-SGD, can be very precisely characterized with GDP. This is a *non-asymptotic* result, not just a central limit approximation!
A Gaussian mechanism with ε = 6 can be less private than one with ε = 8. This points to a problem with how we report privacy guarantees in machine learning. A thread 🧵

Can we do better without reporting an entire privacy profile? Yes! With Gaussian differential privacy (GDP).
As the convention sets δ in a data-dependent way, this matters whenever you compare models across datasets or papers.
Issue 2: You can't properly compare two mechanisms by ε if their δ values differ. A Gaussian mechanism with ε = 6 at δ = 10⁻⁵ is less private than one with ε = 8 at δ = 10⁻⁹. This is because you cannot properly compare ε if δ is different.
No attacker in the universe can achieve that 98% rate: It's purely an artifact of compressing the entire privacy profile into one pair (ε, δ). My colleagues and I detailed on this problem in detail in this NeurIPS'24 paper:
arxiv.org/abs/2407.02191
Issue 1: A single (ε, δ) pair can massively overstate privacy risk. Example: DP-SGD with ε = 8 at δ = 10⁻⁵ suggests a worst-case membership inference accuracy of ~98% using standard conversions. But using the full privacy profile, the actual maximum is only ~68%.
The standard way is to report is to use a single (ε, δ) pair for a small δ. The community has developed informal conventions, e.g., ε < 10 is generally considered OK in privacy-preserving machine learning. But this convention has two big issues.
Presenting this on Thursday Dec 4 at #EurIPS in Copenhagen. Come by at the poster session if this sounds interesting!
#NeurIPS2025

New paper at #NeurIPS2025!
"Unifying Re-Identification, Attribute Inference, and Data Reconstruction Risks in Differential Privacy" in which we derive unified, tighter bounds on operational attack risks for any DP mechanisms, using f-DP.
Link: arxiv.org/abs/2507.06969
Thread👇


New paper at #NeurIPS2025!
"Unifying Re-Identification, Attribute Inference, and Data Reconstruction Risks in Differential Privacy" in which we derive unified, tighter bounds on operational attack risks for any DP mechanisms, using f-DP.
Link: arxiv.org/abs/2507.06969
Thread👇

Continued here:
xitter.cf/hiddenmarkov/status/19…
Continuing the thread on "Unifying Re-Identification, Attribute Inference, and Data Reconstruction Risks in Differential Privacy", for some reason it got borked.
xitter.cf/hiddenmarkov/status/19…