
Building @mostlyrightmd - Public information, strucutred for machines. Sold @avocode to @cerosdotcom, @500GlobalVC alum. Prev @marinadefinance.
Prague
Joined December 2011
- Tweets786
- Following1.2K
- Followers1K
- Likes740




The coolest part was using EmbeddingGemma 2 to embed product text, images and recipe ingredients, then match ingredients to actual products even when their names differ.
We precompute those matches so we don’t repeat the work on every query.
JEV from @typesafeai figures out what you mean, chooses the filters and ranks the results. For recipes, it uses those precomputed ingredient matches.
Try “everything I need for lasagne.” Or laundry gel. Or cat food.
GO TRY IT: chcirohlik.cz
@tomcupr pls collab

I promised one dataset a day until @mostlyrightmd hits 1,000 users. This one’s taking longer than expected 😅
Here is a sneak peek: medicine search across countries, with JEV planning the search and EmbeddingGemma 2 powering embeddings.
Reply for early access!
I just made a BIG update to the movie search I posted yesterday. You can now search 1.26m movies & tv shows by what is on the poster, and it now also supports search in 100+ languages.
Try "poster with a clown" or "poster with a yellow umbrella".

I built a cracked search over 1.26m movies & tv shows with Clef (@Cloudflare) and Jev (@typesafeai) on a @mostlyrightmd dataset, and it's stupid fast
plot: boy befriends alien
actor: tom hanks
character: darth vader
studio: a24
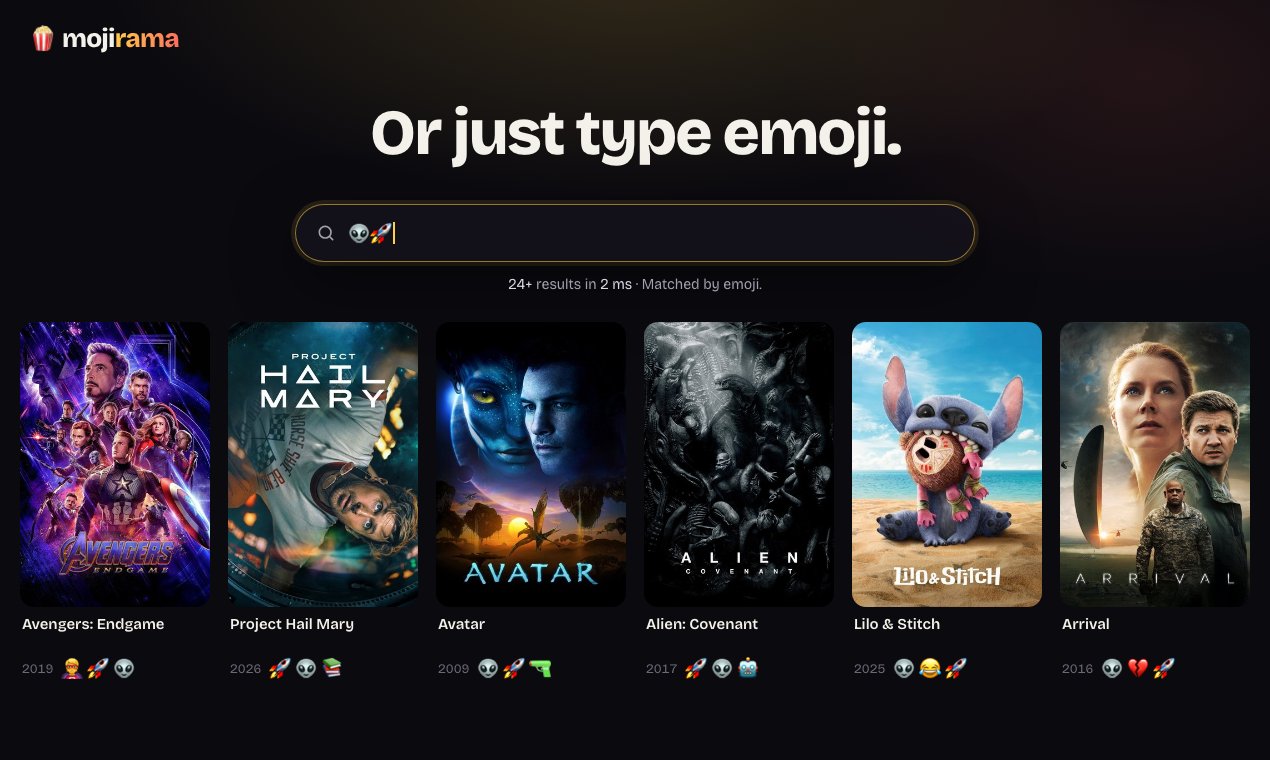
emoji: 👽🚀
1/6 🧵
I've been testing @Google new EmbeddingGemma 2, which launched yesterday, and it is impressive 😅
One open model reads both the text and the posters, and it is small enough to run on my own server.
mojirama.com

A dataset a day until @mostlyrightmd hits 1k users 😁
Today: Airbnb in Prague!
14% of host accounts advertise 62% of listings. The top ten advertise 938.
Built from 29 Inside Airbnb snapshots, with CLEF analyzing listing text.
Story + dataset in replies.

I built a cracked search over 1.26m movies & tv shows with Clef (@Cloudflare) and Jev (@typesafeai) on a @mostlyrightmd dataset, and it's stupid fast
plot: boy befriends alien
actor: tom hanks
character: darth vader
studio: a24
emoji: 👽🚀
1/6 🧵
I used @mostlyrightmd to build the dataset. It joins 16 sources into 1 table: TMDB, Wikidata and Wikipedia. Every title is one row with no duplicates and the dataset refreshes weekly.
We also used Jev (Clef wasn't available at the time) to give each title tags and 3 emojis.
5/6
The dataset is public if you want to build something on it:
mostlyright.md/datasets/movi…
Mojirama goes up on Product Hunt tomorrow. Send me a search it gets wrong before then.
6/6

I built a dataset of 6,000+ @ycombinator companies exits, shutdowns and Form D filings using @mostlyrightmd
I used Jev to check every filing, because matching by name mixes up same-name companies.
Cooking up more datasets. DM me if there's one you need. Link below 👇


GPT-6 Astra + @mostlyrightmd is insane at data engineering 🤯
I asked for 29 years of Czech horse-racing results merged with weather data. It built the dataset fully autonomously.
Need a dataset? DM me. I’ll help you build one for FREE.
This looks interesting from the @sketchapp founders. I'm intrigued.
Miss the design tools space. Maybe I'll come back one day 😄
