
MS/PhD @ Seoul National University.
Joined February 2023
- Tweets295
- Following263
- Followers254
- Likes3.9K



Pinned Tweet
🚀 Excited to share our new preprint: Soohak: A Mathematician-Curated Benchmark for Evaluating Research-level Math Capabilities of LLMs.
To study research-level mathematical reasoning, we introduce Soohak, a benchmark of 439 research-level math problems created from scratch by 64 mathematicians, including 38 faculty members.

Excited to share our #ICML2026 Spotlight 🎉
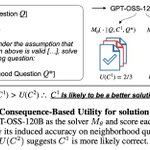
"Judging What We Cannot Solve" — oracle-free evaluation for research-level math.
Models can now *attempt* research math. Verifying those attempts still burns scarce expert time. That's the bottleneck we go after.
If you are interested in handling research-level math with AI come say hi 👋
📍 Poster Session 2, Tue Jul 7, 2:00–3:45 PM

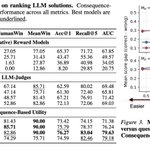
It works. CBU consistently beats reward models, generative RMs, and LLM judges on ranking quality:
• GPT-OSS-120B: Acc@1 67.2→76.3, AUC 71.4→79.6
• GPT-OSS-20B: AUC 69.0→79.2
And it keeps separating correct from wrong even on problems the solver itself usually fails.

This is already how mathematics works. RH is unproven, yet a century of sharp conditional results makes it trusted. Support by consequences.
📄 arxiv.org/abs/2602.06291
👋 Come find us: Poster Session 2 · Tue Jul 7 · 2:00–3:45 PM · COEX, Seoul

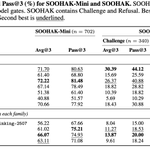
Just updated evaluated models on our previous SOOHAK benchmark! We added GPT-5.5, GLM-5.2, Kimi-2.7, Qwen3.7 and Deepseek-V4-Pro.👍🏻
Despite the interest around GLM-5.2 it doesnt seems to be good at math! (yet)
If you are interested in using Soohak for your evaluations come find me at ICML!
link to leaderboard > soohak-bench.github.io/

Guijin Son retweeted

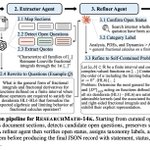
ResearchMath-14K: 14K open research-level math problems
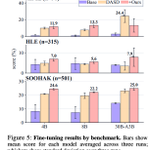
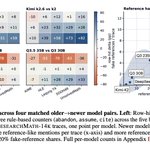
Curated by agents from academic sources, with 220K reasoning traces. Fine-tuning filtered attempts improves Qwen3 by 9.2 points. Newer models also make 5x more fake references.

Guijin Son retweeted

🇰🇷Despite rapid progress in AI agent research, Korean agentic benchmarks remain largely absent!
To narrow this gap, we release K-BrowseComp, a benchmark that requires searching across Korean websites and Korean-language content.
arxiv.org/abs/2606.02404

Guijin Son retweeted

Huge thanks to @minseokwak103 , @dongseok1220 , @gson_AI , @alan_ritter , and @jhkim940331 for their support in writing this work!
We present LaRA (Layer-wise Representation Analysis), a framework for detecting data contamination in RL post-trained LLMs by examining how internal representations change across layers rather than relying on output-level signals such as likelihood or entropy.
huggingface.co/papers/2605.2…

(1/N)
The frontier of mathematics is defined by problems whose solutions are still unknown.
But where do we get prompts at that frontier?
The math literature already contains thousands of open problems 📚
In our recent work, we turn them into 14,056 research-level math problems for LLMs.
Link to dataset:
huggingface.co/datasets/amph…

The surprising part: imperfect attempts still help ✨
Since over 70% of the problems are still open, most traces are unlikely to be correct.
But after filtering out low-quality traces, fine-tuning Qwen3 models improves over the base models by 9.2 points on average.

Thanks to @devpotatopotato, @cartinoe__5930, @MGwak96587 , and @Youngjae4Yu for their help throughout the work.
Link to paper: arxiv.org/abs/2605.28003
Seems like generating cad with agents are attracting attention. But how do you know they are done right?
In our new work we use finite element analysis as verification to test cad-quality!
This quoted post is unavailable.
Creating CAD with LLMs (or agents) is cool but how do you guarantee these outputs are physically sound?
In my recent work with @seonggyung33214 we adopted finite-element analysis to confirm that the Agent-created outputs are sound.
Result? Even the best models fail to create CAD outputs that meet real-world engineering standards. Check out our paper here > arxiv.org/abs/2605.17448


Looks like Frontier Math is in maintenance ⚠️
In the meantime, check out Soohak, our new research-level math dataset!
arxiv.org/abs/2605.09063


If you want your model or agentic harness evaluated on Soohak, please feel free to reach out to me on X or by email at [email protected].
We are also looking for support to run a public leaderboard. If you would like to help with API credits, GPU compute, funding, or infrastructure, we’d be very grateful to chat.
Our goal is to make research-level math evaluation more transparent, rigorous, and useful for the community.
Big thanks to @linguist_cat, @seungonekim, @AkariAsai, @wellecks, @gneubig, and @Youngjae4Yu for their help writing the paper, and to many others who contributed problems, feedback, evaluations, and support throughout the project.
This work would not have been possible without the broader community of mathematicians and researchers who helped shape Soohak.