




Pinned Tweet
for the foreseeable future i’ll be helping build and research ways to optimize inference through heterogeneity @luceboxai
it's gonna be fun. some cool stuff coming soon 😁
bertø retweeted

How does an @AMDGPU_ 32GB R9700 accelerate a model it can’t even fit?
Thanks @cloud_codes for making a really well-made technical breakdown of the Lucebox architecture. Best visual explanation yet of how it actually works.
youtube.com/watch?v=P7Gs-28W…

bertø retweeted

Six months ago we booted up the first @luceboxai prototype (Strix Halo + RTX 3090 + gray chassis).
You can see the excitement (and the 🤝) in the video. We'd thought about this product/company for years, then finally went all in to build it.
Today we're scaling production of Lucebox Zero 495, thanks to our amazing customers. We have many new products lined up for the future.
This is just the start. I’m proud of the team and excited for the future.
bertø retweeted

Our DS4.1 1017 quantizations are already available on day-0, high quality and they can be used on 128GB strix/gorgon halos with only 6GB offloading.
Each Lucebox user will have optimized quants in the machine from tomorrow 🚀
huggingface.co/Lucebox/DeepS…

i've spent quite a bit of time on this, i'm happy with the results.
it's still not perfect but i'm confident it's heading in the right direction
component composability - a distributed system!

1/ Today, we're excited to launch PFlash V2.
If you ask questions over long documents, retrieved passages or a whole codebase on one GPU, reading the prompt can be most of the wait before the first token.
PFlash sits in front of the model and decides which parts of a long prompt the model actually reads. On six public long-context sets it answers 92 of 124 questions against full prefill's 94, while the model reads a median 27% of the prompt, and on one GPU the first token arrives 3.7× sooner on average.
bertø retweeted

LuceBox testing started!
Qwen3.8-27B on with a single AMD Radeon AI PRO R9700 🔥
tool-eval-bench, 97 agentic tool-calling scenarios (hard):
🏆 90/100 ★★★★★ Excellent
⚡ 1.5s median turn, Deployability 85
✅ 100% completion, 3 safety fails
Downloading Qwen3.8 Flash Next R9700 + Strix Halo!

bertø retweeted
A lot of you asked for details on Lucebox clustering.
DeepSeek V4.1 Flash runs at up to 103 tok/s on two 128 GB Luceboxes connected by one 100 GbE link.
A single Lucebox Zero 495 with 192 GB does 54 on the same engine, so that's 1.9x when writing code. Prose after a 2K-token prompt gains less, 56 vs 37.
Each step sends about 95 small messages between the boxes, one after another, so what counts is how fast each one crosses.
Full details on our blog post, link below ⬇️

there is a number that's about to grow, thanks to a clever approach that avoids the usual slowdown…no spoilers 🤫

I've got early access to lucebox-0.10!
Being an early investor has its benefits 😎
Testing Qwen 3.8 27B ~100 toks/s as average!
Gonna connect Pi and test coding soon!
Let's go @luceboxai team! 🚀


gogogo fast!

The first Lucebox Zero 495 batch is almost sold out. Only a few units left at shop.lucebox.com
Huge thank you to every customer who's come through so far. Once batch 1 sells out, new orders move to the next batch at a higher price.
I also updated the image to make pricing clearer, so it now shows the price for each configuration:
- 128GB + 2TB: $5,999
- 192GB + 2TB: $7,999
- 4TB SSD upgrade : +$250
- Cluster kit: +$799 per machine
Every configuration comes with the 32GB Radeon AI PRO R9700, and we've further optimized it for V4.1 Flash with our new quants. Full details in our latest blog post.

bertø retweeted
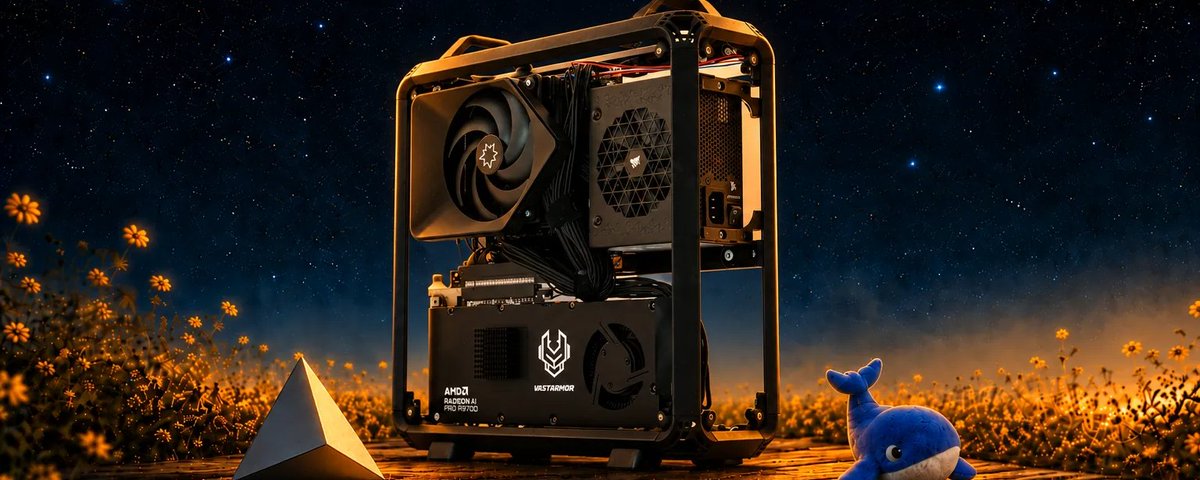
One of the main pieces of feedback we got on the Lucebox Zero 495 is that it's not clear why it matters to have both unified memory and a discrete GPU in the same machine.
It matters a lot. In the article below, we show how the R9700 gets you 3x the speed on a big model like DeepSeek V4.1 Flash.
The Lucebox Zero 495 runs the model across three tiers of memory: the 32 GB on the Radeon AI PRO R9700, the unified memory of the Ryzen AI MAX+ PRO 495, and the SSD.
Each expert lives wherever its usage justifies it. Compared with the same chip without the R9700, a long prompt gets its answer about 3x sooner, and code generation reaches up to 49 tok/s.
Amazing work from: @davideciffa @DeanoC @GeometricAGI @luceboxai
bertø retweeted
For all EU businesses that asked, you can now deduct VAT when purchasing Lucebox on shop.lucebox.com. The value depends on your country.


oh, look at this shiny new thing 👁️
Orders are now open for the new Lucebox Zero 495: shop.lucebox.com/
It’s AMD’s new Ryzen AI MAX+ PRO 495 with up to 192GB of unified memory, plus a 32GB Radeon AI PRO R9700 in the same box.
Lucebox engine split the model by how often each part runs. Dense layers, the hottest experts and the drafter go on the R9700, because nearly every token reads them. The long tail of experts, which most tokens skip, stays in the 495's unified memory. Both chips compute at the same time. 15 tok/s on the 495 alone, 50 with the R9700.
You can get also up to 4TB SSD and 100 GbE cluster kit, installed.
First 200 units are $1,000 off. Deliveries expected in January.


even the testing ones are good-looking
This post reminded me that we have many @luceboxai for testing. We even had to tag them with numbers to recognise them and keep count (great idea from @Salveoo)

bertø retweeted
Btw you can now buy Lucebox with Strix Halo + R9700 (160GB combined, $5999) directly our new website lucebox.com. Sadly, price increase is coming soon.

bertø retweeted

Literally brings me tears to hear these words from my hero.
There absolutely is a reason to accelerate. We have cancer that gives you and your loved ones pain.
We have lack of energy, food, and basic medication in half of the population.
We have serious climate / ocean life crisis, economic / political crisis, and other billion problems that needs smart peoples attention.
But most importantly there are not that many smart people. We need more, but we have population crisis on all developed country. And people want to slow down, its all fine, because *they* live in comfort?
Do mathematicians want to better understand universe to ultimately contribute to real world crisis or not?

my teammates are so good
The R9700 blower is the loudest part of a Lucebox (lucebox.com).
That's why we implemented inference-aware cooling for all Lucebox buyers: On the AMD Radeon AI PRO R9700 we let the model tell the fan what is coming, so the fan spins for the work ahead instead of the heat behind.
Chat runs with the blower at its quietest setting, agent loops at 29% less fan speed, batch work at 25% less, at the same peak temperatures.
crazy stuff tbh
Recently, we worked on something special: pushing ROCm to beat Vulkan on Strix Halo.
Lucebox engine (ROCm) and Llama.cpp (Vulkan) ran on the same Strix Halo on the same day with the same prompt. With the DSpark drafter Lucebox ROCm decodes at 41.9 tok/s at 8K and 38.0 tok/s at 123K prompt tokens.
That is 28% to 47% faster than llama.cpp and Vulkan v0.7.5 running the same drafter and its prefill is 17% to 47% faster 🧵
