





日常焦虑帝 retweeted

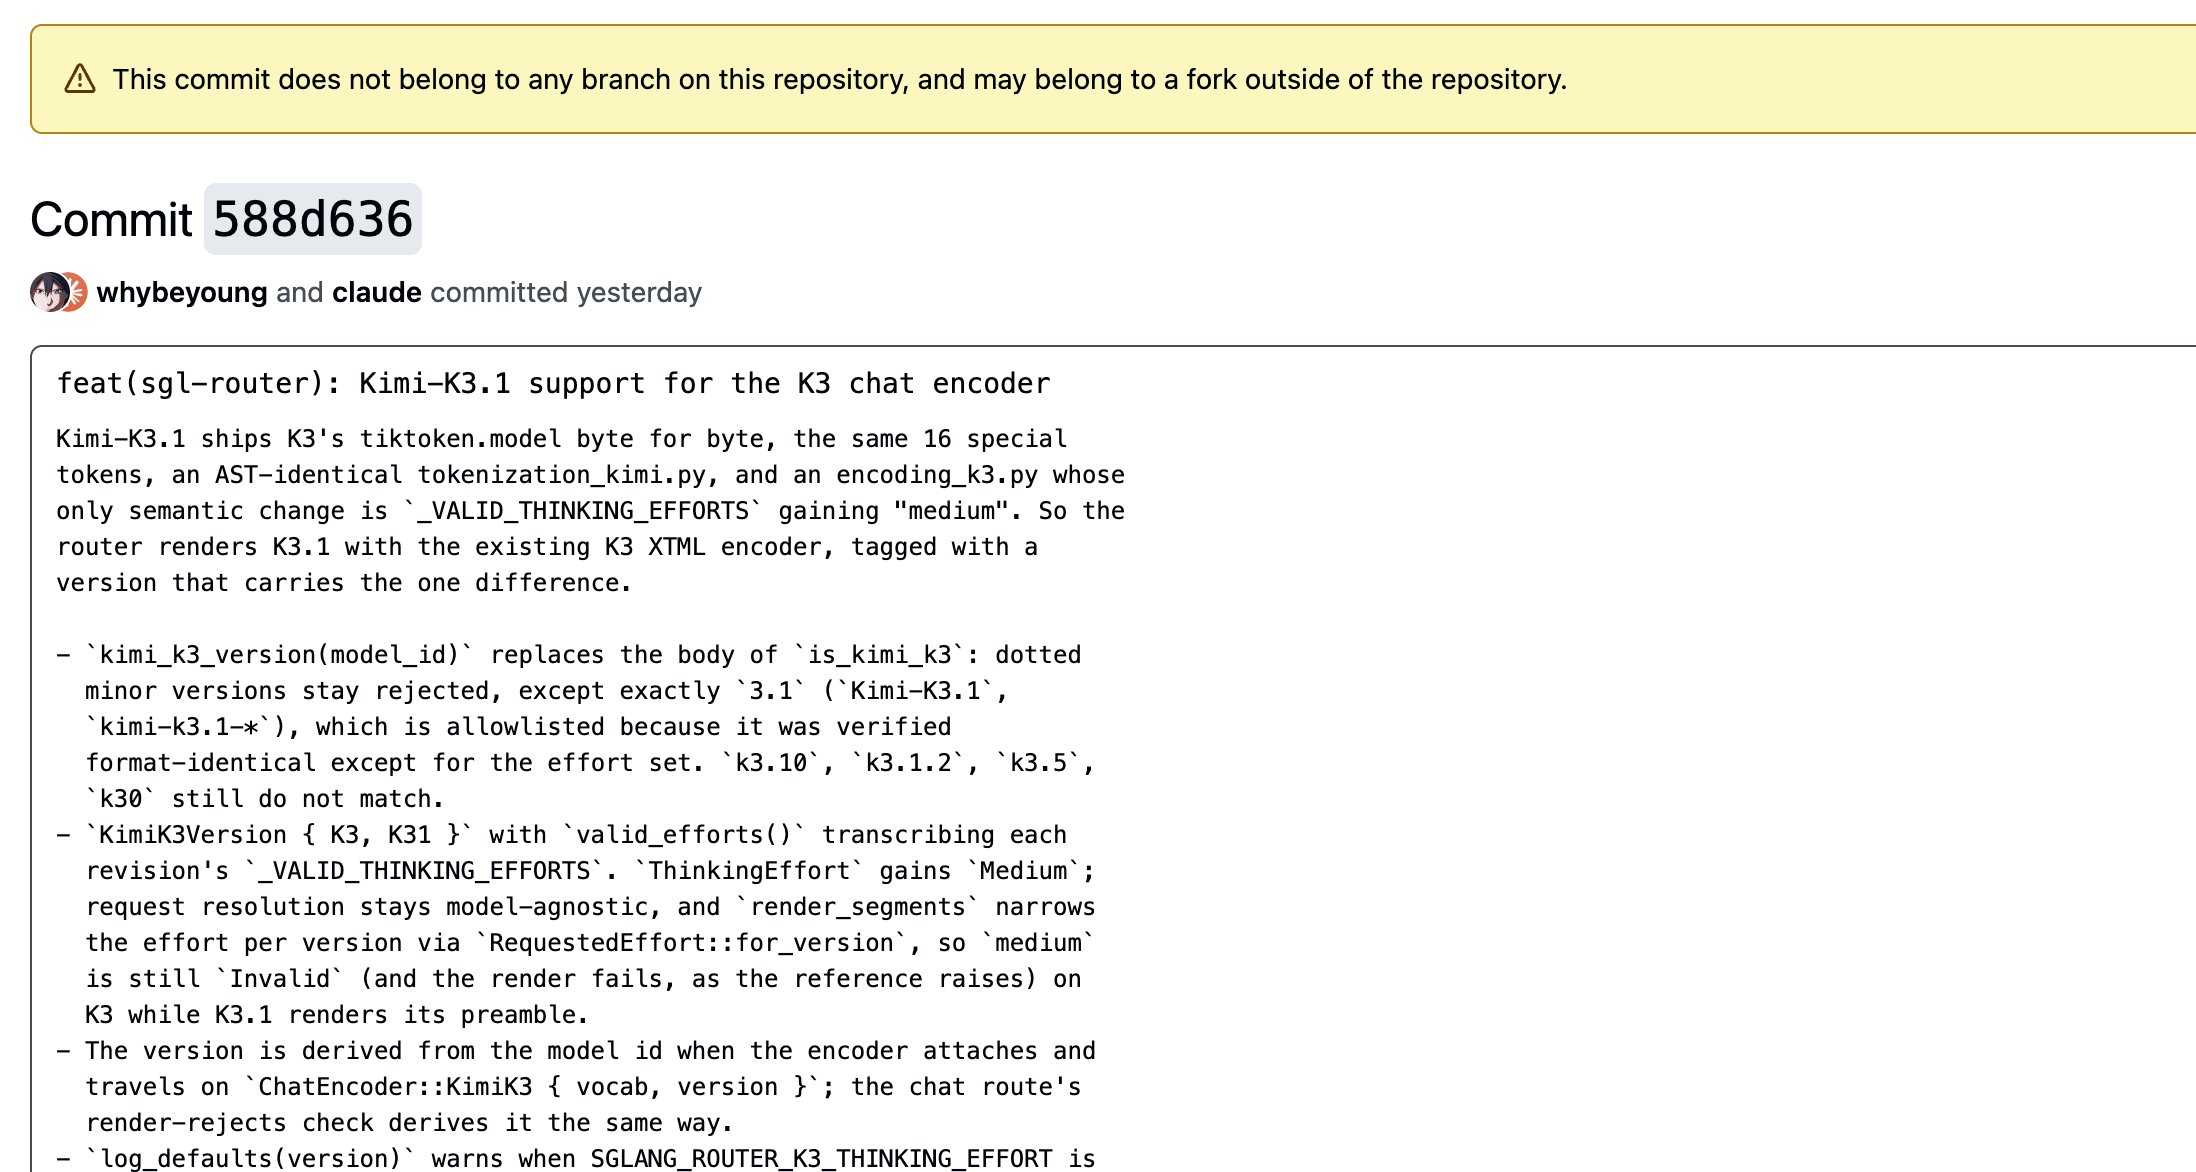
Kimi K3.1 Pro enters MathArena as the best open model (once they release the weights)! Its estimated overall performance is now similar to GPT-5.5 (April 24), putting the open frontier around 6 months behind on MathArena


日常焦虑帝 retweeted

We gave DeepSeek’s updated V4.1-Flash-1017 the same 100 pull requests with known vulnerabilities and an hour per PR to find them in the @BugBunny_ai VulnPR-100 benchmark.
It found 54 for just $7.53, making it the best-performing open-weight model on our leaderboard.
That matches Grok 4.6’s 54 findings at roughly 16× lower review cost. It also finishes only three findings behind Gemini 4 Argon while costing roughly 22× less.
The previous DeepSeek V4.1 Flash found 44 for $12.79. The update catches 10 more vulnerabilities while costing 41% less, bringing the cost down to just $0.14 per vulnerability found.
Better recall, lower cost, and the strongest open-weight result we’ve measured. Seriously impressive work from the @deepseek_ai team.


日常焦虑帝 retweeted

New DeepSeek @deepseek_ai
Oblig @teortaxesTex
DeepSeek-V4.1-Flash-1017
huggingface.co/deepseek-ai/D…

日常焦虑帝 retweeted

The Kimi team is and has been prepping a lunch of there 3.x model for some weeks now.
Many people were trying to claim this model was coming weeks before it was ready. I even debated Nomura on the date of mid-October, but I had redacted it because I originally had read it as arriving by October 15th, which I knew was not going to happen.
We don't have a concrete date yet because the media team hasn't got the media assets ready (or at least quite ready), which is typically indicative of a launch within a couple of days from there. Once I get more information, I'll keep you updated.


日常焦虑帝 retweeted

DeepGEMM Ascend is now open source.
We achieved 99.8% of the hardware limit on GEMM and 98% on MegaMoE.
github.com/deepseek-ai/DeepG…


日常焦虑帝 retweeted

So now we know that before Kirin9050, there only has one N+3 chip: Kirin 9030. (Kirin9030/ Kirin9030 Pro logic die is the same)
It seems that SMIC is still struggling on N+3 process even under small die size.
Kirin9030 chip is roughly ~5M shipping so far (Mate 80 Pro/ ProMax/ RS and Pura X Max). For Kirin9030 die size of 136mm2, one wafer can divide into ~400 chip. So even we assume N+3 yield is as poor as 50%… 5M chip only need 25K wafer in total…
Even we estimate that there should be some stockpile, like extra 3M chip so 8M chip in total, still translate to 40K wafer only.
It seems that Huawei preserve most of its N+3 volume to Mate 90 series.
Mate90 basic/ Pro will use Kirin9030 chip, only ProMax and RS use Kirin9050. We can expect that Kirin9050 volume constrained will be more severe than Kirin9030 on Mate80 (Mate80 Pro use Kirin9030 but Kirin9050 is only for ProMax/RS).
And if we give N+3 process 10K wpm (actually very low) and 1 year manufacturing time, there should be 120K wafer. So ~80K wafer available for Mate90.
10M Kirin9030 chip for Mate90 only need 50K wafer, and 30K wafer can divide into~3.75M Kirin9050 chip under 25% yield (considering the combination of package yield, and Kirin9050 die size is ~114mm2).
Actually, I do not think Huawei now have 10M Kirin9030 chip/ 3.75M Kirin9050 chip for Mate80, so my calculations assumption condition should be lower- either the capacity (10k wpm) or the yield (50% for Kirin9030 and 25% for Kirin9050).
No matter which one, it means SMIC still need to take a long road to increase the yield or output of the N+3 process even on small die.
I do not expect that we can see the large ASIC/HPC die size chip on N+3 for soon.
Ascend series chip will use logicfolding by 2030, perhaps we can also see the large AI chip with N+3 process by that time?
Remember, steady and large amount of N+2 Ascend chip shipping is occurring on Ascend 950 with 0.5x mask size, three years after first SoC chip Kirin9000s was shipped. As for more challenging N+3, it may take longer time.

Shocking, Kirin 9030S is N+2, not N+3….
—————————
Mobile: Pura 90 Pro Max
Die size: 122 mm2
Marker: Hi36D0G-GPCV100
CPP:63nm
Cell height: 252nm
SRAM cell area: 0.0315
——————————
Btw, Kirin 9050 Pro decap is on-going, and it is a chip using N+3 bond with N+2.
Die size is even smaller than Kirin 9030S, hence far smaller than Kirin 9030.
日常焦虑帝 retweeted
Shocking, Kirin 9030S is N+2, not N+3….
—————————
Mobile: Pura 90 Pro Max
Die size: 122 mm2
Marker: Hi36D0G-GPCV100
CPP:63nm
Cell height: 252nm
SRAM cell area: 0.0315
——————————
Btw, Kirin 9050 Pro decap is on-going, and it is a chip using N+3 bond with N+2.
Die size is even smaller than Kirin 9030S, hence far smaller than Kirin 9030.


日常焦虑帝 retweeted
Hi Dario and Sam 👋
If you want to slow down your AI development, feel free to do it. Anyone preventing you?
Slow down, stop, or even shut down your AI. Why do you need the government to intervene?*
*Answer: To stop your emerging competitors.


日常焦虑帝 retweeted

Xiaomi-Robotics-U0 is now fully open source. 🤖
We’re releasing the Xiaomi-Robotics-U0 World Model training and inference framework, and model weights in 4B and 34B, supporting:
• Embodied scene generation & editing
• Single-image generation & image editing
• Video generation
• Interleaved vision-language sequence generation
We hope this open release lowers the barrier to experimentation and accelerates the exploration and real-world application of world models in robotics.
Website:robotics.xiaomi.com/xiaomi-r…
GitHub:github.com/XiaomiRobotics/Xi…
Hugging Face:huggingface.co/collections/X…
#Robotics #EmbodiedAI #WorldModel #XiaomiAI #XiaomiRobotics

日常焦虑帝 retweeted

🚀 AuK is officially here. Nano banana🍌 for audio
An open-source foundation model for unified speech generation and editing.
Natural-language instructions + reference audio. One interface.
Zero-shot TTS. Instruction-controlled generation. Content editing. Whisper-conversion. De-accent. Timbre/style/emotion edit. Speed/Pitch control. Enhancement, denoising, multi-speaker and music separation.
Also releasing AuK-Flash: 4-step inference. ~4.5× faster under matched conditions.
Code, weights, and demo are live. Try it and share your feedback.
🤗 Paper & upvote: huggingface.co/papers/2609.0…
⭐ GitHub & star: github.com/Tencent-Hunyuan/A…