


Pinned Tweet
Transformers use the same hidden state for two competing roles: maintaining state and predicting the next token. 🔀
Splitting these roles into two separate streams outperforms standard Transformers.
Introducing the State-Prediction Separation (SPS) Transformer.
🧵

Yet another banger paper from Nathan :)
It's been a lot of fun hearing day after day about how powerful his new Copy-Paste Language Models are despite their simplicity, and how effective they are at handling long contexts

⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247

Giovanni Monea retweeted

"The Surprising Effectiveness of Shared Memory in Looped Transformers"
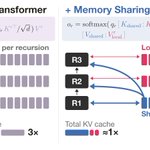
Each loop for looped transformers still maintains its own KV cache, which leads to a growing memory.
This paper introduces Looped Prediction Transformers, where the first loop builds a shared KV cache, while later loops reuse it and keep only a small local window.
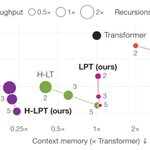
Surprisingly, sharing memory also improves model quality. At five loops, the hybrid model achieves lower perplexity and higher downstream accuracy than a standard Transformer of the same size, using 76-79% less context memory, though at roughly 3-3.5x the inference compute.
alphaxiv.org/abs/2610.02383

Giovanni Monea retweeted

The Surprising Effectiveness of Shared Memory in Looped Transformers
Pretraining looped transformers to share memory across recursions cuts context memory by 76-79% while improving quality over standard transformers at 150M-1B parameters.
arxivb.org/abs/2610.02383

Giovanni Monea retweeted

In the memory constrained world we are running into, these kinds of insights are key.

⚠️ Stop pretraining your looped Transformer with a separate KV cache per recursion!
In our recent preprint, we show that *memory sharing* not only saves memory but is also a net-positive inductive bias!
Less memory, same flops, higher quality.
🔗 arxiv.org/abs/2610.02383
🧵

Very excited to finally share my IBM internship work. It was an intense but rewarding summer (with very nice views), and I had a blast working with my talented collaborators at IBM & Cornell (@KeshavRamji @yelkurdi, @lastrasl @yoavartzi @nthngdy @RamonAstudill12)

So, what does memory sharing bring to the table to *improve* quality?
Prediction recursions attend heavily to the shared memory. Each read sends a gradient signal back to the state recursion.
We find that this "gradient highway" makes the state recursion learn much more.

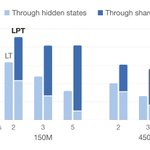
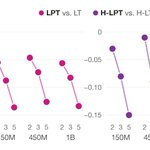
We train LPT and Hybrid LPT at 150M-1B parameters, on 20-50B tokens at 2, 3, and 5 recursions. The more recursions, the more our memory-sharing models outperform their respective baselines.

Prior work laid the foundation for looped models and reduced their extra memory at inference. The result? Surprisingly strong despite the train-test mismatch.
That made us ask: could this be a good inductive bias? One recursion memorizes, the others reuse it to predict.

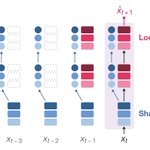
What is memory sharing? Our simple recipe: at later recursions, just concatenate the attention keys of the first recursion and those of the current recursion before performing standard attention.
Then, restrict the later recursions to a short window for memory savings.

Sharing memory makes looping cheaper and better.
At 1B with 5 recursions, H-LPT beats a same-size Transformer by 1.1 perplexity with 76% less memory. Locally, it's easier to fit on your GPU. For serving, it fits 3.6x bigger batches and keeps 81% of the Transformer's throughput.

⚠️ Stop pretraining your looped Transformer with a separate KV cache per recursion!
In our recent preprint, we show that *memory sharing* not only saves memory but is also a net-positive inductive bias!
Less memory, same flops, higher quality.
🔗 arxiv.org/abs/2610.02383
🧵

