




HipAI retweeted

Every builder is using a Karpathy LLM wiki 🧠
Setup is quick, but keeping it current and honest never stops.
Here's the trick:
I built a @getHipAI context graph and instantly 10x'd my work, by doing what claude+obsidian can't alone.
How it works + get 2M free tokens 👇
A LLM wiki and a HipAI context graph aren't competitors, they solve different problems.
The wiki distills, while a graph keeps up with constantly changing context, and cites answers back to the original source!
Real setups need both. Ready to build your first graph?

Every builder is using a Karpathy LLM wiki 🧠
Setup is quick, but keeping it current and honest never stops.
Here's the trick:
I built a @getHipAI context graph and instantly 10x'd my work, by doing what claude+obsidian can't alone.
How it works + get 2M free tokens 👇
HipAI retweeted
tl;dr - I didn't replace my wiki, I gave it a @gethipai context graph as a constant gardener and let it carry the load.
It's not too long of a read though, tap in builders 👇
HipAI retweeted

Ethan decided to work with us because his Karpathy-style second brain was too maintenance heavy and drifted from the truth. @gethipai is now the backbone of his second brain. We're giving away 2M tokens for you to build one for your personal/project/company brain. Reply if interested! 🦛
The release of Genie Ontology by @databricks proves the ontology layer is missing, and it is one of the next huge bets for AI. But, Genie Ontology is only for Databricks. Our layer will work with any data cloud, structured & unstructured data, and any model.


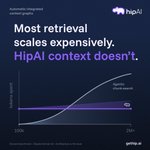
This Discord data is ~150k tokens at one year old.
Agentic chunk-scan scales linearly with corpus size.
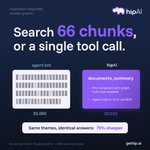
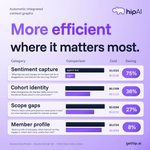
Graph traversal stays flat or grows much more slowly and the synthesis / cohort savings get bigger the more data you stack.
In our next demo:
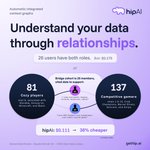
Multiple platforms in one @gethipai graph to showing how connections compound and support deep, effective, and accurate work for teams.

we will treat your neurons as if they were our own @lorepunk

HipAI retweeted
Company Brain
@t_blom
Every company has critical know-how scattered across people's heads, old Slack threads, support tickets, and databases, and AI agents can't operate like that.
We think every company in the world is going to need a new primitive: a living map of how the company works that turns its own artifacts into an executable skills file for AI.

HipAI retweeted
The right context memory layer loop + my new context graph is letting me do things I never thought possible.
No install, just connect. Automatically built and auto-maintained
and free btw, if you get accepted on waitlist 😏

This impressive work validates that the architecture we chose is the best of both worlds: “a semantic layer for generalisation and retrieval by concept, coupled with an external verification layer that provides exact episodic grounding”

There’s been a lot of talk about filesystems as the better path for agent and long-term memory, and that intuition is correct.
We present a no-escape theorem proving exactly why: any memory system that retrieves by meaning (RAG, knowledge graphs, embeddings, parametric memory) will inevitably forget and produce false recall as it grows.
File systems are the only architecture that fully escapes this. @karpathy @garrytan