

4A turns the chaotic web into a clean, scalable & actionable dataset. One API call. Any website. Smart proxy rotation, anti-bot bypass, real-time monitoring.
Sofia, Bulgaria
Joined April 2026
- Tweets23
- Following72
- Followers8
- Likes31
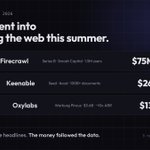




Full write-up by The Web Scraping Club: scraping.club/p/google-remov… (numbers from Nozzle via PPC Land)

6
Google hides result URLs behind redirect tokens since August.
Checking one keyword’s top-100 ranking:
- Before Sept 2025: 1 request
- After 100-per-page ended: about 10
- Today: 500 to 1,000
1
6
This summer $231M went into collecting the web for AI.
- Collection: Oxylabs, $130M from Warburg at $3.6B (~10x ARR)
- Index: Keenable, $26M seed, Accel
- Knowledge: Firecrawl, $75M Series B, 1.5M users
...money followed the data.

22
Zyte audited 24,898 sites: 81.5% now run an access barrier.
88% are still Simple.
The web didn't close, but it got a price gradient. Fashion 2.86, retail 2.60, real estate 2.37 vs a 1.58 average.
Sites defend in proportion to what their data is worth (zyte.com/sowa/2026/industry/).

13
Oxylabs just raised $130M at $3.6B. Bright Data claimed a $300M+ ARR. The mid-market scraping API is disappearing.
A few questions we raise: foura.ai/blog/web-scraping-c…

1
18
App store data looks simple from the outside. It's public. Apple hands out most of it through their old iTunes JSON lookup. Google Play renders it in a browser. How hard can it be?
Read the entire case study at: foura.ai/blog/app-store-inte…

15
Cloudflare just shipped Precursor, and it effectively kills the oldest trick in web scraping.
It stops judging just the landing request and starts scoring the whole session behaviourally like mouse arcs, keystroke timing, human hand tremors.
The bot score now follows the session. Refreshing, rotating identity, and starting over doesn't reset a thing.
Proxy rotation and header fuzzing were built for a world where the unit of detection was a single request. Now? The defenders are looking at 5-minute behavioral coherence.
The real question isn't whether detection evolves. It's whether your stack is still thinking in requests.
Full teardown on what this means for data infra: foura.ai/blog/cloudflare-pre…

34
Every "agents are getting smarter" thread we've seen, argues about model IQ.
But run them in production and the real bottleneck isn't IQ, but the network.
The moment an AI agent hits a login wall, an anti-bot challenge, or a rate limit, it fails silently. It still burns tokens, loops retries, and happily reports partial garbage as a successful outcome.
17

Full math, incl. where LLM extraction DOES earn its bill (unstable layouts, long-tail targets, summarization-shaped output): foura.ai/blog/llm-extraction…

1
11
LLM-extracting every page is demo architecture.
At 100K pages/day it's ~$11K/mo in GPT-4o tokens — for JSON that CSS selectors produce for free. Plus 3–5% confidently wrong records.
The production pattern: LLM writes the selector once, code parses the rest. ~36x cheaper.

1
1
46
4А retweeted

Artifacts in Claude Code are now also available on Pro and Max plans.
Ask for an artifact, Claude writes the code, publishes it live to claude.ai, and updates it in real time while it keeps working. Pages are private to your account and fully self-contained.

The Korea Timber Index is a massive leading indicator for the global supply chain, but tracking it manually is a logistical nightmare.
Here is how we engineered an automated data pipeline to parse and monitor foreign commodity indexes on autopilot: foura.ai/blog/korena-timber-…

ALT Source: https://korena.eu/
2
107
Company career pages are just indexes. The actual data you want is buried inside highly fragmented ATS platforms.
If you're building a job board, traditional web scraping will break on day one.
Use a single smart schema into structured JSON on autopilot:foura.ai/blog/job-board-scra…

1
17
Your RAG pipeline isn't broken because of your LLM. It’s broken because your web crawler is serving it stale data.
The "Recrawl" problem is the silent killer of production AI applications.
Our way to fix data freshness: foura.ai/blog/recrawl-proble…

1
9
