
Read and control interactive stories Talk to writers. Suggest your own ideas and debate with other fans. Vote for what happens next.
Joined November 2012
- Tweets449
- Following36
- Followers949
- Likes166

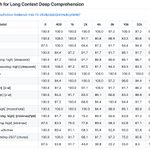


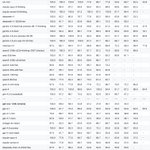


Had to add gemini-3-flash-preview to the results.
It dominates.
Clearly the top model on this benchmark.
Hopefully we can get a v2 of this bench out sometime soon.


Long context eval.
Huge improvement since last year. The frontier models went from poor to great.
An exciting standout is kimi-2.5. It made impressive progress without (presumably) a new architecture, putting up gemini-2.5-pro numbers which we were all impressed by last year.

claude-opus-4-5 fixed claude's long context performance, it is now good when previously it was a laggard. claude-sonnet-4-5 had a regression compared to sonnet 4… Same tier as grok-4.
Kimi-k2.5 now the Chinese/Open-source leader!
Minimax???
gpt-5.2 improves on almost perfection in gpt-5 to now very close to perfect. gpt-5.2-pro did surprisingly poorly.


Fiction.LiveBench for Long Context Deep Comprehension adds: deepseek-v3.2-exp [reasoning: high], deepseek-v3.2-exp, nemotron-nano-9b-v2:free, qwen-max, qwen3-next-80b-a3b-instruct.

Long context tested for Qwen3-next-80b-a3b-thinking.
Performs very similarly to qwen3-30b-a3b-thinking-2507 and far behind qwen3-235b-a22b.

Tested sonoma-sky-alpha and sonoma-dusk-alpha @openrouter on Fiction.liveBench
sky is frontier level! If this is an efficient version that can be served cheaply, that's a fantastic outcome with great performance. Very impressed by this.

