

Accelerating LLMs @Basetenco - long-context and embedding inference (https://xitter.cf/t.co/IdBf5U7mS3) - opinions are my own.
San Francisco, CA
Joined February 2024
- Tweets142
- Following157
- Followers527
- Likes848


While working on GLM5.2 chat-templating for Basetenkenizer, found a small bug, thats now fixed with latest minijinja 2.22 (xitter.cf/feilsystem/status/2081…) and will render the chat-template correctly. Will be included in future releases.
github.com/mitsuhiko/minijin…



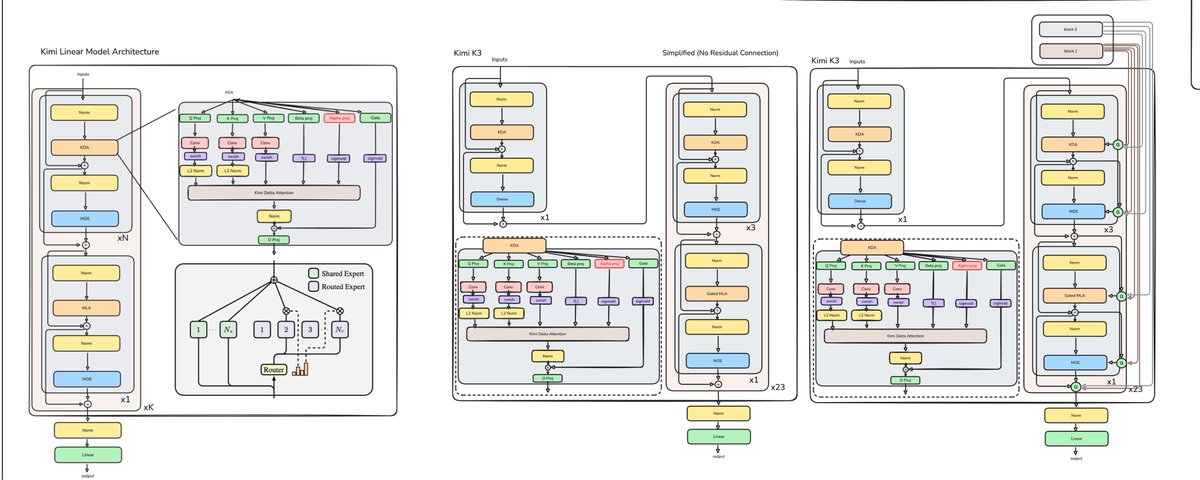
We shipped the worlds fastest tokenizer for KimiK3. Basetenkenizer now available on day 0 on Baseten and on pypi.


Michael Feil retweeted

@baseten model performance team is absolutely cracked. @Zai_org GLM 5.2 is now 4x faster running at full 1M context!
Already available to use in your favorite coding harnesses, here it is COOKING in @FactoryAI Droid and @opencode
Docs for how to get it in comments
Michael Feil retweeted
Biotech R&D is generating more scientific AI models than ever, from protein structure prediction to molecular docking to sequence analysis. But the infrastructure to run them hasn't kept up.
Today we're announcing Benchling Inference, powered by Baseten. Together with @benchling, we're delivering on-demand GPU capacity built for the bursty, high-stakes demands of scientific workloads. With Benchling Inference, scientists can:
→ Deploy models in seconds, not weeks
→ Keep proprietary models inside their VPC if needed
→ Benefit from economics that work even at small and mid-size biotech scale
Benchling and Baseten decided to team up because we believe that research teams shouldn't have to manage HPC queues, negotiate cloud contracts, or become GPU experts to run frontier models on their own data.
Six years of inference expertise are now available where science happens.
Read more here: benchling.com/blog/announcin…


Michael Feil retweeted

OpenAI is shutting down text-embedding-3-small?!?
I strongly believe that if you shut down a closed-source embedding model that you should open-source. Imaging the trillions of tokens that will no longer be queryable.
cc @romainhuet


lets go baseten -- rooting for you.

We are excited to have @baseten as a day 0 launch partner for Kimi K2.6!
Their inference stack brings KV-aware routing, NVFP4 on Blackwell, multi-modal hierarchical caching, and prefill-decode disaggregation, so K2.6 runs the way it's meant to in production.
Try it out at: baseten.co/library/kimi-k26

Michael Feil retweeted
why join a dense team when you can join an moe team @baseten

we're a dense team of 10 jane street engineers, ioi medalists, and sunshine enjoyers down in palo alto.
user numbers up >1,000% since partnering with @fraser
still early, dm me something exceptional you've done if u wanna join!
Named Entity Recognition is a core workload used by Search and Healthcare companies to filter queries and anonymize queries.
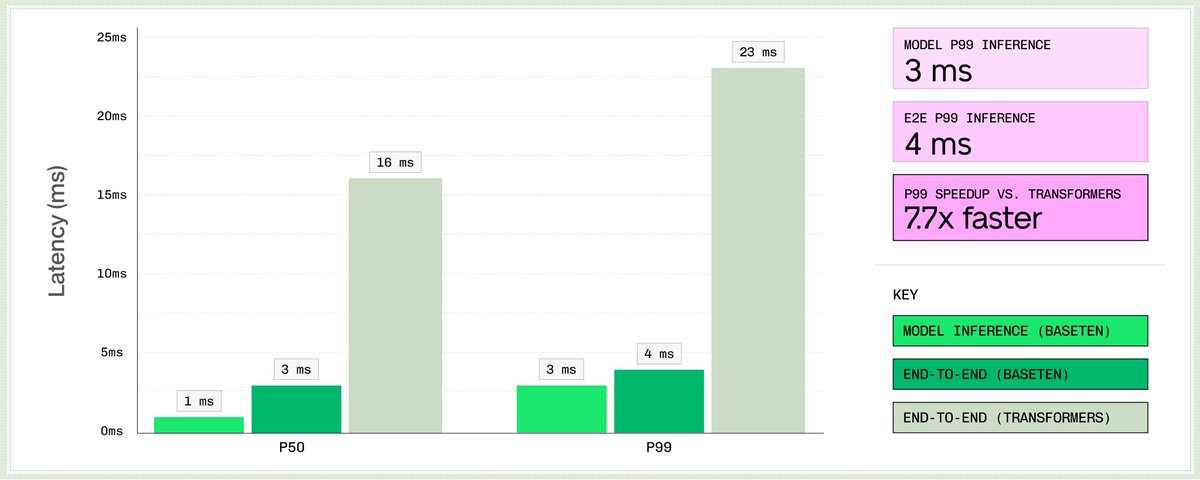
We shipped the fastest inference on the market: 1 ms P50 and 3 ms P99 server-side latency, 7.7x faster than an optimized PyTorch baseline, fixing several bottenecks: HTTP parsing, networking, load-balancing.
Michael Feil retweeted

Over 1 million clinical questions hit OpenEvidence every day. More than half the practicing physicians in the US rely on us at the point of care, mid-decision, with a patient in front of them. Downtime in that moment has real consequences.
We partner with @baseten for our inference infrastructure to make sure answers are always there when physicians need them. They stopped by our office to talk about what that looks like under the hood.
Really good blog by the dynamo and crusoe team. crusoe.ai/resources/blog/red…. tl;dr: Ported some of the learnings back to hf/tokenizers. github.com/huggingface/token… github.com/huggingface/token… at the scale of transformers, will save probably save M$ if done right. @art_zucker.
Making the token+position a u64 is a good idea for lookups, e.g. I did this also a couple of times. github.com/michaelfeil/radix…
I cross compiled the package from the blog post, so `pip install fastokens-b10` is a thing.
