




😷 ➡️ @FabienTarrade@sigmoid.social retweeted

Building the next frontier of AI requires exceptional technical leadership. We’re hiring a Research Scientist (Director+) to join the Frontier AI team at @GoogleDeepMind in Zurich 🇨🇭.
Apply here: google.com/about/careers/app…
😷 ➡️ @FabienTarrade@sigmoid.social retweeted

We launched on possibly the worst timing ever - right when OpenAI, Google DeepMind, and Anthropic all had major releases. Somehow we still made it to #1 on Hacker News. Thanks to everyone who checked us out! 🙏

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

Last year we launched the Swiss AI red-teaming network with @ETH @EPFL and multiple companies
We started off with discussing pragmatic prompt injection defenses
We compiled our thoughts into a list of "design patterns" that we think can be effective in many practical settings

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

You're in Zurich or its zone of influence (Lausanne, Paris, BXL, Munich, London, ...) and like AI + Robots?
We (@openai) together with @mimicrobotics, @lokirobotics, and Zurich Builds are organizing a hackathon from Fri 9 May afternoon to Sun 11.
Limited spots, more below:

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

Sam and I did a deep dive into some of our recent results, discussing how language models plan, perform computations, and reason across languages!
If you use LLMs like Claude and want to know how they work, I recommend giving it a listen. No technical background needed!

In this episode, @mlpowered (Emmanuel Ameisen), a research engineer at @AnthropicAI, returns to discuss two recent papers: "Circuit Tracing: Revealing Language Model Computational Graphs" and "On the Biology of a Large Language Model." Emmanuel explains how his team developed mechanistic interpretability methods to understand the internal workings of Claude by replacing dense neural network components with sparse, interpretable alternatives. The conversation explores several fascinating discoveries about large language models, including how they plan ahead when writing poetry (selecting the rhyming word "rabbit" before crafting the sentence leading to it), perform mathematical calculations using unique algorithms, and process concepts across multiple languages using shared neural representations. Emmanuel details how the team can intervene in model behavior by manipulating specific neural pathways, revealing how concepts are distributed throughout the network's MLPs and attention mechanisms. The discussion highlights both capabilities and limitations of LLMs, showing how hallucinations occur through separate recognition and recall circuits, and demonstrates why chain-of-thought explanations aren't always faithful representations of the model's actual reasoning. This research ultimately supports Anthropic's safety strategy by providing a deeper understanding of how these AI systems actually work.
🎧 / 🎥 Listen or watch the full episode on our page: twimlai.com/go/727.
📖 CHAPTERS
===============================
00:00 - Introduction
6:13 - Surprising findings
10:05 - Circuit Tracing paper: Mechanistic interpretability
16:07 - Similarity of concept embeddings with model concept representation
23:00 - Replacement model and sparse coding
27:58 - Trade-offs between different replacement models
35:38 - Challenges of upstilling black box model into an interpretable model
41:23 - Polysemanticity and superposition
44:22 - Limitations of the model approach
50:53 - Attribution graph
53:32 - Interventions
1:05:53 - Understanding the model strategies
1:12:26 - Examples from the Biology paper
1:20:36 - Chain-of-thought faithfulness
1:25:49 - Future directions

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

Swiss Python Summit Early Bird Alert! 🇨🇭🐍🎉
Get your tickets on python-summit.ch/ before it's too late and save up to 40%! 🤩
#python #pythonsummit #EarlyBird #Discount
😷 ➡️ @FabienTarrade@sigmoid.social retweeted

If you remember our Applied LLMs course, you'll love this. Today, we are making all these resources available for free to everyone! 📚
We did extra work to add learning tracks, resources, and notes to each lesson to maximize your learning. Link in next tweet

Maybe you should check this default setting and fix it !
This Post is from an account that no longer exists. Learn more
😷 ➡️ @FabienTarrade@sigmoid.social retweeted

"The little book of Deep Learning" update v1.2!
Minor updates ("meta-parameter" -> "hyper-parameter") + fine-tuning in 3.6 + a new chapter 8.
Draft below, comments are welcome.


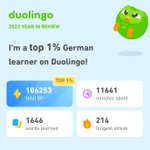
I’ve joined the Streak Society, Duolingo’s most exclusive club. Get a 365 day streak to join me! #DuoStreakSociety

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

The "Self-Extend" paper arxiv.org/abs/2401.01325 promises magic for your LLMs: extending the context window beyond what they were trained on. You can take an LLM trained on 2000 token sequences, feed it 5000 tokens and expect it to work. Thread 🧵
(SWA below=sliding window attn.)

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

We just released Mixtral 8x7B paper on Arxiv:
arxiv.org/abs/2401.04088

😷 ➡️ @FabienTarrade@sigmoid.social retweeted

Thanks, everyone, for all the support and positive words for my "Build a Large Language Model (from Scratch)" book!
The next chapter on *coding self-attention, multi-head attention, and causal self-attention from scratch* is on the way and will be in the MEAP in a few weeks!
For a sneak peek, you can find the code (along with short notes here): github.com/rasbt/LLMs-from-s….


One of the best ways to understand LLMs is to code one from scratch!
Last summer, I started working on a new book, "Build a Large Language Model (from Scratch)": manning.com/books/build-a-la…
I'm excited to share that the first chapters are now available via Manning's early access program if you are looking to read something over the holidays or pick up a new project in 2024!
In short, in this book, I'll guide you step by step through creating your own LLM, explaining each stage with clear text, diagrams, and examples.
This includes Implementing the data preparation, sampling, and tokenization pipeline:
1. Coding multi-head attention from the ground up
2. Building and pretraining a GPT-like model
3. Learning how to load pretrained weights
4. Finetuning the model for classification
5. Instruction-finetuning the model with direct preference optimization
PS: The code implementations are in PyTorch.
Don't hesitate to reach out if you have any questions!

I would like to wish you all a very happy, healthy, and prosperous New Year 2024 with the best success in your projects. May it be full of peace, joy, love and success for you and your loved ones.
🎆🥂
😷 ➡️ @FabienTarrade@sigmoid.social retweeted

We release today the final Open Assistant dataset with data collected on open-assistant.io until Nov 5, 2023.
OASST2: huggingface.co/datasets/Open…
Thanks again everyone who contributed to the project! It was a pleasure to work with all of you.
Happy holidays! 💙🎅
😷 ➡️ @FabienTarrade@sigmoid.social retweeted

We're excited about all the interest in our Gemini report and working to make it even better!
This week we made major improvements, switching to the @MistralAI instruct model, and working with the Gemini team to reproduce their results. Updates below.

Google’s Gemini recently made waves as a major competitor to OpenAI’s GPT. Exciting! But we wondered:
How good is Gemini really?
At CMU, we performed an impartial, in-depth, and reproducible study comparing Gemini, GPT, and Mixtral.
Paper: arxiv.org/abs/2312.11444
🧵
