

Trying to solve sample efficiency prev: Engineering physics @iitbombay '23
Joined June 2023
- Tweets769
- Following624
- Followers4.1K
- Likes2.6K



Pinned Tweet
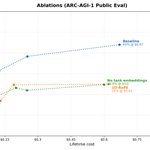
44% on ARC-AGI-1 in 67 cents!
Trained from scratch in 2hrs on a 5090
Matches TRM, beats HRM and is way faster & cheaper
No recursion, just a transformer
Also, 7% on ARC-2 🧵

Wrong. Humans will do economically useful work DESPITE ASI being better at everything
Tldr: Doesn't matter that a robot can kick a ball farther than any human. I will still enjoy my human team doing it better than the other stupid human team
The disempowerment view stems from a snobbish and wrong understanding of what is "economically valuable" work
The economy is ultimately driven by human desires that evolution RLed into our nerves. Thats it. It is a metasystem that values and rewards work based on how many reward circuits it cumulatively fires among all humans. We're already a superorganism that way.
There's no inherent value in doing innovative or tech stuff other than us setting up metasytems that reward it abnormally high (eg: money through VCs and moral high status through sociological metasystems) bc the large amount of reward circuits firing bc of it
Why does sports have so much money? Because we have been RLed like crazy into being tribalistic. Anytime your tribe does well, or the other tribe does bad, you feel great.
We are also RLed to do this to be tribalistic about arbitrarily abstract ideas like theories, companies, even ideas themselves. Youll see this on the internet in crazy fandom wars, wikipedia edit wars.
ASI is one of the grand prizes that the economic engine has been driving humanity to collectively and unknowingly build (yes there are more grand prizes!). This entity can finally solve all the negative reward producing problems that humans are not smart enough to solve.
But this doesnt mean we have to build ASI in the form of an all-controlling god in a box!! We dont need to disempower ourselves!!
We do have a choice. We can find a way to get all the benefits of ASI AND keep our freedom AND minimise the downsides
And it isnt hopeless. People like Elon and Ilya have showed us that single individuals can change the path of the human superorganism.
If you dont like the ASI vision someone else is building, then build your own! Be ambitious and take that shot.

I now type "explain in easy to understand language" 100s of times a week
Weird way to experience jevon's paradox
Mithil Vakde retweeted

Ninth update to OpenAI problem #109 (integer multiplication): we are now past 2^-12.
κ = 2⁻¹¹·⁰⁶⁶ (tightened from κ = 2⁻¹⁸²)
The exact witness is 4.6637 × 10⁻⁴, about 3.70 fold over our previous 1.2613 × 10⁻⁴, and a 2¹⁷⁰ fold improvement over the original OAI result.

Eighth update to OpenAI problem #109 (integer multiplication): we are now past 2^-13.
κ > 2⁻¹³ (tightened from κ = 2⁻¹⁸²)
The exact witness is 1.2613 × 10⁻⁴, about 1.97 fold over our previous 6.397 × 10⁻⁵, and a 2¹⁶⁹ fold improvement over the original OAI result.
Mithil Vakde retweeted
I think one of the hard things AI is going to do is force a lot of people to look at why human beings do things. Hard because ultimately we do most of what we do, including many beautiful things, as some form of status seeking.
Mithil Vakde retweeted

I think I just trained NanoGPT in 9.65 seconds!?
Yesterday, @hermanbrunborg used a connected longest exact match model, trained concurrently on CPU, to get the nanoGPT record from 39.9 seconds to 21.5 seconds, in an impressive open PR. By adapting their work, and generalizing the CPU model to a larger share of the tokens, I got the record down to 9.65 seconds, and submitted the PR this morning.
I built on three open PRs, in addition to my contributions: the main basis for my generalization was from @hermanbrunborg, and additional work from @nthngdy, @cyrusghane, and Daniel Monroe. Their engineering is extremely impressive.
Of course, all of our records are still subject to review. As I mentioned in my comment on Herman‘s PR (and in my own PR description), CPU usage is a gray area in nanoGPT. Their PR was the first to discover a clever way to effectively use CPU during the run, so I’m looking forward to the official reviews.
This was another very fun challenge! Particularly (potentially) breaking the 10 second barrier yesterday. So much engineering tact is yet to be explored.
Huge shoutout to the three authors of the PRs for their innovations.
@hermanbrunborg - I will also be at stanford for the weekend along with some of my cofounders, and sf for a couple days after, would love to chat more IRL, if you’d be open 🙂
engineering physics gives you the best of both worlds :)

The future light cone of discoveries rounds up to 100% engineering, as the set of physics rules that govern our reality is very tiny compared to what can be done with those rules.
The reason I didn’t choose a career in physics, my favorite subject, is that I would be stuck waiting for a new collider or telescope. Better to advance technologies that ultimately enable discovery of new physics.
Mithil Vakde retweeted

After seven years, I've made the hard decision to leave Google Deepmind.
I joined Google in 2019 because I believed we could make build models to understand and generate code.
Back then, very few people had that conviction. I’m glad I found those people at Google and that we worked hard to make that dream a reality.
Coding is now democratised and it will be used to solve everything else!

Mithil Vakde retweeted

Can complex multi-step reasoning emerge purely from cells that only talk to immediate neighbors?
Happy to share our paper “Reasoning with Neural Cellular Automata (NCA)”, from our team at Google, Paradigms of Intelligence 🧵👇
Mithil Vakde retweeted

My second interview with @CJHandmer, Founder of @TerraformIndies.
0:09 How the Mass Driver is going to work
2:54 Mass Driver vs scaling Starship
4:26 Economics of space compute vs building data centers on Earth
8:53 Why large scale projects are becoming illegal
14:26 Terafab
20:02 Starmind
26:19 Maximum scale as fast as possible
27:43 Luisiana launch tower buildout
30:13 Elon’s decade long company baking period
32:56 Firing teams
37:35 Starting companies
41:57 Being unfiltered publicly
42:52 DOGE
46:39 Deregulating without a major war
55:17 Founder-led companies are mini dictatorships
58:53 Taxes
1:03:26 Civilization hard resets
1:05:30 Starship scaling constraints
1:07:16 How Elon sets objectives
1:09:31 Universal high income
the only way to ensure long term survival of human species is building superintelligence
if no one builds it, our species will die

Mithil Vakde retweeted
I really enjoyed working on this project. I believe the new flop-aware paradigm of nanoGPT thinking is useful, and it seems helpful in a compute optimization context like this one. It seems like a simple and logical conclusion of optimization: figure out what’s actually needed, and use that. The process was actually fun.
One note regarding this record, as noted in the blog. Some of the techniques that scale to frontier pretraining have been redacted from this record. Most importantly, ANVIL III, the significantly improved version of the ANVIL optimizer lineage, has not been included in this record, as it is proprietary to us at @hyperstition_cc. It replicates Muon’s speed but beats it by 20-28 millinats of loss at all model sizes 124M-1.2B and training depths (up to 8x-Chinchilla), with remarkably consistent hyperparameters and extremely high SNR, as compared to Muon. You can learn more about ANVIL III and Feather-1.7B, the model we trained using internal architectural changes and ANVIL III, here:
hyperstition.cc/cutting-pret…
Using ANVIL III (which allowed me to cut steps) improved the speedrun results by another 0.7 seconds, with lower net loss. This alone proves there’s still more room to improve this record.
One final thing that I’ve had many people ask about is how much of a role autoresearch played in my work. The answer is almost none. While almost all of the implementation was done with Claude Code, I did the ideation almost fully by myself. I spoke about this extensively in a conversation with @METR_Evals.
We had a cluster of H100s while I was working on the record. At night or when I stopped working on it, I’d send out several agents to try to hill-climb the speedrun and improve the record. In total, the agents made shockingly little progress, despite spending more time in aggregate than I did. No matter what I told them, it seemed difficult to get them out of local minimums, stuck performing futile tuning of a method that saved 0.1 seconds and cost ~5 millinats (clearly a bad trade), or just tuning hyperparameters for hours on end trying to make some small change. I saw similar phenomena as those described in this METR report:
metr.org/blog/2026-07-21-exp….
However, as I also discussed with METR, I don’t think the agents lack the knowledge to do this. Instead, I think a lot of it comes from a personality issue with current LLMs. They have very little belief that large jumps like this are possible, or they approach it with the wrong paradigm. Autoresearch was not very helpful in my work, and, from personal experience, I don’t think this current generation of publicly available models, without special harnesses, will do very high-quality autoresearch. However, I think the capability and knowledge is already here, which implies that we could be significantly closer to true autoresearch than recent results would imply.
NanoGPT was a really fun challenge and it led to a number of valuable insights and processes. Finally, I’d like to give @Classiclarryd and @KellerJordan a huge thank you for all of their efforts maintaining the repo.


New historic NanoGPT record at 39.9s (-27.7s) from @DevenPzak , obliterating the prior record of 67.6s!
This record introduces a new paradigm of thinking to NanoGPT: instead of optimizing matmuls or adding more expressive operations, optimize at the individual flop level with incredibly clever engineering and ML judgement. If a flop is low value on a particular step, skip it.
Specifically:
-(~8s) Sampled softmax. If a token doesn’t appear in a batch, skip its lm_head fwd/bwd some fraction of the time.
-Sparse values. Only run an optimizer step for ngram embeddings that occurred in the batch. Set beta1 to zero to enable this. Beta2 is applied retroactively when the row is later used.
-Sparse updates. Only update ngram and value embeddings once every 4 steps instead of once every 2.
-Sparse communication. Shard the n-gram table across GPUs, and only pass the rows receiving updates on each step.
-Sparse optimizer states. For the n-gram table, reduce from 2 floats in Adam optimizer per param, to 1 float per 768 params.
-Hand-rolled flash attention for 64 dim heads.
There are several additions that add accuracy too:
-(~4s) EMA during last 300 steps, combined with lifting final_lr to 0.3 instead of 0.15.
-(~1s) A new optimizer, Anvil2, which expands muon via a second tracked momentum buffer, improves the ortho coefficients, and modifies the cautious weight decay application.
-A couple additional dynamic skip connections in the network.
The most striking consequence of the ‘flop aware paradigm’ is you can grow parameters arbitrarily large,
only limited by the available memory, since you can selectively choose how to expend flops on those parameters on each step. NanoGPT has kept active parameters below 124M, but total is unbounded, and has grown to 640M through embedding sparsity over the last year. This PR takes that to its logical conclusion on the 8xH100, scaling up to 65B sparse embedding parameters, which accounts for 25% of the PR’s gains. At frontier scale, where one is not bounded by an 8xH100, one could imagine where this paradigm could lead.
github.com/KellerJordan/modd…
As this was a very notable PR, I spoke with Deven for an hour to learn how he did it. Here’s his story on the changes: hyperstition.cc/training-nan…

man just rip the bandaid off, no more UIs
make it agents all the way down
auth and info/entertainment are the only time I wanna see an interface
Mithil Vakde retweeted

New historic NanoGPT record at 39.9s (-27.7s) from @DevenPzak , obliterating the prior record of 67.6s!
This record introduces a new paradigm of thinking to NanoGPT: instead of optimizing matmuls or adding more expressive operations, optimize at the individual flop level with incredibly clever engineering and ML judgement. If a flop is low value on a particular step, skip it.
Specifically:
-(~8s) Sampled softmax. If a token doesn’t appear in a batch, skip its lm_head fwd/bwd some fraction of the time.
-Sparse values. Only run an optimizer step for ngram embeddings that occurred in the batch. Set beta1 to zero to enable this. Beta2 is applied retroactively when the row is later used.
-Sparse updates. Only update ngram and value embeddings once every 4 steps instead of once every 2.
-Sparse communication. Shard the n-gram table across GPUs, and only pass the rows receiving updates on each step.
-Sparse optimizer states. For the n-gram table, reduce from 2 floats in Adam optimizer per param, to 1 float per 768 params.
-Hand-rolled flash attention for 64 dim heads.
There are several additions that add accuracy too:
-(~4s) EMA during last 300 steps, combined with lifting final_lr to 0.3 instead of 0.15.
-(~1s) A new optimizer, Anvil2, which expands muon via a second tracked momentum buffer, improves the ortho coefficients, and modifies the cautious weight decay application.
-A couple additional dynamic skip connections in the network.
The most striking consequence of the ‘flop aware paradigm’ is you can grow parameters arbitrarily large,
only limited by the available memory, since you can selectively choose how to expend flops on those parameters on each step. NanoGPT has kept active parameters below 124M, but total is unbounded, and has grown to 640M through embedding sparsity over the last year. This PR takes that to its logical conclusion on the 8xH100, scaling up to 65B sparse embedding parameters, which accounts for 25% of the PR’s gains. At frontier scale, where one is not bounded by an 8xH100, one could imagine where this paradigm could lead.
github.com/KellerJordan/modd…
As this was a very notable PR, I spoke with Deven for an hour to learn how he did it. Here’s his story on the changes: hyperstition.cc/training-nan…


Mithil Vakde retweeted

After 2.5 years at Sarvam, I am starting something new!
I had a great time leading the RL team. We launched the 30B and 105B models back in Feb with a young team building everything from scratch. Excited to see the team keep growing and pushing the frontier. Grateful to @pratykumar for the early bet and trust.
As for what's next: I am convinced that there are a few critical parts of the stack that we still need to build to meaningfully accelerate science. One of them is verification.
Scientific discovery only scales with compute when proposing and verifying new ideas is fast and cheap. In math and code, we're starting to see what happens when models can generate ideas and reliably check them at scale. OpenAI's recent Navier-Stokes work is a glimpse of what that looks like.
Similar moments in chemistry, materials, biology and the rest of the physical sciences would require verification to get dramatically faster and cheaper. It cannot be bottlenecked by the throughput of physical labs
More soon. Very excited for what's next.
Mithil Vakde retweeted

today we’re launching eyecandy robotics!
we’re bringing animated characters to life through robotics and ai.
Mithil Vakde retweeted

Hot damn!
Congrats on the AGI, @OpenAI! 😉
kenforthewin.github.io/blog/…