

Speech & Audio @ Hugging Face 🤗
Joined August 2023
- Tweets283
- Following385
- Followers842
- Likes511





Eustache Le Bihan retweeted

🤗 transformers serve now speaks 🔊
We just added an OpenAI-compatible `/v1/audio/speech` endpoint.
And we couldn't have picked a better model to launch it
with than Phonon, @GradiumAI brand-new on-device TTS: tiny, fast and multilingual.
Run with:
transformers serve gradium/phonon-40m-en
I told you it was not finished!
Banger release from the goated french speech team, aka @GradiumAI
day0 transformers 🤗 support, have fun building with it!

A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
gradium.ai/phonon🧵

find the model weights on their hub org 🤗
huggingface.co/gradium

Eustache Le Bihan retweeted

Harness Lens - what harness for your use-case?
Compare 19 (and counting!) harnesses across tools, design, and how opinionated they are.
Learn about how each compacts, their system prompt, and what makes them 𝙩𝙝𝙚𝙢.
Impressive tool by @yb2698: huggingface.co/spaces/ybelka…
Eustache Le Bihan retweeted

added Fish Audio’s Drama-3 to speech-to-speech 🎭
cloned my voice. now I can ask it to whisper, laugh, sigh or get worried, just by talking.
cheers to @andimarafioti for the demo + sampling tips!
PR + setup: github.com/huggingface/speec…
Eustache Le Bihan retweeted

Fun and crazy napkin math: Meta, NVIDIA, Alibaba, DeepSeek, Moonshot, Mistral and ~30 other labs have shared close to $1B worth of training compute on the Hugging Face Hub
Free to download
End of 2023 it was under $40M
Wikipedia was written in volunteer hours. This AI age commons is written in GPU-hours and data
(it's a floor btw: about half comes from official compute numbers rest is educated guess and it still miss the ~900k community fine-tunes)
Space with data to explore: thomwolf-hub-dollars.static.…

Eustache Le Bihan retweeted

There are 505 "agent traces" datasets on the @huggingface Hub (17.6 GB).
I parsed them to answer: what models, which harnesses, what tasks, how long are sessions?
Real user usage is ~15% of sessions. Here it is broken down:
🧵 👇

Eustache Le Bihan retweeted

Crazy week for open-source AI, right? Now it’s our turn!
Beam, Reflection’s first open model, is out:
-501B MoE, 23B active
-1M context
-Built for coding, reasoning & agentic workloads
-Apache 2.0
🧵
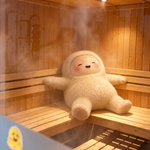
🚨 JUST SPOTTED chilling in the HF Paris sauna
Muse Spark Open landing DAY 0 in 🤗 transformers!!
What a week for open source 😎
🤖 Made with AI


Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio


Eustache Le Bihan retweeted
Jensen Huang le sait : la France est le pays le plus attractif d’Europe pour l’intelligence artificielle, grâce à nos talents, nos infrastructures et nos entreprises qui nous permettent de rester à l’avant-garde.
Depuis Choose France, notre coopération avec NVIDIA s’accélère, des startups aux grands acteurs industriels, en passant par les infrastructures de calcul et la recherche.
Avec une nouvelle étape aujourd’hui : NVIDIA investit dans des entreprises françaises et s’engage à soutenir notre initiative franco-allemande pour développer la recherche ouverte en Europe.
Cela a d’autant plus de valeur que nous partageons et portons la même exigence d’une intelligence artificielle ouverte, sûre et au service de notre souveraineté.
Merci cher Jensen pour votre confiance et votre soutien.

Eustache Le Bihan retweeted

Yesterday and today I worked on the new "decision" pipeline to support all `jev`-like models in `transformers`.
This will bring good standards in the mayhem that the ecosystem is now 👀
Meaning support for all jev/clef/von/etc via the simple and efficient `transformers serve`
crazy year for OS text-to-speech, and it’s clearly not the end 👀
BIG release by Fish Audio: drama-3
- big boy: 35B, 3B active, day0 support in sglang-omni
- would have loved a license allowing distillation though 🙈
plain-language direction, mid-line shifts, world-level tags
83 languages
features are cool but the moat isn’t just the weights. It’s that reward model (and the human A/B data behind it) + voice library, not released

$52M seed round. 15M+ users. But this is what we're most proud of yet.
Introducing Drama 3: the most emotive and controllable TTS model in the world
And yes, it's open-weight.
You can now control how even a single word should sound, change its tone, and shift your voice mid-sentence.
Uncle Roger was impressed too.
Try it here:
s.fish.audio/rqh0l8
Comment “DRAMA” within the next 48 hours for 1 month free.
If you're an enterprise your first month is on us:
s.fish.audio/qz9r0t

