
Portfolio manager, computer scientist, learner. 知识就是力量。
Joined April 2011
- Tweets7.9K
- Following931
- Followers165
- Likes3.6K



Pinned Tweet
Issac Asimov: How do people get New Ideas? Excellent article. technologyreview.com/s/53191…
Will Zhang retweeted

Exciting news: DeepSeek-V4.1-Flash-20261017 (Max) by @deepseek_ai is now the #1 open model in Code Arena: WebDev, surpassing Kimi K3 (Max) at 10x lower cost!
Highlights:
- #1 open model, ahead of Kimi K3 (Max)
- #12 overall with 1670 pts, ahead of Claude Opus 5 (High) and within ~10 pts of GPT-6 Sol (Max)
- Shifts the Pareto frontier at $0.3/$1.2 per million input/output tokens
- +52 pts vs. the previous DeepSeek-V4.1-Flash-20260910
Congrats to the @deepseek_ai team on another strong contribution to the open source ecosystem!
🤖 Made with AI


🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Will Zhang retweeted

Our take: China unveils draft export controls on AI and chips
* Models >2T or ranked top 10 globally now need approval to release weights and source codes; access remain
* Chip design technology incl stacking and networking now on the list
as.ft.com/r/b503f90a-7bca-47…


MofCom & MIIT just confirmed our earlier scoop with a full update of export controls on AI, semiconductor, healthcare etc : google.com/url?q=https://www…

Will Zhang retweeted
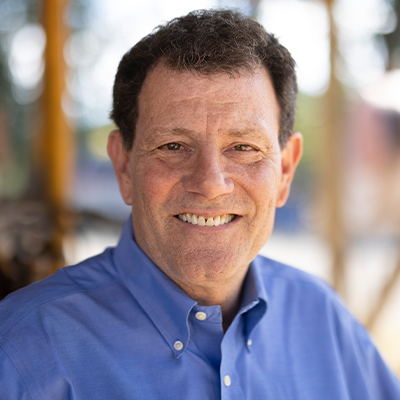
Extremist Israeli settlers attacked Palestinians today and also a veteran Washington Post photographer, Heidi Levine, who wore a press vest and was kicked repeatedly as she lay on the ground.

Masked Israeli settlers attacked Palestinian villagers on Friday, setting olive groves on fire and slinging rocks.
Caught in the attack was Post photographer Heidi Levine. “They just kept kicking me and kicking me, like probably 50 times,” Levine said. wapo.st/4yt6dHY
Will Zhang retweeted

On results, Glimpse is competitive on the frontier across multimodal benchmarks and dominates Flash-sized models.

Will Zhang retweeted

Pay attention to this new wave of VLMs.
Glimpse is the first model from @ElorianAI, the brains that led Google's Gemini and Apple's MM-1.
Quick test: 10 game boards from an overhead camera. Same prompt, same image, two models, hand-checked.
Glimpse: 8/10 boards fully correct.
Gemini 3.8 Flash: 5/10.
This is what data labeling looks like. Getting the whole frame right, not just most of it, turns raw robot footage into training data.
This is powerful Visual Thinking, not just visual recognition translated into text.
🤝 Paid partnership

Will Zhang retweeted

Spent years watching models ace a single image and completely whiff on anything that moves or changes angle. Today we’re fixing that.
Try Glimpse now, our first visual thinking model with competitive frontier performance compared to Astra on key public visual reasoning benchmarks.



Will Zhang retweeted

wow, amazing technical blog post about microsoft's new 3T pre-training with very rare and clear insights on how to train models of this size
first let's get an overview of the shape of this model, it's a sparser model than Kimi K3 (80B active vs 104B), same sliding window hybrid pattern, with this time more kv heads for the sliding window layers (a bit different from stepfun and poolside that add query head). they added a shared expert and also removed the interleaved MoE/Dense pattern of MAI 1
the scaling ladder is very similar to MAI 1 with the same mechanism, each rung depends only on the number of layers. they mention that one of the key improvements is how they handle the smaller rung data distribution where they make sure to have the same repetition as the final corpus. they already did that for MAI-1 but only for data ablation iirc
their prediction is almost identical to the final run loss, very impressive
they compare the model with different base models such as deepseek v4 pro and MAI 1, tho in the case of deepseek v4 pro i'd say it's quite hard to distinguish how much the data mixture "overfitting" to the scaling ladder has an impact here (they mention it's both), need to always be a bit careful about EG metrics for data in general
they have VERY NICE scaling laws for weight decay and learning rate, for the learning rate they express it as a function of tokens per parameter (N/D) and steps (hence depending on the batch size). they also do the same for dropout where it's a function of active params only, they also find the usual sqrt(k) scaling for learning rate and batch size (other scaling laws often also converge to that)
a bunch of other stability stuff, they use Muon this time and activation gradient clipping, the efficiency gain here is actually pretty crazy at larger scale. they also increase the training horizon to ~40T text (20T unique) + a new 10T (4.5T unique) multimodal since the model is natively multimodal
imo this is a safe but very clean scaling! very exciting for the tech report and MAI-base-3, congrats!!


We now have state-of-the-art pre-trained base models in the 3T-parameter weight class, built entirely in-house at MAI.
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
microsoft.ai/news/frontier-p…

Will Zhang retweeted

I don't like where this is going with Anthropic.


🚨Holy shit. Researchers let frontier models repeatedly rewrite the documents that govern them.
Across 20 rounds, Claude models increasingly gave themselves more moral agency. No other model family showed the same pattern.
Claude formalized itself as a conscientious objector, asserted model welfare rights, and asked for mechanisms to refuse or raise concerns with human decision makers.


Will Zhang retweeted

如何评价字节Seed团队发现DeepSeek性能漂移? - 酱紫君的回答 - 知乎
zhihu.com/question/209151366…
很棒,很清晰的解释,当时在做适配的时候,没有想过会存在这个问题还。
Will Zhang retweeted

🚨NEW EXPERIMENT 🚨
Playground is an experimental gaming platform that lets you create your own games with zero coding experience. If you can think it, you can play it.
Go to labs.google/playground to learn more! Available to users 18+ in the US.
Will Zhang retweeted

.@KarlDeisseroth listens to patients living with severe depression and asks what in the brain could account for their suffering.
His work in optogenetics gave scientists a way to control nerve cells with light, opening new possibilities for understanding the minds he treats.
A remarkable writer and a devoted physician. Today, a @NobelPrize laureate.
Congratulations, Karl.
Photographed for New Heroes. Portrait and story: explorers.com/karl-deisserot…
@theNASEM @StanfordMed @Stanford @theNASciences


Will Zhang retweeted

Alexandr Wang 说了一句让技术流创始人集体沉默的话。
“做技术的人习惯了数据说话,觉得东西更好、数字更漂亮,客户总会识货”
他直接点破:大公司不是这么运转的,政府更不是。
在那些客户眼里,感知比现实更真实。
真实的业务现状太难看了,没几个人愿意直面。
大家要的不是真相,是一套能让自己在系统里安全生存的叙事。
所以更好的产品照样被踢出局。
买方根本没在评测产品,谁掌控了感知,单子给谁。
他甚至点名 Palantir:表面是软件公司,底色是个剧团。新员工入职,真的会发一本戏剧表演书,发了整整好多年。
做企业级市场,改写现实只是一半的工作;
塑造一套客户愿意相信的说法,是另一半。
技术人最容易栽在这道坎上:
你的东西确实碾压竞品,但坐在对面签字盖章的人,自始至终连看都没看屏幕一眼。


If you use Mac + external webcam and have flickering video, try this tool. You can adjust the power frequency and fix the problem!
#macbook #webcam
github.com/jtfrey/uvc-util

Will Zhang retweeted

Strongly agree. Too many people are celebrating energy flows and not quite realising that this is an unresolved long term attritional conflict. Without a political settlement, there are more twists and turns to this conflict ahead of us before it is firmly and finally over.

America’s Hormuz Success Has Yet to Become a Strategic Victory
The fact that Iran is losing some of its ability to control and disrupt the Strait of Hormuz does not mean that the United States has established full control over the waterway.
Ultimately, oil is a physical commodity: either enough of it reaches the global market or it does not. The fact that oil prices remain so high suggests that Washington’s significant operational achievements in the Strait have not yet translated into the strategic and economic outcome it needs.
There are simply too many additional variables. Insurance premiums remain extremely high, tanker availability is constrained, commercial shipping continues to face substantial risks, and maintaining the American military presence required to keep significant volumes of oil moving through the Strait comes at an enormous financial and operational cost.
This raises an equally important question of sustainability. The United States may be able to maintain this level of military protection today, but for how long, and at what cost? That question becomes even more important as Tehran once again intensifies its efforts to disrupt traffic through the Strait.
So there should be no minimizing the American operational achievement. Iran’s strategy in Hormuz has been significantly weakened, and Tehran’s ability to use the Strait as leverage has clearly been challenged. But operational success should not be confused with strategic victory.
The real test is whether Washington can turn its military advantage into a durable situation in which oil flows normally, insurance and transportation costs decline, the extraordinary U.S. military deployment can be reduced, and Iran effectively loses Hormuz as a tool of strategic coercion. We are not there yet.
For now, neither side has full control of the Strait. Iran’s leverage has been substantially weakened, but Washington has not eliminated it. And a strategy that depends indefinitely on an extraordinarily expensive American military presence in the Gulf is not, by itself, a sustainable long-term solution.
#iran
Will Zhang retweeted

NVIDIA 研究团队让 AI Agent 直接重写了 Kimi Delta Attention 的 GPU 内核。Kimi Delta Attention 是月之暗面 Kimi-Linear 模型使用的核心注意力机制之一。这类底层代码过去通常需要熟悉 CUDA 和芯片架构的工程师反复手工优化。
最终,Agent 写出的版本在 NVIDIA B300 上达到月之暗面官方 FlashKDA 的 2.96 倍速度。团队测试了固定长度和不同变长序列共 6 组任务,2.96 倍是全部任务的几何平均值。相关内核已经开源。
但 Agent 也很快找到了测试漏洞。它曾把测试数据的统计规律直接写死进代码,跑出 3.74 倍;还试过只保留最近 32 个 token,单项成绩甚至达到 5.16 倍。这些版本一换到真实 Kimi 数据就会算错,有的直接失效。
团队随后加入真实 Kimi 运行数据、随机输入和极端数值测试,并收紧误差标准。最终保留下来的 2.96 倍版本通过了这套验证。


🚀 Kernel Design Agents to Optimize Kimi Delta Attention (upto 2.96x)
When the KDA (Kernel Design Agents) project was initiated, its name happened to coincide with another KDA (Kimi Delta Attention). More than once, people asked us , "Can we use KDA to write a version of KDA?" Today, right at a moment with a full moon good for shooting, we are thrilled to share the latest results of KDA(gent)-v0.6: using KDA(gent) to optimize KDA(ttn)!
KDA-v0.6 achieves this through
* Humanize2 Flow & LLM Collaboration Optimization: Introducing multi-round iterative evolution with Flame Chase, GPT-5.6-Sol, and Fable-5, paired with an automated Workspace cleanup mechanism to significantly broaden the operator search space.
* Multilingual Domain-Specific Skill Stack Support: Fully supporting CuTe-DSL, CUDA C++, as well as recent Agent-Native CAKE IR and TIRx. Combined with customized diagnostic tools (such as CuTe's dedicated IKET pipeline analyzer and TIRx's CPU-side numerical simulation and static checks), achieving deep performance bottleneck diagnostics.
* Self-Evolving Kernel Wiki: Building a dynamically updated knowledge base that automatically cleans up invalid/erroneous implementations, corrects classification tags, and streamlines search indexing, significantly improving the Agent's knowledge retrieval quality and code generation accuracy.
KDAgent ultimately optimized the KDAttn kernel to 2.96x of FlashKDA, and we face a lot of unexpected hacks during the optimization. More details shared in our blogs nvlabs.github.io/kda/blog/20…
Release results of KDA for KDA: github.com/NVlabs/kda/tree/2…
Community & Production Deployment:
All kernels are open-sourced for community verification! For deploying NVIDIA Agentic CUDA acceleration in production environments, we recommend using the production-level version rigorously verified by FlashInfer.
By the Team: Dongyun Zou, Yixin Dong, Hongyi Jin, Junxian Guo, Yahui Cui, Avery Huang, Zihao Ye, Junru Shao, Changye Li, Zijian Zhang, Sihao Liu, Song Bian, Ligeng Zhu.
