



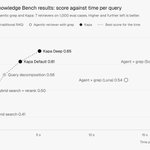
it's still mindblowing to be that jev isn't a reranker but it performs like one

wow jev 1.14 is stupidly good as a reranker
gg @typesafeai team

wow jev 1.14 is stupidly good as a reranker
gg @typesafeai team
Emil retweeted
love to see this integration
introducing @LangChain × kapa
your langchain agents can now search all your company knowledge more accurately, 3x faster and 8x cheaper than frontier models
we synch docs, github, notion, slack, zendesk and more into a single index (with vectors + file system)
your agent gets two tools: search everything, and read the full doc
it takes 2 min for your agent to set up (+ free to try)
just paste this into your agent:
"set up a knowledge base for my agent using docs.kapa.ai/getting-started… and pip install langchain-kapa-ai to use official plugin"
keep making agents go brr @hwchase17 + team!
we think this is a peak into the future of how agents will use the web :)
introducing WebMCP in kapa
any agent that visits your website can now ask your company directly
today agents scrape your pages and tries to convert them to markdown. it's the early mobile web all over again, pinching and zooming through sites built for someone else
instead WebMCP lets your site hand agents a proper tool. answers come from your own knowledge with source links. and you get analytics!
codex and chatgpt's browser already use it. chrome has it in an origin trial
if you are an existing kapa user, it's a one line change for your widget: data-webmcp-enabled="true"
if you aren't, you can try it for free for 14 days :)
we just killed RAG in n8n.
introducing the official @kapa_ai node for @n8n_io
no more:
- chunkers, embeddings and vector stores to babysit
- re-index jobs that quietly go stale
- naive 2024 rag pipelines
instead, kapa:
✓ connects all your sources to one index
✓ keeps it in sync by itself
✓ gets better answers in half the tokens
and its free to try :)

Emil retweeted

Ever found the answer buried between docs, tickets and GitHub?
@kapa_ai, co-founded by @emilsnotes, has a ChatGPT plugin to pull source-backed answers from your team’s knowledge.
14-day trial, then paid.
chatgpt.com/plugins/plugin_a…

introducing the official @kapa_ai for grok @bot
stop your bots making up answers about your product
connect your docs, help center and tickets once. every bot answers from them, and keeps up when they change.
now you can easily build bots to:
- answer support questions accurately
- fill in security questionnaires from your docs
- build sales coaches that review calls and coaches reps
best part: your bot spots gaps in your docs and opens PRs to fix them :)

Super excited that @clickhousedb uses @kapa_ai 🚀
Helping developers AND their coding agents get unstuck on a deeply technical platform.
ClickHouse uses Kapa to power AI answers across its documentation, with MCP making that same knowledge available to coding agents directly in the IDE.
Helping people get unstuck and get more out of the product. Awesome to be working together!

used the @CustomerIO MCP and the @kapa_ai MCP to email kapa customers announcing the @kapa_ai MCP
one of those customers is @CustomerIO
i swear this is not a riddle

Introducing the Kapa MCP
set up and run @kapa_ai without opening @kapa_ai
> launch a docs agent
> add a Slack bot for your team
> index Zendesk, Confluence, Notion + 30 more
> spin up an MCP server
> read your top questions and docs gaps
> open PRs to fix the docs
all from one chat in Claude or Cursor
the dashboard is feeling a bit left out :)

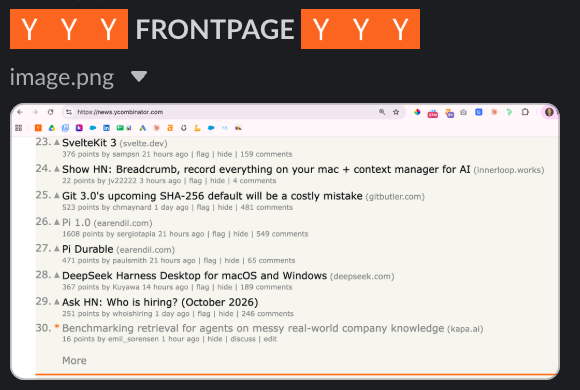
annnnnd HN front page!!
introducing Company Knowledge Bench
the first retrieval benchmark built on messy, real-world company knowledge
soon agents will do a huge share of the work inside every company. all of it starts with finding the right information, but almost nobody can measure how well their agents actually find it
public benchmarks don't help. they're either one narrow domain like law or medicine, or synthetic documents and questions. real company knowledge is messy, contradicts itself and goes out of date
retrieval is the core of @kapa_ai, so we spent months building our own benchmark from 1,000 real-world queries by people and agents
then we ran 7 retrievers on it:
1/ grep works surprisingly well, but it's 5x slower and floods the context with 40K tokens per query
2/ optimized agentic retrievers do far better. Kapa Deep scored highest (0.65) in ~5s with an eighth of the tokens
3/ we're still very early. lots of headroom left, especially as more agents run on company knowledge
full write-up below
