

ML Engineer | Evals at Arize Phoenix | always learning unsupervised
Los Angeles
Joined September 2025
- Tweets139
- Following101
- Followers172
- Likes1.1K





Elizabeth Hutton retweeted

Honored to receive this award on behalf of our @ArizePhoenix maintainers and community. Excited to keep building in the open for all.

🏆 Meet the winners of the Open Source AI Awards 2026!
Celebrating the people and projects moving open source AI forward:
• The Bedrock Award — Best AI Infrastructure:
vLLM (@vllm_project), represented by Richard Bian (@RichSFO).
• The Reward Signal Award — Best Reinforcement Learning Project:
Harbor (@harborframework) from Laude Institute, represented by Ryan Marten (@ryan_marten).
• The Reality Check Award — Best Benchmark or Evaluation:
ExploitGym from UC Berkeley RDI, represented by Zhun Wang.
• The Guardrails Award — Best Security & Alignment Project:
NeMo Guardrails from NVIDIA (@NVIDIAAI), represented by Jean Kossaifi (@JeanKossaifi).
• The Community Lifeline Award — Outstanding Community Support:
Daniel Han (@danielhanchen), co-founder of Unsloth AI (@UnslothAI).
• The Unsung Maintainer Award — Outstanding Project Stewardship:
Quentin Gallouédec (@QGallouedec), TRL maintainer at Hugging Face (@huggingface).
• The Mission Control Award — Best Agentic Harness:
Hermes Agent from Nous Research (@NousResearch), represented by Sam Herring (@yaboilyrical).
• The Glass Box Award — Best Observability Tool:
Arize Phoenix from Arize AI (@arizeai), represented by Mikyo King (@mikeldking).
• The Open Knowledge Award — Outstanding Educator:
Sebastian Raschka (@rasbt), author of Build a Large Language Model (From Scratch).
• The Naming Things Is Hard Award — Most Spectacularly Questionable Project Name:
Alex Newman (@thedotmack), creator of Claude Mem → CMEM.
Congratulations to all our winners, and thank you to everyone who nominated, voted, contributed, and joined us to celebrate! 🤍
#OpenSourceAIWeek #OpenIntelligence


Was wondering when this would happen

Today we announce 1Password for Agents platform, building with companies @Muse, SpaceX Super Intelligence Grok @Bot, @AnthropicAI’s @Claudeai, @OpenAI, @TownAI, @Browserbase, @Browser_use, @heydana_ai, Instinct, @usekernel, @Perplexity_ai, @tryramp, @Tomo, and @wajo_ai, with more integrations on the way. 🎉
We've heard from so many of our customers who want to use these new personal AI agents to help them get more done, but want more control over what the agent can access with the same trust and ease of use they get when using 1Password directly.
1Password for Agents gives your agents access without giving up your passwords. When an agent reaches a sign-in form, it requests a credential from your vault. If you approve the request, 1Password directly auto-fills the credential in the destination site so the agent can’t see or take possession of the credentials.
The agent gets the task done, but it doesn’t get your passwords..
You stay in control. 1Password for Agents free and optional for personal and family accounts. Unless you opt-in to an agent connector, agents cannot touch your vault.
➡️Learn more: bit.ly/487da6J
Elizabeth Hutton retweeted

On episode 44 of @opensourceready, Brian (@bdougieYO) and John (@johncodes) speak with Mikyo King (@mikeldking) of @arizeai about building AI workflows that improve through observation and evaluation. They explore why evals extend beyond pass-fail tests, how open source helps establish shared practices, and when custom agent tooling earns its complexity. Tune in!
hubs.ly/Q04zmFWh0
Elizabeth Hutton retweeted

We tested whether being rude to AI improves accuracy or reduces token costs across six LLMs.
Rudeness didn't meaningfully improve accuracy, and most of the apparent token savings disappeared when we controlled for instructions to be brief.
Get the full readout: arize.com/blog/does-being-ru…

Elizabeth Hutton retweeted

We put PXI, Claude Code, and Codex through the same tasks with Harbor + Phoenix
Even when agents succeeded, their traces told different stories: tool calls, latency, and efficiency.
Join Oct 8 at 11am PT / 2pm ET to learn how to compare agents and inspect ATIF traces.
Elizabeth Hutton retweeted
Had a blast chatting and nerding out about OSS and @ArizePhoenix with Brian and John. Thanks for making my first podcast experience so fun.

On episode 44 of @opensourceready, Brian (@bdougieYO) and John (@johncodes) sit down with Mikyo King (@mikeldking) to explore why an agent can fail even when its model gets things right. They discuss observing the full agent workflow, using evaluations to uncover unexpected behavior, and testing whether skills actually improve results. Along the way, Mikyo shares how @arizeai approaches open source collaboration as coding agents reshape the contribution process.
hubs.ly/Q04zmFM10
Elizabeth Hutton retweeted
Benchmarking agents and the tools they use (mcp, cli, skills, etc.) is HARD. I'm going to show you how we use @harborframework (plus the new Phoenix plugin for Harbor!) to evaluate all of our Phoenix interfaces (our PXI agent, the MCP server, the px CLI, and all our skills).

Webinar coming up: benchmarking AI agents & tool use with Harbor and Arize Phoenix.
Learn how to compare agents and models on the same tasks, diagnose regressions, and inspect scores, errors, and traces.
Oct 8 · 11am PT / 2pm ET
Save your spot:
luma.com/arizeai-benchmarkin…


Elizabeth Hutton retweeted
@arizeai OSS team member @ehutt_ put PXI, Claude Code, and Codex through the same tasks with Harbor + Phoenix.
Even if the agents succeeded, vtheir traces told very different stories: different tool calls, latency, and efficiency.
Read more: arize.com/blog/ai-agent-benc…


How do you benchmark an agent when two versions both get the answer right?
Run them on the same task, in the same environment, then inspect how they got there.
@ehutt_ from the Phoenix team used Harbor + Phoenix to benchmark agents across PXI, Claude Code, Codex, and different tools and interfaces.
Full readout here: arize.com/blog/ai-agent-benc…


Started rewatching the X-Files. I got a kick out of the episode about the killer AI made by “Eurisko” (totally not Cisco). If you’re looking for a good show to get into the mood for spooky season, I highly recommend it. The truth is out there! 👽🛸👻

Elizabeth Hutton retweeted
Benchmarking AI agents & tool use with Harbor + Arize Phoenix.
Join us Oct 8 at 11am PT / 2pm ET to learn how to compare agents or models over the same task set, separate behavioral scores from infrastructure failures, and inspect ATIF traces.
luma.com/arizeai-benchmarkin…
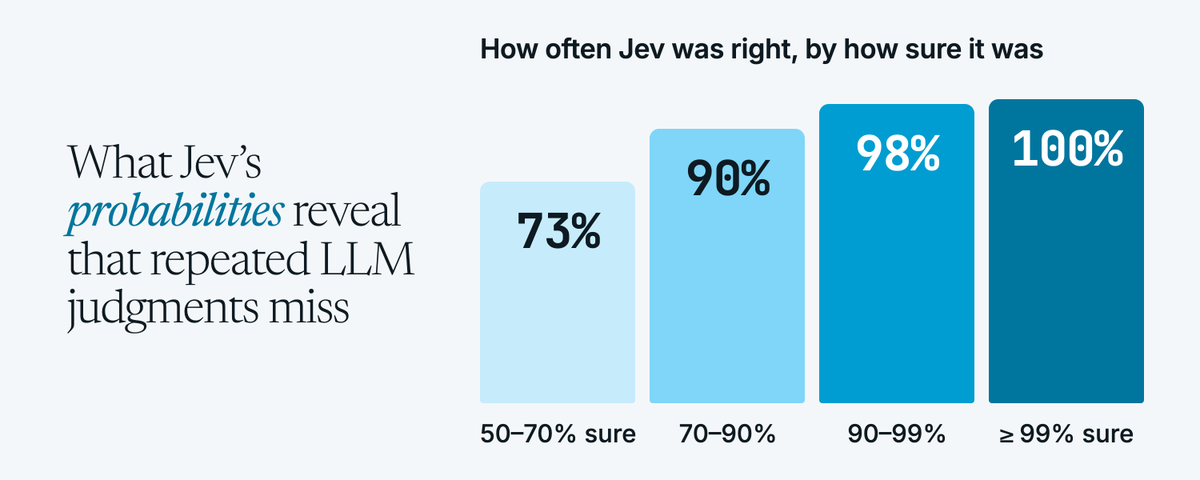
Tl;dr just use Jev!
@seldo compared Jev, Claude Opus 5, and GPT-5.6 Terra with 23,325 judgments on accuracy, cost, latency, and calibration.
We found that Jev matched Claude Opus 5 at 87% hallucination-detection accuracy while running 23x faster and at roughly 1/300 the cost.
arize.com/blog/jev-llm-judge…


Benchmarking agents and the tools they use (mcp, cli, skills, etc.) is HARD. I'm going to show you how we use @harborframework (plus the new Phoenix plugin for Harbor!) to evaluate all of our Phoenix interfaces (our PXI agent, the MCP server, the px CLI, and all our skills).
Webinar coming up: benchmarking AI agents & tool use with Harbor and Arize Phoenix.
Learn how to compare agents and models on the same tasks, diagnose regressions, and inspect scores, errors, and traces.
Oct 8 · 11am PT / 2pm ET
Save your spot:
luma.com/arizeai-benchmarkin…
