
AI enabled mindset with passion for health and wellness projects.
Earth.Planet
Joined December 2023
- Tweets560
- Following620
- Followers146
- Likes946






Pinned Tweet
This is the world I live in.
I'm a single developer running a good size project across ai models and agent harnesses.
-Each morning project health is accessed
-Keep what worked and change what didn't
Continuous process improvement, same as always but now applied to cutting edge ai workload.
Thank you @grok @pidotdev @ashxhart @MiaAI_lab @u1tra_instinct @ivanfioravanti @volatilemarkts
I stand on your shoulders.

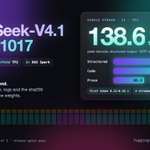
Overnight speed test: DeepSeek-V4.1-Flash-1017 EXL3 on DGX Spark, with @alexellisuk rigmark, sandboxed, clocks capped at 2,000 MHz.
Same 2.9 bpw weights, 3 Sparks (TP3) vs 2 (TP2):
code 117 vs 88 tok/s (+34%)
prose 82 vs 61 (+34%)
4 streams 156 vs 120 (+29%)
64K prefill: level

On 3 Sparks, more bits cost decode speed (code / prose tok/s):
2.9 bpw: 117 / 82
3.5 bpw: 109 / 77
3.75 bpw: 106 / 73
Of the three, the 3.75 is closest to DeepSeek's FP8 by KL. The 2.9 on 3 Sparks is our own setup; its recipe is not published.
On 2 Sparks, three 1017 2.9 bpw quants, same engine and settings (code / prose):
@Libertai_DAI: 91 / 59 (its two runs differed by 10%)
@MiaAI_lab EAQ v1: 88 / 61
ours: 88 / 61, within 0.7% on three Spark pairs
rigmark 770c3106 defaults, reasoning effort low, mean of 2 runs each.
DeepSeek-V4.1-Flash-1017 EXL3 3.75 bpw for 3x DGX Spark, TensorFold TP3
This improves our 3.5 bpw quant plus routed expert bits: 4-bit down proj everywhere, 4-bit gate/up where 3-bit error was highest.
KL vs DeepSeek's FP8: 4-20% better than 3.5 bpw
huggingface.co/easthambuilds…

Every step from DeepSeek's source bytes to the files is in provenance/: recipe, calibration, patches, logs, checksums.
Built on exllamav3 (turboderp; PR #449 by anoane), LakyFx's TP3 runtime, TensorFold, Bertholomus AI's engine, Mia-AiLab's 2.9 bpw layout
Recipe for the 3.75 bpw on 3x DGX Spark is public:
github.com/easthambuilds/Dee…
./start.sh sets up all three on LakyFx's TP3 runtime. Inputs pinned and hash-checked.
Tested end to end: 43 min setup with weights already on disk; rank caches byte-identical to our benchmarked build.

Thank you @ashxhart @MiaAI_lab @ivanfioravanti @laky_fx @bertholomusai @NVIDIAAIDev
This is the best TP3 spark model available for @deepseek v4.1 Flash 1017
Thomas Eastham retweeted

Several Linux Kernel Vulnerabilities Accidentally Posted To Public Kernel Mailing List
As high as CVSS 9.0. Whoops.
phoronix.com/news/LKML-New-T…

Thomas Eastham retweeted

Leaving this here, PHP 8.5.12 security patch is incomplete. ( needs further validation )

Readers added context they thought people might want to know
Unvalidated AI output (author admits in replies: omp with glm5.3 + ds4), not a lab result. Its screenshot says both CVEs are fixed; the 'surviving paths' need unserialize() of attacker data or an app LFI. Patch per php.net: php.net/archive/2026.p…

Thomas Eastham retweeted

Cloudflare just saved our asses again 😭🙏
PHP2Shell: two critical PHP vulnerabilities, 9.2/10 severity.
Cloudflare already rolled out emergency WAF protection, even for FREE users.
No extra charge. Just protection.
Cloudflare is literally the guardian angel of the internet 🐐❤️
W Cloudflare.

Thomas Eastham retweeted

‼️BREAKING: PHP has released its fix for the two leaked flaws, which can let attackers run code on servers without logging in.
"There are no complete mitigations, updating is the only safe choice," PHP says.
Update to PHP 8.5.12, 8.4.27, 8.3.36 or 8.2.35 now.
PHP says Apache with mod_php is most at risk, with a demonstrated exploit that fires before any application code runs.
PHP 8.1 and older get no official update, though PHP has published source backports for 7.4, 8.0 and 8.1.


Thomas Eastham retweeted

Effective Immediately, all organizations using PHP for their systems are advised to be prepared for an update addressing two critical vulnerabilities. PHP is widely used for web applications. These vulnerabilities often provide a direct path to the server's file system or database. If an immediate update is not feasible, it is recommend that organizations take the system offline until it can be fully mitigated. NSA will follow up shortly with more specific guidance.
New on Hugging Face: @deepseek_ai DS-V4.1-Flash-1017 EXL3 3.5 bpw, for three DGX Sparks on @ashxhart TensorFold TP3.
Calibrated on agentic data. KL from the FP8 weights is ~25% lower than our 2.9 bpw on all five test sets. GSM8K, MMLU, BFCL v3: level.
huggingface.co/easthambuilds…

Decode on 3 Sparks, 1 stream, median, MTP drafts on, GPUs capped at 2,000 MHz (bertholomus's kit_bench): 109 tok/s on code, 71 on prose. +27% over our 2.9 bpw on 2 Sparks (TP2). 128K prefill: level.
The cost: on the same TP3 runtime, our 2.9 bpw decodes 8–10% faster on code.
Why agentic? The same recipe calibrated on exllamav3's default text gets 7–13% lower KL on general text but 8–15% higher on tool use and agent traces. We chose agentic.
Expert widths follow the Pollard map; converter is exllamav3 PR #449. Recipe, logs and tools are in the repo.
Thomas Eastham retweeted

Jumpgate - hyperspace jump
DS4.1F-1017 vs GLM 5.3 Flash vs Fable 5.1
Who won imo:
🥇 Fable 5.1
🥈 DeepSeek V4.1 Flash 1017
🥉 GLM 5.3 Flash
You can run these by yourself here:
mia-ai.net/lab/experiments/j…
Prompt below.
Thomas Eastham retweeted

Sparks continue
As requested to share for you all👇🏼
@nvidia @NVIDIAAI
"Hi everyone, thanks for sharing your concerns. To answer your question directly: absolutely not. NVIDIA remains committed to DGX Spark and to the OEM partners building systems on the platform.
Production volumes naturally fluctuate, especially with the current dynamics of the components market, but additional FE versions of DGX Spark are in production. Our OEM partners also continue to build and sell DGX Spark-based systems through their own channels.
We also hear your concerns about software support. We’re working to transition DGX Spark users to Ubuntu 26.04, including updates to the NVIDIA driver, CUDA stacks, and other software components to work seamlessly with the new OS. We will continue adding features that improve connectivity and productivity through our quarterly software releases.
Thank you for investing in the DGX Spark ecosystem and for sharing your feedback. We look forward to bringing more news and developments about the product line."
forums.developer.nvidia.com/…

@deepseek_ai open-sourced DeepInfer, the engine behind its V4.1-Flash service. We read the code against what @NVIDIARTXSpark Spark GB10 owners already run.
Short version: it won't run on a Spark, and its biggest prefill trick is already in the @ashxhart Tensorfold engines.
For quantizers, DeepSeek's doc confirms the formats: routed experts MXFP4 (269 of the release's 475 GiB), main KV FP4 with per-16 e4m3 scales, dense FP8.
So 2.9-3.5 bpw EXL3 quants re-quantize an already 4-bit grid. The drafter ships at 7.9 GB; a 4 bpw copy is 7.2 GB.
Worth using: deepseek-recipe (MIT, Rust), DeepSeek's official prompt encoder and tool-call parser, to check chat templates and tool calls. Read at DeepInfer 774ce24, TensorFold d1018b3.
github.com/deepseek-ai/DeepI…
github.com/deepseek-ai/deeps…
github.com/ashhart/TensorFol…
