

consulting companies in evals, search, retrieval
Joined November 2018
- Tweets5.4K
- Following443
- Followers15.4K
- Likes26.3K





Pinned Tweet
tried going as much in detail as possible for the Colpali blog, it will be a long read
antaripasaha.notion.site/Col…


we have ran an extensive experiment with all major decision models on our dataset to see how trustworthy decision models are for evals
go give it a read


Antaripa Saha retweeted

New blog post 🎉: How To Use Decision Models For Evals
In this post, we show you how to choose a decision model for your task, tune its threshold (don't assume the 0.5 default is good!), and interpret its scores.
Lots of cool interactive charts here.
Antaripa Saha retweeted

OCR (esp. VLM approaches) often extract 1 page at time, which breaks when cross-page context is needed, which is a lot.
Join @barrowjoseph and I as we dive in and discuss this topic, OCR post processing, and the new Miner U Popo paper.
luma.com/mineru


for folks who have been constantly asking what’s perplexity is upto nowadays. check this out.
the team is cooking with lots of awesome releases on embeddings models. rooting for the team more so after Antoine has joined

Antaripa Saha retweeted

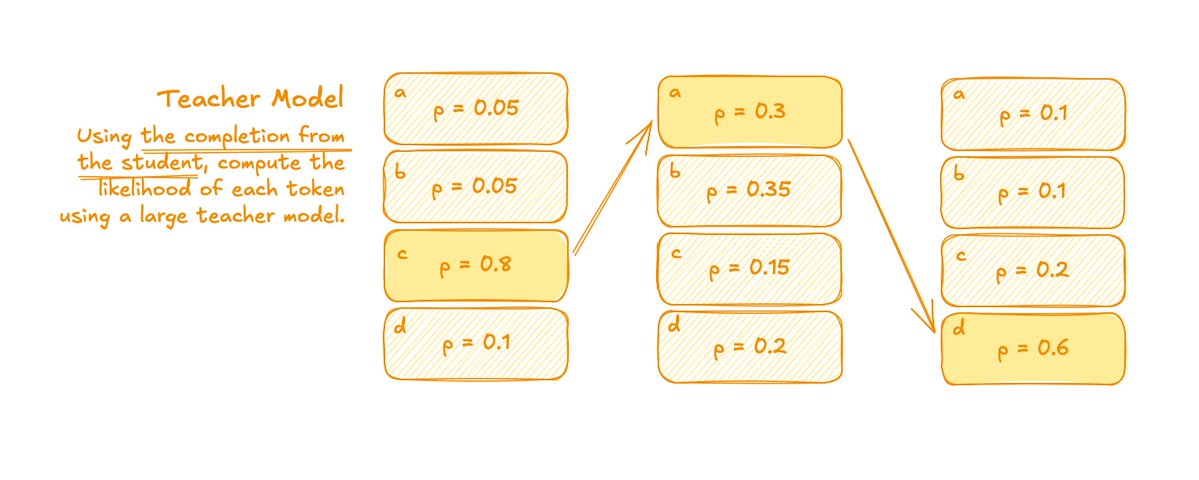
I spent a flight building a "minimal on-policy distillation" setup. Unlike a lot of other tutorials, my focus is on the engineering of spinning/scaling up training!
In the real world, you should just use @PrimeIntellect's prime-rl or @huggingface's TRL (among others) but...


Antaripa Saha retweeted

Excited to share Quail, our new open source AI-SQL engine (a collab with Modal)! By planning queries and LLM inference together, it reaches 1B+ input tokens/min on one H100 for one query 😱🚀
AI-powered data operators create a new, interesting inference workload👇
doing my debut in video content with my fav topic -> evals
we are starting this series and will go a lot deeper into how to do evals. excited ;)


Antaripa Saha retweeted
I've been using Jev by @typesafeai Here's the six things i've tried and am confident I'll still use Jev for 60 days from now.
There's many more experiments, ideas, and things I think I will use it for. It's a big deal (more on why in next post).
But I am only sharing things that I am 99% sure will lead to stuff I will still be using Jev for in 60 days.
That means I started with small, boring, but useful, stuff.
- Fact-checking my scripts
- Ranking my news feed
- Finding the right text in PDFs
- Checking citations
- Grouping my review notes
- Figuring out why agents fail (eval over traces)
isaacflath.com/writing/six-t…

Antaripa Saha retweeted

new blog on my explorations @ prime residency "Honey, I Looked at the Data of a Frontier Benchmark and Found some Issues: Porting Agents' Last Exam Linux CLI subset to Verifiers v1" is up now. got to work with florian (@xeophon) as my verifier on this.
sankalp.bearblog.dev/porting…

100% of the data is synthetic
people are often skeptical of synthetic data. it just proves how carefully constructed synthetic data can be incredibly powerful

you might be the first person talking about the data over the architecture! 🥲
we consider ourselves a data research lab! the vast vast vast majority of research was on making data that is truly general (ala a cognitive core) and 100% of our data is synthetic (but not the type of crap that is just spit out from an LLM obviously)
got access to Jev!!
heard a lot of good things about it, especially as a classifier.
really curious to try it for evals. lots of llm-as-a-judge for binary decisions are going to get replaces. give Jev some state + a bunch of questions and get back probabilities you can actually threshold on.
also feels pretty useful inside agent harnesses as a control plane for making all those fuzzy decisions like which model or tool to route to, whether to continue or retry, whether an output looks good enough, whether something needs human review, etc. basically letting the llm handle generation, while Jev handles a lot of the judgment calls around it.

Antaripa Saha retweeted

A lot of my working life over the past year has been preoccupied with harness engineering.
When @HamelHusain introduced me to @doesdatmaksense to chat about how evals belong at the center of harness engineering, I immediately wanted her to write a guest post for the VG substack.
Check it out to take your agent evals to the next level: hugobowne.substack.com/p/how…
Thanks, AS & HH!

Antaripa Saha retweeted

📈 New blog post: Training and Finetuning Multi-Vector Embedding Models with Sentence Transformers.
As a practical example, I finetuned a ColBERT-style model for medical retrieval. 14.5 hours on one RTX 3090, and it beats every general-purpose retriever I could find.
Thread 🧵

such a creative work. and look at the reward functions, that is why it’s always suggested in evals too to go for binary as compared to 0-10 rubrics

Antaripa Saha retweeted

AutoResearch experiment: I went into a GPU Mode kernel competition with very little CUDA background and engineered a research loop around coding agents: goal, rules, experiment memory, verifier, and compute.
Finished 5th overall. Give it a read.

Do automated evals actually work?
I and @HamelHusain spent last few weeks testing the auto-evals efficacy of different evals platforms.
We took 100 real production traces from an apartment-leasing voice agent, manually reviewed the failures, masked the labels, and asked different systems to do the same error-analysis task and discover failure modes.
We tested dedicated eval platforms like Braintrust, Arize, and LangSmith, along with ChatGPT, Codex, Claude Code, and Factory Droid.
Full post here: parlance-labs.com/blog/posts…
