

I’m a computational biologist and biochemist 🧬 Postdoctoral researcher at University of Toronto and OICR
Joined September 2020
- Tweets84
- Following176
- Followers43
- Likes155


AnderDN retweeted

Aún estás a tiempo si mañana tienes un hueco de apuntarte a uno de nuestros Bio::Bytes sobre ajuste de p-valores!
17 Fecha: 8 de octubre. Horario: 16:00-17:00. Lugar: Edificio Silicosis, ISPA-FINBA (Av. Roma s/n). A que esperas, inscríbete ya!

AnderDN retweeted
Hemos llegado al core del análisis del transcriptoma, ¿te lo vas a perder? Te esperamos el 23 de abril a las 16h en @FINBAsturias
Inscripciones: forms.gle/irWfvzp8zyFZnJ2j7
Conducido por: @dn_ander

AnderDN retweeted
¡Anunciamos la primera sesión del ciclo Bio::Bytes!
📅 Fecha: 19 de febrero. 🕓 Horario: 16:00h - 17:00h.📍Lugar: Edificio Silicosis, FINBA (Av. Roma s/n). 🎟️ Acceso: Libre hasta completar aforo.
Conducido por: @dn_ander
Inscríbete en: forms.gle/YKLSQ5yEoML65Hku9

AnderDN retweeted

La Plataforma de Bioestadística y Epidemiología @Bioestad_ISPA organiza un nuevo Curso de Bioestadística básica, del 4 de febrero al 25 de marzo.
25 plazas disponibles, que se adjudicarán por orden de inscripción.
Más información e inscripciones en ispa-finba.es/curso-bioestad…

AnderDN retweeted

Big, beautiful trees!!
SMART-PTA for whole-genome+transcriptome on thousand of single cells from the normal human esophagus 🤯 Massively scaling up the power of scWGS to build deep phylogenies and chart somatic evolution from birth throughout life.
biorxiv.org/content/10.1101/…

AnderDN retweeted

Many cancer methylation studies make subtle but fatal mistakes:
❌ Feature selection across train+test (xitter.cf/jmschreiber91/status/1…)
❌ Ignoring confounders
❌ Weak model evaluation and robustness
The result? Biased predictions that don’t generalize.🧵We set out to do it right.

Thrilled to see my postdoctoral work published in @CellGenomics!
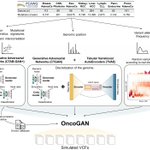
OncoGAN generates simulated genomes to train genomic analysis tools —without the confidentiality risks of real genomes.
News story: oicr.on.ca/ai-generated-geno…
Paper: cell.com/cell-genomics/fullt…
#Genomics #Cancer #AI
AnderDN retweeted
IV Curso de Introducción a R, organizado por ISPA-FINBA y @grupoRasturias del 23 de septiembre al 25 de noviembre.
Más información e inscripciones en ispa-finba.es/iv-curso-de-in…

AnderDN retweeted
Un año más, desde el Grupo de R de Asturias, y en colaboración con @FINBAsturias, lanzamos el Curso de Introducción a R - ¡y ya va por su cuarta edición! 🎉
Si te interesa empezar a manejar datos y crear figuras con R, no dudes en apuntarte.
¡Os esperamos!
Más información👇

AnderDN retweeted

🚀 What do genomic Transformers actually learn about biology?
•What knowledge do they hold at random init, after pre‑training, and following fine‑tuning?
•We dove deep into every attention head to find out.
📄 Preprint live now “Interpreting Attention Mechanisms in Genomic Transformer Models: A Framework for Biological Insights”
👉 biorxiv.org/content/10.1101/…
Code: github.com/meconsens/genome-…
⸻
🛠 What we built
•Scalable mapping between attention heads & biological features (e.g. TSS, GC content, GO terms)
•Label‑specific analysis to uncover context‑dependent attention patterns
•GPT‑4 summaries for every head’s attention‑feature links
•Head ablation experiments to test causal impact on predictions
⸻
🔍 Key discoveries
•Even models with random DNA weights show biologically meaningful heads
•Fine-tuning refines, not erases, what pre‑training learned
•Tokenization matters: overlapping vs non‑overlapping k‑mers affect interpretability
•Heads tied to biology are more predictive than heads with no feature links
•Some heads show negative learning—they attend to absence of features
⸻
🧠 Why this matters
We now have tools to ask: what genomic models learn—and which heads are driving predictions. A big step toward truly interpretable, testable genomics AI.
⸻
⚠️ Limitations to keep in mind
•Not every head is interpretable
•Attention patterns can be unstable across layers & tokens
•Interpretations explain only part—not all—attention variance
•GPT‑4 summaries are helpful but can overgeneralize
•Results depend heavily on annotation quality & biological context
⸻
TL;DR: We’re bringing interpretability to the core of genomic Transformers—revealing biologically meaningful attention heads, unpacking how tokenization & training shape them, and letting us pinpoint which ones actually matter.
🎉 Huge shoutout to the incredible lead authors in the lab, Mica Consens, Vivian Chu, Ander Diaz-Navarro for driving this forward!
@VectorInstitute @UHN_Research @UofT


AnderDN retweeted

🔍 ¿Te suena virtualenv o conda? Pues en R también tenemos una joyita: ¡renv! 💎
Desarrollado por Posit, renv te permite crear entornos virtuales (📦 conjuntos de paquetes aislados) para que tus proyectos en R sean:
✅ Reproducibles
✅ Fáciles de compartir


AnderDN retweeted
El 2º premio (100€) se lo ha llevado, también desde la Universidad de Granada:
👧Laura Jiménez
Os dejamos aquí unas cuantas imágenes de su propuesta:


AnderDN retweeted
El 1er premio (300€) se lo han llevado, de la Universidad de Granada🥁🥁🥁:
👦Óscar Sobén (@oscarsoce12 ) 🤝Thalía Serrano (@kkalith_ ) 👧
Entre ellos han creado una app interactiva con Shiny, la cual os dejamos a continuación para que la probéis:
oscarserver.shinyapps.io/des…

AnderDN retweeted
Exciting News:
Our team — Arman (@arman1sa lead, an AI engineer @UHNAIHUB ) + Nasim Abdollahi — placed 1st in the AIRCHECK Hackathon mini-challenge!
They built a gradient-boosted model with Bayesian optimization to predict binding of DEL-derived molecules to target proteins.
AIRCHECK is a large-scale open-access platform for AI-driven drug discovery, developed by @thesgconline, X-Chem & HitGen, hosting DEL screening data across diverse protein targets.
Thanks to @UHN, @Google, and @UHNAIHUB for supporting this work.
More to come on accelerating hit discovery with ML!
#AI #DrugDiscovery #Cheminformatics #Hackathon


🚀 Only 2 weeks left to join the VI Visualization Contest with R by @grupoRasturias
🏆 Prizes:
🥇 1st: 300€
🥈 2nd: 100€
Show off your #RStats skills and impress us with your best visualizations!
🔗 More info: github.com/grupoRasturias/da…
#Visualization #Contest #DataViz

AnderDN retweeted
🔥 Unveiling the Future of Genomics with Genome Language Models (gLMs)! 🔥
Our comprehensive review, "Transformers and genome language models," is finally published in Nature Machine Intelligence!
Link: nature.com/articles/s42256-0…
Key Highlights:
🔬 The Challenges Addressed by gLMs: gLMs tackle the intricate task of interpreting vast genomic sequences, enabling predictions about gene regulation, variant effects, and more.
🧠 Transformers in Genomics: Discover how transformer architectures, renowned for their success in natural language processing, are adept at capturing long-range dependencies in genomic data, leading to more accurate models.
🚀 Beyond Transformers—Introducing HyenaDNA: Explore innovative architectures like HyenaDNA, which offer efficient long-range genomic sequence modeling at single nucleotide resolution, pushing the boundaries of genomic research.
📊 Comparative Analysis of Models: We delve into the evolution from sequence-to-function models like DeepSEA and Enformer to sequence-to-sequence models such as DNABERT and Evo, highlighting their respective strengths and applications.
⚡ Strengths, Limitations, & Future Directions: Gain insights into the current capabilities of genomic AI, its limitations, and the promising avenues for future research and application.
This pivotal work is the result of a collaborative effort led by Micaela E. Consens (@micaelanonsense ), with contributions from Cameron Dufault, Michael Wainberg (@michaelwainberg ), Duncan Forster, Mehran Karimzadeh, Hani Goodarzi (@genophoria ), Fabian J. Theis (@fabian_theis ), Alan Moses.
@UHNAIHUB @UHN @VectorInst @uoftoront
#Genomics #AI #MachineLearning #Transformers #HyenaDNA #DeepLearning #Bioinformatics #GenomeResearch


AnderDN retweeted
Bueno, bueno.... pues aquí está uno de nuestros eventos más importantes del año.
Nuestro "CONCURSO DE VISUALIZACIÓN DE DATOS CON R"📈📊, anímate a participar y afrontar el reto que proponemos este año.
¡Esperamos ver con que nos sorprendeis!
.
.
Y que corran esos códigos 😎


8/9 A huge thank you to the rest of authors Xindi Zhang, Wei Jiao, @BoWang87 and Lincoln Stein for their contributions and guidance!!!
@ontariogenomics @CANSSIOntario @MoGen_Grad @OICR_news
9/9 More info:
Alongside the OncoGAN models and pipeline, we’ve released 800 synthetic genomes spanning 8 tumor types!
📄 Preprint: tinyurl.com/yepheye3
📂 Datasets: tinyurl.com/28bpd5hs
💻 Code & Docs: tinyurl.com/mr3ku653