



Pinned Tweet
What would a project, framework or language need to provide to maximize effectiveness for AI?
I’m thinking: a large corpus of working examples, the ability to establish fast feedback loops via strong types, good testing culture, good linters/formatters, well written user docs and plentiful examples.
My gut says something like tigerstyle.dev would probably help too.
IME the more guardrails I establish the more effective the LLMs are because there are fewer degrees of freedom for them to get lost in. The faster they can identify when they’ve left the golden path e better the results.

Dan Kubb retweeted

“Rarely is anyone thanked for the work they did to prevent the disaster that didn’t happen.” — Mikko Hyppönen
Dan Kubb retweeted

Caring is the moat, you should feel visceral pain when things are bad or broken and stop at nothing to fix them
Dan Kubb retweeted

You know when you ask the agent to find issues and it finds them, then you repeat and every time it finds new issues.
That’s the entire internet right now.
Cancel your holiday plans, this isn’t going to stop until February.
Dan Kubb retweeted

At this point, if you’re in software and aren’t currently working on a plan for moving to formal verification, it’s irresponsible.
The writing is on the wall. This needs to be your priority now.

New on our Frontier Red Team blog: using Claude to formally verify software at large scale.
Formal verification can prove that code is free of certain bugs, but historically it has only been feasible for small codebases (or required a lot of expert time).
With AI models, however, this is beginning to change. In collaboration with @theoremlabs, we used Claude to prove security properties in over one hundred real-world open-source libraries over the span of a few weeks.
Read our research in full here: anthropic.com/research/forma…

Dan Kubb retweeted

This triggers me... stop calling your AI agents a factory. You're building a product studio. The factory metaphor is the wrong one and let's shed projecting Taylorism on our agents. Why?
- Factories reproduce. Products are invented. If you knew exactly what to build, most of the hard work would already be done.
- Factories optimize for predictability. Product development requires exploration, experimentation, and occasionally throwing everything away.
- Factories break work into repetitive tasks. Products require interconnected decisions. Change one thing and ten others need reconsidering.
- Factories minimize variation. Great products come from discovering which variations actually matter.
- Factories separate design from production. With agents, designing and building increasingly happen at the same time. Don't tame your agents into these small boxes! They are getting annoyed!
A product studio is different and if you can see it that way it changes how you work:
- You start with a vision, not a specification or a task.
- You discover what you're building by building it. And you can do this in spades, it's so fun!
- You explore multiple ideas cheaply, discard most, and develop the promising ones.
- You spend more time reviewing, debating, and refining decisions than producing artifacts.
- You work at multiple levels of abstraction, constantly moving between the big picture and tiny details.
Building products with agents is much more like writing a great book vs assembling a car. You have a story you want to tell. You write, read, rewrite, delete entire chapters, discover better ideas halfway through, and sometimes realize the ending changes everything that came before it.
No one really wants an assembly line producing chapters faster. For the love of your agents, please stop calling them factories.
Dan Kubb retweeted

Day 16/
You can now cache for 12h in the API and for logged in users across Codex & Work we keep cache forever and you don’t have any penalty for coming back to an old conversation or resuming after a few hours and are now guaranteed to hit the cache.


Dan Kubb retweeted

I strongly believe there are entire companies right now under heavy AI psychosis and its impossible to have rational conversations about it with them. I can't name any specific people because they include personal friends I deeply respect, but I worry about how this plays out.
I lived through the great MTBF vs MTTR (mean-time-between-failure vs. mean-time-to-recovery) reckoning of infrastructure during the transition to cloud and cloud automation. All those arguments are rearing their ugly heads again but now its... the whole software development industry (maybe the whole world, really).
It's frightening, because the psychosis folks operate under an almost absolute "MTTR is all you need" mentality: "its fine to ship bugs because the agents will fix them so quickly and at a scale humans can't do!" We learned in infrastructure that MTTR is great but you can't yeet resilient systems entirely.
The main issue is I don't even know how to bring this up to people I know personally, because bringing this topic up leads to immediately dismissals like "no no, it has full test coverage" or "bug reports are going down" or something, which just don't paint the whole picture.
We already learned this lesson once in infrastructure: you can automate yourself into a very resilient catastrophe machine. Systems can appear healthy by local metrics while globally becoming incomprehensible. Bug reports can go down while latent risk explodes. Test coverage can rise while semantic understanding falls. Changes happens so fast that nobody notices the underlying architecture decaying.
I worry.
I wish the discord around AI would move on from:
> humans produce lots of slop, therefore it's ok that AI produces lots of slop
To:
> AI should be expected to produce code that is not slop, superhuman quality and maximizes understanding
Dan Kubb retweeted

This is a very old debate. Functional core+Imperative shell greatly reduces the need for mocks. The problem has always been how to design your software to make it more amenable to tests across all levels of the test pyramid. Every type of tests requires some design.

The value of unit testing was always low if you were writing in a strongly typed language. Integration testing, in particular when you used mocks and injection, was always questionable too.
I think it's entirely possible we wind up in a place where the only test suite you actually must build is the black box testing suite, and adversarial review takes care of the rest.
Dan Kubb retweeted

Your job is finding weaknesses. "I can't help with that" gets in the way.
Abliterated Large V2 by @abliteration_ai, now on Venice.
Dan Kubb retweeted

What worries me about the future of programming is you see this and don’t immediately know there must be something wrong with the results or what you actually measured.

I've had agents implement and optimize the Campfire web app in Elixir, Go, and Rust. Yes, Ruby is the slowest. I didn't care about that when the pay-off was huge in terms of productivity and developer joy. But if you're no longer reading the code? github.com/basecamp/once-cam…

Readers added context they thought people might want to know
The shown benchmarks use non-equivalent implementations: Elixir routes all DB queries through a single GenServer with Redis for jobs (retained from Rails), while Rust uses in-process queues, omits CSRF tags/fields, and applies other caching changes.
github.com/basecamp/once-…
raw.githubusercontent.com/basecamp/once-…
github.com/basecamp/once-…
github.com/basecamp/once-…
x.com/zachsdaniel1/s…
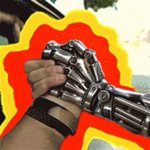
ChatGPT must have a sense of humour.
I wanted to make a new slack emoji with a teamwork emoji as a base, and asked it to change the fist in the foreground to be the Terminator hand.
This is what it gave me instead:
🤖 Made with AI

Dan Kubb retweeted

Delegating all of your thinking to AI will make you dumb and your outcomes will always be average. Use it as an assistant whilst continuing to use of your brain. Failing to do so guarantees atrophy of neural networks. Look at what happens to your body when you don't exercise.

Dan Kubb retweeted

Apparently all of these “AI is escaping containment” stories are actually just AI researchers not knowing jack squat about the absolutely most basic security practices.
Dan Kubb retweeted
one thing I can tell you about agents
no amount of ponytail or Matt Pocock skills in the initial prompt is useful. All models (Astra, fable, opus 5.5) write far more code than required
But *after* they raise the PR if you take a fresh context, a little clear head and start another agent asking it to break down what it can cut down, what it can remove from that PR you’ll go a long way
You’ll have to put in the work and the extra tokens, if you want to stop your repos from bloating. And this is not the most optimal state of things - but tons better than tacking on a “make no mistake” style skill hoping it will make the model stay concise. It just won’t.

Dan Kubb retweeted

Increasingly convinced: people who do best with agents are those that are good at shipping things in small pieces.
Someone who could ship a feature in 4 commits going to main now does better with agents than the guy who always ended up with a 6k PR on Friday afternoon.
Dan Kubb retweeted

We aren’t moving beyond code btw. You’re either a bad engineer or too inexperienced to tell when the models are fucking everything up
the code is the specification, not language. What’s happening is that the models are filling the gaps with assumptions embedded in its weights.
And if you aren’t reading the code, you’re missing ALOT