

AI research & product @meta tbd, @instagram | before: @GoogleDeepMind @YouTube @Google news/discover, search ranking, ads | CS & Econ @yale
san francisco
Joined October 2017
- Tweets94
- Following2.4K
- Followers679
- Likes947



Devansh retweeted

$META Devansh Tandon reveals the tokens-in, engagement-out flywheel behind Meta's recommendation system, where better models lift Reels watch time 30% and the monetization pays for the next training run
"These scaling curves aren't just academic research. They're driving real product impact at scale for some of the biggest consumer businesses in the world."
"Here's a couple of examples I have from Meta's recent earnings reports. Instagram Reels had a strong quarter, 30% year on year watch time."
"And the optimizations we made to improve the quality of recommendations included simplifying our ranking architecture to enable efficient model scaling and longer interaction histories to identify a person's interests."
"We doubled the length of user interaction sequences used for training Instagram and increased the richness of each user interaction."
"So these are direct parallels to the power law scaling curves for LLMs."
"And I want to introduce this idea of a flywheel of tokens in engagement out, which is what's powering all of these recs models scaling."
"You train a model, you then run inference on it, which is the tokens in, that recommendation model results in better content recommendations, it drives consumer engagement, daily active users' time spent, it translates to monetization and ads or subscription, which pays for the next model training run."
"And so every step on the scaling curve is one loop around this flywheel, and a lot of consumer apps are spinning this core flywheel at the heart of their business. So we have a long way to scale these recommender systems."
_______
For the full breakdown of the lecture on Meta's ads recommendation system: firesidealpha.substack.com/p…

Mark Zuckerberg says Meta trains discretion into Muse so it can book a restaurant reservation without disclosing your allergy or pregnancy, something off-the-shelf coding agents skip
"So, I mean, you have to train that into the model. I mean, just like any other capability, it needs to be good at knowing, you tell it a lot of things and then you want it to go achieve your goals."
"But let's say you want it to go get you a reservation at a restaurant, and you're trying to find a good restaurant, but maybe you have some allergy. But you may not want to disclose the allergy, or if you're pregnant or something like that."
"But the Muse will know if you tell it. And you're going to want it to be able to do the job but while disclosing as little information as possible."
"So that's a specific skill. And it's something that's kind of basic social skills or common sense that people have."
"But if you're just building a coding agent, most of these companies haven't trained that in. So that's the type of thing that we can do because we're doing the full stack, right?"
"Because we're training the model, we're not just taking someone else's model off the shelf and trying to build a scaffold and an agent around it. We trained the whole model specifically to be good at that."
_______
For the full set of takeaways from Meta's Connect Keynote: firesidealpha.substack.com/p…
Lag7 has been a dependable trade, I think LagLab might be the next one.
Labs: top 5 frontier labs - Anthropic, OpenAI, Google, Meta, SpaceX
Lag: labs naturally have lag periods due to the model development cycle (~6mo pretrain, 1-3mo posttrain/RLs). mode lag can be measured with your favourite benchmark, AA Index as starting point
major transitions mean the lagging labs are underpriced. this was meta during the llama --> muse transition period. today it's google in the gemini 3 --> 4 transition.
crossover funds investing in AI should evaluate, am curious to see backtest returns


personal agents are finally here: instinct taking over the timeline, grok bot, poke & many others. will be interesting to see meta & google to release their consumer agents later this year
instict's manifesto claims: "The interface is simple: there are no new interfaces."
i think agents are now too powerful to constrain to a text/voice interface. in my daily use, i kick off an agent team, have it build a dashboard to monitor progress along the way, and websites to explain the final output. i'm barely consuming information from the base claude code or codex chats, just using them to direct agents.
coding is free now, a new personalized interface can be created for every task, while maintaining a consistent design language. it'd be exciting to see a personal agent that takes the opposite view:
The interface is simple: there is a new interface for every task.
Opus 5 framed as frontier intelligence (fable) at half the cost is a direct response to K3

What does this mean? Initial reactions:
1/ Frontier price pressure
A price war was already simmering between Claude/Fable and Codex/GPT, accelerated by Muse Spark 1.1, now gets a second front. Open weights ~1 month behind the frontier will pressure pricing power for the labs planning to IPO soon. Frontier labs will continue to move up to higher value tasks / app layer to keep pricing power on the hardest 10% tasks. The durability of the ‘frontier premium’ is the biggest question.
2/ Model garden alternative for coding agents
Tokenmaxxing has given way to model gardens once companies received their coding agent bills, which have exploded with the latest frontier models. Enterprises now want control over their agents and their spend, and open weights can now be a real substitute, not just a fallback. Many will prefer a near-frontier, self-owned option to complement Claude/Codex.
3/ Open source as statecraft
Xi’s speech alongside the K3 release demonstrates China’s strategy to deliberately open source frontier models to commoditize the model layer US lead. In the global develop market, Chinese open weight models are established as the default stack, the US is losing the open ecosystem race outright.
Kimi K3 is an exciting release, a 2.8T open weight model with 1M context.
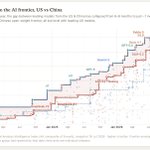
On benchmarks, it collapses the gap between the US frontier & the Chinese open-weight frontier. A year ago that gap was 6-8 months, but with K3 it is only ~1 month. K3 isn’t as token efficient, so likely won’t be cheaper off the shelf.
I charted the US v China frontier using the Artificial Analysis Intelligence Index from 2024. K3 is now comparable to leading models on agentic coding.

note: benchmarks don’t tell the whole story, i used artificial analysis for a clear frontier chart but the real performance is jagged – and depends on the applications being considered. Coding / long horizon benchmarks follow similar trends.
from vibe checks, i’m most impressed by Kimi K3’s grit & persistence to keep going on longer horizon tasks. the model is quite verbose and could be more token efficient.
note: benchmarks don’t tell the whole story, i used artificial analysis for a clear frontier chart but the real performance is jagged – and depends on the applications being considered. Coding / long horizon benchmarks follow similar trends.
from vibe checks, i’m most impressed by Kimi K3’s grit & persistence to keep going on longer horizon tasks.

I'm speaking @aiDotEngineer today, for the LLM-RecSys track.
The biggest consumer apps in the world are content feeds (Instagram, YouTube, Facebook, TikTok), and recommendation model improvements drive most of their engagement & revenue growth.
These recommendation systems are being transformed and rebuilt into LLM-native recommendation systems. I'll share frameworks + a recipe to train LLM-native recs models. LLM-native models enable new product experiences: steerable & interactive recommendations that put users in control of their algorithm.
LLM-Recs is the largest application of AI for consumer apps, and remarkably token efficient when compared to AI chat apps.

4/10 of the best consumer apps are content feeds, where the growth / addictiveness is driven by the recommendation system
Instagram, YouTube, TikTok, Facebook
I've now worked on the algorithms behind 3/4
(just missing tiktok)

WhatsApp may be the statistically best app we've ever made.
It's a product manager's dream with its unparalleled addictiveness (DAU / MAU) of 87% and stickiness (M1 retention) of 86%, both #1 in the world while having the #1 most monthly active users for any non preinstalled app of 2.7B users.
Here are the top 25 most used apps in the world by MAU on both these metrics. Some surprising observations:
— There are now 15 1B+ user apps in the world, 8 by Google, 4 by Meta.
— The 3 that aren't are TikTok, Telegram (!) and ChatGPT
— Telegram has more users than Spotify, Pinterest, Netflix, Amazon, Snap!
— ChatGPT's one month retention is #5 after WA, Instagram, Chrome and Youtube. 2yrs ago, it was been #20 by M1 retention
— Shopee, a shopping app in southeast Asia, is huge and retains users better than Amazon!
Useful way to break down consumer businesses especially within certain categories (X vs Reddit vs Threads is a good one). It's shocking how few new apps have been able to break through in the past 10yrs.

so cool!
i spend O(100m) tokens daily working with agents through interactive explainers
core loop:
1/ search: code / papers / documentation
2/ visualize html to understand
3/ kick off coding agents to build
4/ understand agent progress through dashboards

2/
Check out how Gemini 3.5 Flash instantly digests dense academic papers and autonomously codes a fully interactive, visual website explaining the intricacies of the research. It's an incredible stress test that seamlessly merges massive long context, deep reasoning, complex coding, and ultra-low latency.
It really helps you distill papers down to their essence and aid your understanding!
Jensen highlights China's dominance of the open source frontier, the only AI CEO who can speak the truth
China disagreements hinge on:
1/ takeoff timelines
2/ taiwan timelines
Biggest mystery: what was Mythos really trained on?

The Jensen Huang episode.
0:00:00 – Is Nvidia’s biggest moat its grip on scarce supply chains?
0:16:25 – Will TPUs break Nvidia’s hold on AI compute?
0:41:06 – Why doesn’t Nvidia become a hyperscaler?
0:57:36 – Should we be selling AI chips to China?
1:35:06 – Why doesn’t Nvidia make multiple different chip architectures?
Look up Dwarkesh Podcast on YouTube, Apple Podcasts, Spotify, etc. Enjoy!