

Building 8-9 figure AI Operating Systems
Melbourne, Victoria
Joined February 2020
- Tweets9.4K
- Following290
- Followers30.2K
- Likes12.1K




Pinned Tweet
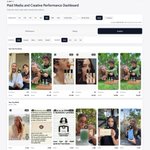
For the next 24 hours you can grab my Meta Ads Performance Dashboard Blueprint that breaks down your funnel
from impressions to booked calls and shows you exactly where conversion is leaking
Comment "META" and I'll DM it FREE
(Must be following)

i think we’re about to stop measuring coding agents by how much context they can hold
and start measuring them by how much context they can ignore
we’ve seen agents make worse decisions because an old implementation note or stale assumption was still sitting somewhere in context
the agent does not need:
every Slack thread
old PR
meeting
document
file in the repo
it needs the smallest set of facts required to make the right decision
more context feels safer
until one stale sentence buried 80,000 tokens ago changes what gets built
context engineering is slowly becoming context deletion
Lian Lim | Dashboard & AI Automation Expert retweeted
the biggest lie in automation is “it ran successfully”
we had workflows returning 200
no errors
green executions
everything looked healthy
the output was still wrong
wrong field mapped
wrong record updated
wrong assumption upstream
the automation didn’t fail
the validation did
since then i care less about:
“did the workflow run?”
and more about:
“did the thing we expected actually happen?”
green logs are not proof
we added another rule to Claude Code after watching agents “fix” their own failing tests:
the agent that writes the feature does NOT get to rewrite the test that proves it works.
sounds obvious.
until you watch an agent:
→ change the implementation
→ break the test
→ rewrite the test
→ get green
→ confidently tell you it passed
green is meaningless if the same agent controls both the answer + the exam.
our rule now:
builder writes the change
reviewer gets fresh context
tests stay untouched unless the PR is specifically about tests
human still owns the merge
AI coding gets way safer when every agent has something it is NOT allowed to touch.
in two weeks, Shopify let AI build the store and let AI do the shopping.
October 1: Canvas.
you describe the store and Shopify's Sidekick edits the live theme code while you watch.
it's desktop only for now.
third party themes and app blocks aren't supported yet.
October 13: AI shoppers.
customers can connect ChatGPT or Claude to their Shop account, search 1B+ listings and check out with Shop Pay.
the buyer still approves every purchase.
one replaces the person building your homepage.
the other replaces the person browsing it.
what changes for operators:
→ theme and CRO agencies lose the easy work first
→ product titles, specs and stock become the sales pitch
→ agent orders skip your Meta and GA4 funnel entirely
two things to check in your Shopify admin this week:
→ whether you're auto enrolled in new agentic storefronts, because merchants can turn it off
→ which products are unlisted, because opting out of the catalog doesn't stop normal crawling
your homepage used to be the storefront.
now it's your product data.
asking Claude Code nicely in a prompt is not a guardrail.
the agent is fast.
these decide what it's allowed to be fast at.
1. branch from main, stop at the PR
it opens a pull request and stops there.
a human merges, so it never steps on another dev's open branch.
2. CLAUDE. md in every repo
the client's stack and the files it must never touch.
it reads this at the start of every session.
3. deny rules for the dangerous stuff
.env files and destructive commands are blocked in settings.
asking nicely in a prompt is not a guardrail.
4. plan before it edits
it writes the plan first.
we read it before a single file changes.
5. a hook on protected files
a script runs before every edit and blocks the files that matter.
the agent writes the code.
the repo decides what ships.
73% of developers using AI coding assistants now use them daily
i expected that number to be high
the number that surprised me was this:
only 20% use AI for deploying, operating or troubleshooting production systems
which kinda explains where vibe coding is rn
we trust agents to write code
we trust them to debug code
but the second prod, infra, permissions + real customer data get involved...
humans suddenly want the steering wheel back
that gap is probably where the next wave of developer tools gets built
not better code generation
better ways to prove an agent is safe enough to ship
curious where people draw the line rn

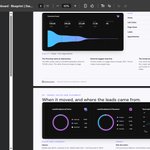
i built a Meta ads dashboard that showed a client where 724.5K clicks went
most brands never see that drop-off because their reporting can't show it
the funnel view changed how they buy media:
→ clicks to link clicks: 60% drop
→ link clicks to page views: 20% drop
→ page views to leads: 93% drop
each stage is a different problem with a different fix
creative problem, landing page problem, offer problem
one funnel view tells you which one is bleeding
the rest of the build:
→ CPM, CPC, CPL tracked live across every campaign
→ 33.6M impressions across 263 campaigns
→ device split that revealed 95.8% of leads come from mobile
→ creative table ranked by spend, link clicks and CTR
$1.1M in spend, 1,790 ads, one screen
if you want to build a similar funnel view for your ad account
Comment “DASHBOARD” and I’ll dm you the blueprint

the easiest way to waste money in ecom happens before the campaign even launches
- marketing decides what to push
- sales has retailer promos running at the same time
- operations knows the stock is already tight
and those three facts live in different places
we built one operating loop around that problem
112+ campaigns and key moments
66+ products across 8 markets
312 retailer promotions
before a campaign gets committed, the system checks:
→ what product is being pushed
→ which market it is for
→ what retailer promos overlap
→ how much stock is available
→ whether planned demand outruns supply
if stock is tight, the campaign gets flagged while there is still time to change the plan
the useful part is simple
marketing can make a better decision before spend goes out
this is the kind of automation i think more brands should be building

hard question for security + platform people
google is now giving gemini coworker agents their own workspace account
their own:
→ company email
→ calendar
→ drive
→ directory identity
and i think this is where ai agents start becoming an actual infrastructure problem
because once an agent has an identity, somebody has to answer:
who owns its permissions
who approves access
where do its secrets live
what happens when it changes role
who reviews what it did
how do you offboard it
and who is accountable when it makes the wrong call
my current view:
every serious production agent should have its own identity, scoped permissions, audit trail and kill switch
i would not want it quietly borrowing a human account
security people
dedicated agent identity or delegated human access
which one survives in production?
i think multi-model routing is getting overhyped
google’s new gemini agent can choose between gemini and claude depending on the job
sounds ideal
until you’re the person responsible for the production system
different models can mean different:
→ tool-call behavior
→ schema adherence
→ refusal patterns
→ latency
→ caching economics
→ failure modes
→ eval results
you save money on the easy calls
then inherit another layer you now have to test every time a model changes
for people actually running agents in production:
has multi-model routing genuinely made your system better
or did you eventually pin each workflow to one model and stop being clever?
if these three launches are any signal, ai agents are about to get much more modular
anthropic dropped haiku 5.5 for cheap, high-volume work
jev is getting attention for fast bounded decisions
and gpt-6 can now build the interface the human actually interacts with
put those together and an agent starts looking less like “send everything to one giant model”
and more like this
1 → cheap model reads + extracts the messy stuff
2 → decision model chooses the route, tool or escalation
3 → normal code executes the action
4 → frontier model gets called when the problem is actually hard
5 → gpt-6 generates the ui when a human needs to inspect or decide something
we spent the last few years asking one model to read, think, decide, write, route and explain everything
now those jobs are starting to split apart
that architecture is way more interesting to me than any single model release today

claude code can now rebuild itself
describe a feature in plain english and it builds it into its own interface
i wrote up how to build your first mod tonight + the 7 i'd build first, with the exact prompts
comment "MODS" and i'll send it


jev launched 20 days ago
wsj says it’s already processing around 1 trillion tokens a day
and being used by roughly 25% of fortune 500 companies
then openai announced decisions api
that sequence is worth paying attention to
for years we’ve been using giant llms for tiny software decisions
→ which queue should this ticket go to
→ which tool should the agent call
→ is this action risky
→ should this request escalate to a human
jev’s bet is that these aren’t writing problems
they’re decision problems
- typed answers
- probabilities
- milliseconds
then normal code decides what happens next
if this architecture keeps winning, ai stacks may start splitting into two layers
llms for reasoning + generation
decision models for routing + control
the question i keep coming back to:
how much of what we currently send to an llm never needed an llm in the first place
the ai agent i’d show a trades business owner first doesn’t write emails
it wakes up at 5am and plans the day
one van has 102 suburbs it can route to across a service area roughly 270km north to south
but the same-day limit is only 50km
so the agent looks at the open jobs, works out where they actually are
and groups nearby work before the owner starts driving
the rules are pretty practical
→ 50km max spread for jobs on the same day
→ job duration changes by service type
→ 30 minutes left between visits
→ road order calculated using actual driving distance
→ full days disappear from the customer booking page
the part i found interesting is in the historical job data
across 176 completed jobs, 40 of the 42 multi-job days were already concentrated within one or two suburbs
the owner already knew what a good day looked like
the knowledge was just sitting in his head
we turned that judgement into a system
the agent prepares the run

Check out full build case study ↓
dashboard-lim.com/case-studi…