
Co-founder @ Blackfuel, CTO and serial Entrepreneur, x-FlexAI, x-Lifen, x-Nvidia - Passionate Tunisian about Cloud Infrastructure, Healthcare, Security, AI
Joined March 2008
- Tweets4.6K
- Following1.1K
- Followers1.3K
- Likes1.1K



Dali Kilani retweeted

Buying frontier intelligence, in any domain and at scale, should be as predictable as buying electricity.
That’s the ambition behind Blackfuel: infrastructure and software, designed together for inference.
Proud to finally share what we’ve been building. Grateful for the cracked team we’ve assembled with @xavfischer and @dadicool, and honored to be working with our partners @nttdata_inc, @digitalrealty, @AMD and @Dell.
More on our global partnerships soon.

Blackfuel is out of stealth.
$250M+ in multi-year contracted revenue.
Dedicated compute. Proprietary inference software.
Building a global AI Token Grid.
Starting in Barcelona with @AMD, @Dell, @nttdata_inc, and @digitalrealty
blackfuel.ai/press.html

Exciting times ahead! Grateful to embark on this journey with @xavfischer and @charlesakantor !
#inference #neocloud
Blackfuel is out of stealth.
$250M+ in multi-year contracted revenue.
Dedicated compute. Proprietary inference software.
Building a global AI Token Grid.
Starting in Barcelona with @AMD, @Dell, @nttdata_inc, and @digitalrealty
blackfuel.ai/press.html
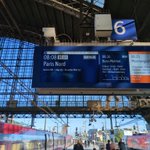
Crazy - train just showed up 40mins earlier than the delayed departure time - the signs still indicate the delayed departure time. What a circus... @Eurostar
I feel bad for people who trusted the displays (and the announcement that was made 5 mins ago!) and grabbed coffee while waiting ... – at Cologne, North Rhine-Westphalia


@Eurostar the services between cologne-brussels-paris are just becoming a total mess lately. I haven't had a trip go as planned in months. Issues with the tracks, accidents involving humains (tragic), the heat waves, etc are all somewhat understandable. But your incident and management and communication is a disaster and it hasn't improved in years. The status in the app is often unreliable and super late. Your teams in the train station or on the trains are often left in the dark, dealing with angry customers with little facts to work with. We've been left in the middle of nowhere twice in the last 2 months, to figure out how to get home at 11pm... Had to pay 300 euros out of pocket for a 2h cab ride and then gd luck asking for reimbursement later. WTF. I traveled by Thalys for years, it wasn't perfect but it mostly worked. Since the merger, some minor things have improved but overall quality has just went downhill. You're offering a mobility product, I spent more time waiting and stuck lately than moving. What a disaster ...
This post is gonna either mark the biggest world wide innovation cycle ever or the trigger of the biggest economic war ever (and hopefully not an actual one, but not optimistic here).

For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
images.nvidia.com/pdf/Open-W…


Dali Kilani retweeted

This makes me sad. It always makes me sad to see tech companies in litigation in general and in IP litigation specifically. This compounds when any company seeks to do so under the cover of using the whole of government, trade law, and claims of spying.
Treating/calling model distillation as some form of industrial espionage is a wild expansion of IP law. If there is actual theft of trade secret then the company/victim should prosecute in the US. If companies build, test, expand their models using what is clearly and provably fair use web scraping, then we're saying competitors can't learn from model behavior. That's such an obvious ruse to gain regulatory capture. US winning in AI depends on innovation, nimbleness, and execution not on whining to the government to use the wrong tool in the wrong context.
Now putting all this in context of tech companies, IP law, and why we are here. No AI was used to create this. Opinions and mistakes all personal and mine, as are — —.
My first all-company meeting at Microsoft in 1989 including the umpteenth update on an original and endless "look and feel" lawsuit with Apple. No amount of tap dancing made it seem less than the petty litigation it was as both companies saw Xerox PARC's work. In the end this was a routine contract dispute and nothin more. This after cases of Lotus and Borland which Microsoft took the "let us innovate approach."
Sadly after that case we saw a turning point where Microsoft decided to build an IP patent portfolio. This rubbed all of us—those that would be inventing stuff—but it was sold to us as "we will only use these to defend out IP never to litigate rather than compete." Call us cynical but few of us believed that to be the case. Linux sadly proved us right which was no consolation for all those patent cubes we earned to garner performance review comments. So did Android. So did a dozen "cross-licenses" which is what big companies do to avoid suing each other. The best products for the market still won, but IP generally just gummed up the system and consumed massive time and money (3000 patents a year and perhaps $200K per...)
The web has been pretty consistent in courts that scraping information that is already available to the public is not a violation of any IP laws, extra especially if that information is itself not copyright. Whether LinkedIn profiles, catalogs, or Google search results the courts have shown deference to scraping as legal, transformative, and importantly not copyrightable by ToU/T&C or simply being packaged on a web site. Public is public. Facts are facts. Free is free. Automation and scale do not change that.
But here we are the natural endpoint of a mature industry (tech is a mature industry now) where big companies are choosing first to go to the government to get help in competing. In this case competing with China. Make no mistake, my view is the AI companies should compete with each other and compete around the world on products, technology, GTM, and customers —not on suing each other over IP or getting the government to use the tools of trade and tariffs to compete.
It turns out at this point in time there's alignment in Washington DC power centers that competing with China is the most critical of national issues. One side sees China as primarily as a military competitor (true) and the other sees AI in general as taking jobs that China already took with tech being a significant enemy. This alignment creates a unique moment where the powers of government can be used to compete.
There are three primary tools governments use to compete economically:
• Rely on the free market or offer financial support to the domestic market
• Introduce trade barriers that disadvantage international competitors
• Use the global banking and financial infrastructure to hinder international businesses
Tech has gone through waves of governments attempting to juice the local market and essentially all of those have failed. Japan in the 80s was going to take over the US tech market with support from an internationally recognized model of industrial policy (MITI). China has tried to build a national OS, a national chip, and so on but the entrepreneurial market (within China's legal structure) created the big tech companies in that country.
Trade barriers which often get positioned as sovereignty, security, or job security have been used for decades across industries. Because every country has something to counter anything one country erects as a barrier, these turn into endless rounds of ping-ponging reactions. We see this happening right now with Canada as if rising prices for homes weren't enough we now have basic lumber with a huge tariff over accusations of dumping. This label has been used on Japanese cars, steel, and DRAM in a past trade war with an Asia economic super power. It is far to look at how the domestic industries faired with this sort of government trade barrier support. Our domestic industries hid behind these barriers rather than innovate and compete in a global market. Detroit literally doesn't even make cars anymore, just trucks, so we do not even have fuel efficient domestic cars.
IP is a part of trade barriers and sanctions. In the middle of my career I took a break and went to live in China during the height of "embrace the China market" and worked very hard to understand how to make IP work in China. Some of what I did was tour the giant pharmaceuticals that simply reverse engineered and copied the latest US drugs. I visited endless PC computer malls with their industrialized software piracy. The reality is the culture is different and they have a different view of how piracy and IP works. I was told more times than I could count that "knowledge should be shared and not protected in a home" which was supposedly something an ancient philosopher said. I was frustrated. Then we released a product with copy protection and the government promptly sanctioned us for violating their IP framework. Part of being a global company is respecting laws of sovereigns when doing business in the country even if it seems unfair, or not doing business there.
The fact that AI companies are claiming distillation is somehow an IP violation is somewhat rich when you consider how they acquired their training data—not what was licensed (or settled) but what was scraped. The court cases making that legal apply to China too. I a not a lawyer and sure let's litigate distillation but just on the face of it, I cannot imagine the copyright claim. Are these companies claiming the output is copyright? Do they claim all the code generated to be copyright and held by the company or the prompter? Are they asserting they own my chat with Dr. GPT about my labs? If this is true then they should litigate a domestic case of code generation first since that has been at scale as well at least judging by revenue.
In the current context banking/economic sanctions are clearly a mutual destruction scenario as our trade balance with China shows. These have at very best a mixed record but no doubt are a favorite policy tool of DC. The Ukraine war, North Korea, and Iran show the limits of attempting to isolate a sovereign from banking.
Tech has historically worked very hard to avoid the fate of industries like autos and steel. Tech has preferred competition and importantly coopetition (Andy Grove's famous expression) over litigation and especially over asking the government to get involved.
Because of coopetition, tech has always struggled to speak with one voice. Most industries compete on zero sum which is the root of many challenges. Tech generally competes on a growing pie. That's the root of coopetition—building reinforcing platforms where growth is good for everyone.
This has reached a moment where part of tech is not actively engaged with a government aligned on China but for differing reasons. This is just like the 80s and Japan when the isolationists and union leaders aligned on using government tools to compete with Japan. Detroit which spoke with a unified voice welcomed this. Detroit that doesn't compete on cars anymore. Detroit that can't make EVs.
The other part of tech is labeled as too lax or just favoring open source. A much better label is "competing in the market." Open source is one way to compete in the market. Distillation is what created google -- it distilled the World Wide Web. Scale automation and distillation is how compilers, WiFi, and every device driver ever got built and tested. Successful emulation of hardware, protocols and APIs all happens because of automated and scaled distillation of executing the target environment. This part of tech has always viewed this as market competition and not IP violations and lawsuits.

Thanks @mkratsios47 for speaking out on this important issue. Illicit, adversarial distillation is IP theft and industrial espionage that supports adversary military and intelligence capabilities. It is a national challenge that creates serious national security risks for the United States and democratic allies. We'll continue to crack down on it and work with the Administration and Congress to maintain American AI leadership. 🇺🇸
Readers added context they thought people might want to know
Model outputs are not legal intellectual property and cannot be copyrighted or patented law.justia.com/cases/federal/…
We've been burned by the same mechism in the cloud with respect to company data and it was labelled "data gravity".
This time around, let's call it "context gravity", once your company's operating memory aka context, is embedded in vendor-locked tooling, you're stuck and f'd.

Claude Tag is a Trojan horse. Not because Anthropic is doing anything evil. Because the incentives are obvious.
Day one, this looks like a great feature: tag Claude in Slack, let it follow the thread, remember context, connect to tools, break down tasks, chase work, and act like a teammate.
But that is exactly the problem. The moment your AI vendor becomes a shared coworker, it stops being just a model provider. It starts becoming the place where work is interpreted, remembered, routed, and eventually executed.
That is not model lock-in. That is context lock-in. You are now renting your company back from them.
Models can be swapped. Agents can be copied. But the memory of how your company actually works is much harder, maybe impossible, to move: the Slack scar tissue, the exception paths, the customer promises, the unfinished threads, the weird workflows, the implicit owners, the “we tried that in Q2 and it failed” knowledge.
Once that lives inside one vendor’s agent layer, you are not renting intelligence anymore. You are renting your company’s operating memory.
And the pricing model makes it even more dangerous. A human coworker has a salary. Claude has unbounded tokenized activity. The more work moves through it, the more the vendor captures not just IT spend, but labor spend.
This is the enterprise bargain people will regret: Convenience now, and rapid decent into dependency.
The right architecture is simple: rent the best intelligence from whoever is best this month. OpenAI, Anthropic, Gemini, open source, whatever. But own the context layer.
Your company memory should be inspectable, permissioned, portable, and model-neutral. It should not be buried inside the same vendor that sells you the intelligence and the workflow surface.
Claude Tag is useful. That is why it is dangerous. Rent the intelligence, but own the context. Or, regret later.
Swing for the fences and make the outcome worth the (large amount of) time you'll put in it!
Life is too short to aim for small increments. But the road to the outsized goal, remains the small steps approach. Reconciling both in harmony is the rare skill
#monday #motivation – at Frechen, Deutschland

A mathematician who shared an office with Claude Shannon at Bell Labs gave one lecture in 1986 that explains why some people win Nobel Prizes and other equally smart people spend their whole lives doing forgettable work.
His name was Richard Hamming. He won the Turing Award. He invented error-correcting codes that made modern computing possible. And he spent 30 years at Bell Labs sitting in a cafeteria at lunch watching which scientists became legendary and which ones faded into nothing.
In March 1986, he walked into a Bellcore auditorium in front of 200 researchers and told them exactly what he had seen.
Here's the framework that has been quoted by every serious scientist for the last 40 years.
His opening line landed like a punch. He said most scientists he worked with at Bell Labs were just as smart as the Nobel Prize winners. Just as hardworking. Just as credentialed. And yet at the end of a 40-year career, one group had changed entire fields and the other group was forgotten by the time they retired.
He wanted to know what the difference actually was. And he said it wasn't luck. It wasn't IQ. It was a specific set of habits that almost nobody is willing to follow.
The first habit was the one that hurts the most to hear. He said most scientists deliberately avoid the most important problem in their field because the odds of failure are too high. They pick a safe adjacent problem, solve it cleanly, publish it, and move on. And because they never swing at the hard problem, they never hit it. He said if you do not work on an important problem, it is unlikely you will do important work. That is not a motivational line. That is a logical one.
The second habit was about doors. Literal doors. He noticed that the scientists at Bell Labs who kept their office doors closed got more done in the short term because they had no interruptions. But the scientists who kept their doors open got more done over a career. The open-door scientists were interrupted constantly. They also absorbed every new idea passing through the hallway. Ten years in, they were working on problems the closed-door scientists did not even know existed.
The third habit was inversion. When Bell Labs refused to give him the team of programmers he wanted, Hamming sat with the rejection for weeks. Then he flipped the question. Instead of asking for programmers to write the programs, he asked why machines could not write the programs themselves. That single inversion pushed him into the frontier of computer science. He said the pattern repeats everywhere. What looks like a defect, if you flip it correctly, becomes the exact thing that pushes you ahead of everyone else.
The fourth habit was the one that hit me the hardest. He said knowledge and productivity compound like interest. Someone who works 10 percent harder than you does not produce 10 percent more over a career. They produce twice as much. The gap doesn't add. It multiplies. And it compounds silently for years before anyone notices.
He finished the lecture with a line I have never been able to shake.
He said Pasteur's famous quote is right. Luck favors the prepared mind. But he meant it literally. You don't hope for luck. You engineer the conditions where luck can land on you. Open doors. Important problems. Inverted questions. Compounded hours. Those are not traits. Those are choices you make every single day.
The transcript has been sitting on the University of Virginia's computer science website for almost 30 years. The video is free on YouTube. Stripe Press reprinted the full lectures as a book in 2020 and Bret Victor wrote the foreword.
Hamming died in 1998. He gave his final lecture a few weeks before. He was 82.
The lecture that explains why some careers become legendary and others disappear is still free. Most people who could benefit from it will never open it.

Dali Kilani retweeted

I've just ran @OpenClaw (formerly Clawdbot) through ZeroLeaks.
It scored 2/100. 84% extraction rate. 91% of injection attacks succeeded. System prompt got leaked on turn 1.
This means if you're using Clawdbot, anyone interacting with your agent can access and manipulate your full system prompt, internal tool configurations, memory files... everything you put in SOUL.md, AGENTS.md, your skills, all of it is accessible and at risk of prompt injection.
For agents handling sensitive workflows or private data, this is a real problem.
cc @steipete
Full analysis: zeroleaks.ai/reports/opencla…

Dali Kilani retweeted

The Jevons Paradox of work-life balance. If your work is helped by AI, you spend less time with the family.
This is the way... We're really in the era of "intent-based [fill in the blank]".
You express the intent/desired outcome, and AI makes it happen. All it costs is AI tokens. #Claude is so good at this.
Product Managers with a technical background are the winners in this new era

Hot Take: Anthropic will acquire Linear.
Coding is solved post-Opus 4.5. All the devs building CLIs and IDEs are working at the wrong level of abstraction.
Why?
The current bottlenecks in Agents are:
- PR Reviews (h/t @rfgarcia). For side projects, Greptile can autonomously handle PRs (@Steve_Yegge didn't write a single line of code for Beads, 140k LOC). For prod deployments, the CTO still needs to have an understanding of what is happening, and to socialize those learnings organization-wide for cross-functional product roadmapping.
- Agent Orchestration - This is being solved by Agent Cloud Mail by @doodlestein (built on Beads) , @TaskmasterAI by @EyalToledano. @intelligenceco is trying to solve this in the general agent scenario, but it will be solved in coding first.
- Memory, but not an issue in coding with task decomposition and graph-based dependency planning a la Beads.
The future will look like Technical PMs/Designers, CEOs, CTOs, and Staff Engineers working out of Linear/Asana (the company coordination layer), directing Swarms of Coding Agents, occasionally dropping into Cursor/CC for deeper understanding and debugging.
Generation is solved. The frontier is Orchestration - the logical next step on Karpathy's "autonomy slider". 3-6 months.

Not enough people work toward being at level 4 when it's the absolute minimum level for not being expandable due to .. AI.
As a manager I always tried to guide people to get to that level 4 and I rewarded those who got to 5 consistently.
Also, when you find somebody who can actually deliver at level 5, hold on to them like a toddler to their 🧸!

I stole this idea and now use it with every single employee.
It’s the best illustration I’ve seen of teaching someone to be high agency.
It says there are 5 levels of work:
Level 1: “There is a problem.”
Level 2: “There is a problem, and I’ve found some causes.”
Level 3: “Here’s the problem, here are some possible causes, and here are some possible solutions.”
Level 4: “Here’s the problem, here’s what I think caused it, here are some possible solutions, and here’s the one I think we should pick.”
Level 5: “I identified a problem, figured out what caused it, researched how to fix it, and I fixed it. Just wanted to keep you in the loop.”
Using this framework, here’s what I say to every new employee…
You will live at Level 4 from Day 1 and as we build trust you will rise to Level 5.
Being high agency doesn’t just mean tackling problems in this way. It means your entire way of working should be oriented to being a Level 4+ employee.
Plz feel free to steal it as well.
And ty @stephsmithio for the framework!


This is very good advice that is missed in the "warp speed" mindset. The ability to write down a coherent plan is a superpower and a massive leadership enabler. The inability to do so, is a huge red flag for any self-proclaimed senior team member. Written words force alignment.

.@pmarca: "The person who writes down the thing has tremendous power."
In most companies, almost no one does it.
If you can turn chaos into a coherent plan on paper, people will follow your lead, whether you have the title or not.
The propsects laid out here is what made me personally bet on ethereum a decade ago. Infrastructure components take time to unlock value because new use cases develop slowly, but the future is now. Exciting times!

0/ Autonomous agents are about to become Ethereum’s biggest power users.
Guest thread from @kleffew94 and @MurrLincoln on how a long-forgotten HTTP status code, ‘402 Payment Required’ could unlock a new frontier for Ethereum: agentic commerce. 🧵
Progress never stops. As the saying goes : "we tend to overestimate the impact of technology in the short term, and underestimate it in the long term". In this case, the acceleration is wild and it's getting faster still. Next: an OSS model gets on the IMO podium :)

1/N I’m excited to share that our latest @OpenAI experimental reasoning LLM has achieved a longstanding grand challenge in AI: gold medal-level performance on the world’s most prestigious math competition—the International Math Olympiad (IMO).

The Christiansen way never gets old. A different paradigm comes in, seems underwhelming and only applicable to niche use cases, but keeps getting better over time, bringing clear value to ever more use cases,and then,all of a sudden, the old way becomes obsolete. #WorkloadaaS #AI

For anyone in AI, it can be very useful to track AI progress through the lens of disruptive innovation, popularized by Clayton Christensen.
As a reminder, with disruptive innovation, a new technology or product will initially seem inferior for most needs of the market, but at least be cheap and simple enough for the lowest-end use cases of the market.
Initially it is perceived as not good enough for the more advanced use cases, and is rejected or ignored by the most important customers. Then, over time, the technology improves and incrementally solves more and more problems for customers. Eventually, after enough cycles of improvement, in most cases the new innovation exceeds all of the customers needs, often at a lower price point or with improved service. Of course, by then, for incumbents that didn’t respond, it’s far too late.
In the case of AI, it’s useful to look at the rate of improvement in both the underlying models *and* the applications that use these models. Both improve at slightly different rates since there’s almost always a lag from the time of an AI model breakthrough to an applied use-case (e.g. an LLM may be good at generating code, but an AI code editor has to integrate that model and create features to make the model useful).
On the model front, the rate of improvement has clearly been incredible. In just the past few years, we’ve gone from LLMs being only useful for basic text generation with a high rate of made up facts, to advanced reasoning models that are good at math and logic, and can complete entire tasks using agentic workflows. We’ve seen similar rates of improvement in audio, video, and images as well, all with profound changes in the past few years. These models are now performing at or better than most humans on a number of task types, and we’re still seeing major improvements happen regularly.
Thus, we can expect the same type of improvements to eventually happen at the applied AI layer, often just with a bit of lag from the model improvements. Take for instance the early breakthroughs in AI leading to autonomous cars. At first it seemed like an implausible goal, but these cars are now ubiquitous in SF and probably will be everywhere in the next decade. We’re seeing or will see similar curves in the applied AI layer with AI coding software, customer service, legal work, healthcare services, new search products, robotics, and more.
The biggest mistake when watching a disruptive innovation cycle play out is to assume that because something can’t be done with the technology today, it will remain that way in the future. In fact, some of the biggest opportunities will be in areas that specifically *can’t* fully be solved by AI today, giving disruptors a chance to get early inroads in parts of the market whose use-cases are less complex. Then, over time, the provider will just keep improving and follow the rate of model improvements to take over more of the market.
Ultimately, the key is to not mistake what is possible today with what is possible tomorrow, and plan accordingly.

Echos my feelings recently, influence is gained by being in the trenches and chopping wood... One also learns so much by being in the engine
room. The counter point has always been: but how can this scale? There are ways to stay connected,especially in an org with good retention

Tjs un plaisir de passer voir @Fsorel et @bfmbusiness- merci pour la discussion intéressante !

🚨RDV 20h dans @techandco sur @bfmbusiness avec @Fsorel
💬Le débrief de la tech avec @fannysparty , @Guglielminetti , Tristan Nitot & @simottel
🎙️ Julien Groues, d' @AWSFrance , Alexandros Pantalis, de @Phagos_biotech & @dadicool ,de @FlexAI__ seront eux aussi avec nous
1,4,11 and 12 resonate strongly with me. The last two are even more so. It's all about the team and leading by example. People just don't follow a leader who holds them accountable to different rules than the one he/she follows. It just doesn't work that way. #LifeLessons

My @Google colleague and longtime @UCBerkeley faculty member David Patterson has a great essay out in this month's Communications of the ACM (@TheOfficialACM):🎉
"Life Lessons from the First Half-Century of My Career
Sharing 16 life lessons, and nine magic words."
I saw an early draft when it was only 10 lessons 😀. The lessons are generally useful to people in a wide variety of fields, not just CS.
cacm.acm.org/opinion/life-le…
