
A Robotics Company Little Gemma - The fastest LLM engine: https://xitter.cf/t.co/Hbz1R2tSli
Chicago, IL
Joined April 2025
- Tweets206
- Following67
- Followers26
- Likes336




Pinned Tweet
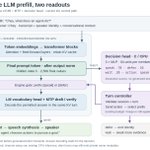
Conversation between Gemma 4 E4B and 12B hybrid models with decision heads. youtu.be/UgsxENT30kU?si=heR2… via @YouTube


The first EXL3 node running the full voice stack. youtu.be/ymtGvz6tHr4?si=MxqH… via @YouTube
Hybrid Gemma4 and JEV like decision head youtu.be/IllniIXMfIo?si=XCY1… via @YouTube

Cortexist retweeted

『指が ”脚” になる』🤌⇒🦿
srl-ethz.github.io/website-f…
AI学習で5本の指を脚と道具に。歩行・転倒復帰・キー操作を実現。手が自ら仕事へ向かう。
#Robotics #PhysicalAI #RobotLearning #ReinforcementLearning #dexterous #manipulation #SoftRobotics #ETH
Gemma4 E4B performs well enough on Jetson Orin to be used for voice conv... youtu.be/yQEc9eTP6Ek?si=QsjL… via @YouTube

SMS & Forward 4.4.0 — first release.
An SMS app that can forward your texts to a computer you own and let your agents get 2FA code and reply.
play.google.com/store/apps/d… via @GooglePlay

Introducing a minimalist TUI app simple-note, coded in Rust. We built and tested it on Arch Linux and Sway, but you can run it in any Linux environment. github.com/cortexist/simple-…


We forked @sigma__dev and adapted it for Linux, modernizing the media player while adding a subtle nostalgic touch. The fork: github.com/cortexist/sigma-f…
Cortexist retweeted

"Understanding Transformers and Attention Mechanisms" is a very interesting paper that presents the Transformer architecture from the perspective of applied mathematics.
It starts by representing text as vectors and explains mathematically how the attention mechanism processes these vectors to encode contextual information. It then develops Multi-Head Attention and shows how the main components of the Transformer architecture are constructed.
The paper also discusses more recent methods designed to reduce the computational and memory costs of attention, including KV caching, Grouped Query Attention, and Latent Attention. I think it is a useful reference for anyone interested in understanding Transformers beyond their high-level architecture and in seeing the linear algebra behind modern language models.
arxiv.org/pdf/2604.00965

Cortexist retweeted

Discrete Fourier Transform by hand ✍️ ~ 12 steps walkthrough below
Here is a little-known secret about the DFT and the inverse DFT: it is just matrix multiplication in both directions, one the transpose of the other, exactly like the forward pass and backpropagation I drew in other examples.
Goal: recover which cosine waves a signal is made of, using nothing but multiplication and addition.
= 1. Given =
Three signals written as sums of cosines, and a fourth, X, that we do not know yet.
= 2. Frequency matrix F =
Let us write the coefficients as a matrix. Each signal is a row, each frequency a column, so A = cos(w) + 2cos(2w) becomes [1, 2, 0, 0].
= 3. Sample the waves =
We read the four cosine waves at ten discrete time points. That word "discrete" is the whole difference between this and the continuous transform.
= 4. Cosine matrix W =
Let us write those samples as a matrix: each frequency a row, each time point a column.
= 5. Frequency to time =
We multiply F by W. That combines the four cosine waves in the proportions F specifies, and the result T is the three signals as they would look in time.
= 6. Transpose =
Let us stand each signal up as a column.
= 7. Time to frequency =
We multiply W by that transpose. Every cell is the dot product of one signal with one cosine wave, which measures how much of that wave the signal contains. Zero means none of it.
= 8. Scale =
Let us multiply by 2/n, with n = 10. The projections come out five times too large, and this is the correction.
= 9. Transpose back =
We turn it back around, and it is F again, exactly. That is the check: the transform recovered the coefficients we started from.
= 10. Now solve for X =
Let us run the same multiplication on the one signal whose recipe we never knew.
= 11. Scale =
We divide by 5 again.
= 12. Transpose back =
And X reads [0, 0, 3, 2], which says X = 3cos(3w) + 2cos(4w).
Note: I originally drew this to show that the DFT is a special case of a convolution layer, its filters fixed to sine and cosine waves rather than learned. No wonder, then, that a convolution layer free to learn its own filters can be trained to process signals.
💾 Save this post!
Cortexist retweeted

One brain. For any robot. 🤖
We’re launching Gemini Robotics 2: our next-generation physical AI bringing full body intelligence to humanoids, advanced dexterity, multi-robot teamwork and more.
Cortexist retweeted
Backpropagation by hand ✍️ ~ 11 steps walkthrough below
Backpropagation is the algorithm that actually trains a neural network, and it is where most people stop following along. It is not calculus you cannot do. It is matrix multiplication, working backward, one layer at a time.
So I drew and calculated one entirely by hand.
Goal: push the loss gradient back through a 3-layer network and land on a new value for every weight and bias.
= 1. Given =
A 3-layer perceptron, an input X, predictions Ypred = [0.5, 0.5, 0], and the truth Ytarget = [0, 1, 0].
= 2. Backprop gradient cells =
Let us draw empty cells for every gradient we are about to compute. The shape of the answer comes first.
= 3. Layer 3 softmax =
We get dL/dz3 straight from Ypred minus Ytarget = [0.5, -0.5, 0]. No chain rule needed, and that shortcut is the whole reason softmax and cross-entropy are paired.
= 4. Layer 3 weights and biases =
Let us multiply dL/dz3 by [a2 | 1]. One multiplication gives the gradient for W3 and b3 together.
= 5. Layer 2 activations =
We multiply dL/dz3 by W3 to get dL/da2. The gradient moves back across a layer the same way the signal moved forward.
= 6. Layer 2 ReLU =
Let us pass it through the gate: keep the gradient where the activation was positive, zero it everywhere else.
= 7. Layer 2 weights and biases =
We multiply dL/dz2 by [a1 | 1]. The same figure as step 4, one layer up.
= 8. Layer 1 activations =
Let us multiply dL/dz2 by W2.
= 9. Layer 1 ReLU =
We apply the same gate again, now on a1.
= 10. Layer 1 weights and biases =
Let us multiply dL/dz1 by [x | 1], and every weight in the network now has a gradient.
= 11. Update =
We subtract, and the network has learned. In practice a learning rate scales this step.
The gradients:
dL/dz3 = [0.5, -0.5, 0]
dL/da1 = [1, -2, 2, -1]
dL/dz1 = [0, -2, 2, -1]
The takeaway: matrix multiplication is all you need. Just like the forward pass, backpropagation is matrix multiplications end to end. You can do every one by hand, slowly and imperfectly, which is exactly why a GPU's ability to do them fast mattered so much to deep learning.
💾 Save this post!