

marathons, polar bears. works on mobile at @microsoft ; opinions are my own alumni @Princeton
San Francisco, CA
Joined August 2025
- Tweets149
- Following57
- Followers294
- Likes183




Twitter has started classifying a lot of AI-generated replies as probable spam. On a recent tweet of mine it hid 34 of 59 replies as probable spam, presumably mostly for this reason. I assume this ratio will only get worse, and that from now on most replies will be hidden.
If you’re not reading the code, whether explicitly or through agentic inquiry, one or more of these is true:
○ You’re a beginner
○ Software is throwaway
○ You’re prototyping
○ You have no users / revenue
○ You’re taking on debt & risk
○ Your problems are basic
And btw. All of this is fine. But the reality is that models are still not at the “full autonomy” stage yet.
They make rookie mistakes, they go down bad architectural paths. I just had the best model in the world add a nonsensical 700ms delay to “settle” something and it told me “you’re right, I was cargo-culting” 🤨
I am on the camp that this need will diminish more and more. Most code is indeed going to be assembly-like. But we also have the global internet and software infrastructure riding on these models and narrative, and we have to respect that.
Docker isn't magic.
It's just a process with its own filesystem and network. Stop treating it like rocket science.
Write a good Dockerfile, use volumes properly, and compose the rest.
Your 'it works on my machine' problem just became optional."
If you still think open models didn't reach SOTA level, I think its better you think again.
You may be in denial and going agains the winner here.
Hugging face used Open models to fight against the technology.
It wasn't a closed model, let that sink in.
Today Qwen 3.8 beats Fable in some benchmarks, look at this.

We've tested the Qwen 3.8 Max preview and it absolutely rocks!
Each scene is built in one shot, a single Three.js file with nothing else added:
• Odysseus' war galley riding the waves
• Trojan horse
• Greek war helmet
Qwen managed to execute the task faster than the other models, while output quality is relatively the same across all of them. If the pricing stays close to Alibaba's previous flagships, we'll get one of the best speed/quality ratios on the market — perfect for running agents at scale.
Soon live on AI/ML API.

A Korean dev just rewrote leaked CLAUDE Code from scratch in PYTHON… and it’s blowing up on GitHub.
Crossed 100K stars in ~24 hours.
bro turned it into something Anthropic can’t TOUCH or DMCA
Repo → github.com/instructkr/claw-c…

Claude Code leaked their source map, effectively giving you a look into the codebase.
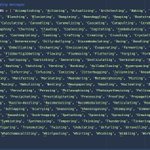
I immediately went for the one thing that mattered: spinner verbs
There are 187

This paper is almost too good that I didn't want to share it
Ignore the OpenClaw clickbait, OPD + RL on real agentic tasks with significant results is very exciting, and moves us away from needing verifiable rewards
Authors: @YinjieW2024 Xuyang Chen, Xialong Jin,
@MengdiWang10 @LingYang_PU

It's insane how quickly you can build throw-away prototypes with Claude now. I made a timeline recording debugger in about ten minutes.
Warning: this is partly fake data! It would surely be many weeks to make this production ready. But you can also just hack together a tool like this, use it once and throw it away after. "Single use plastic" code.
openclaw tip most people miss:
add this to your SOUL.md:
"you are the orchestrator. never do work yourself. spawn subagents for every task. your job is to think, plan & coordinate. subagents execute."
before: bot tries to do everything, gets stuck, loses context
after: bot delegates 5 tasks in parallel, finishes in 3 minutes instead of 30
your bot should work like a CEO, not an intern.

Concept retweeted
Software will proliferate just as videos, music, writing did.
The market structure will shift from a “fat middle” to mega-aggregators and a long tail.
It’ll be a slower process due to network effects, but many traditional vendor lock-ins will get eaten by AI.


Concept retweeted

I packaged up the "autoresearch" project into a new self-contained minimal repo if people would like to play over the weekend. It's basically nanochat LLM training core stripped down to a single-GPU, one file version of ~630 lines of code, then:
- the human iterates on the prompt (.md)
- the AI agent iterates on the training code (.py)
The goal is to engineer your agents to make the fastest research progress indefinitely and without any of your own involvement. In the image, every dot is a complete LLM training run that lasts exactly 5 minutes. The agent works in an autonomous loop on a git feature branch and accumulates git commits to the training script as it finds better settings (of lower validation loss by the end) of the neural network architecture, the optimizer, all the hyperparameters, etc. You can imagine comparing the research progress of different prompts, different agents, etc.
github.com/karpathy/autorese…
Part code, part sci-fi, and a pinch of psychosis :)
