

I ike to talk bout software engineering
Joined December 2019
- Tweets4.1K
- Following1.1K
- Followers392
- Likes14K






Edgar Rodríguez retweeted
The sooner we replace the whole wall of text in markdown the sooner we can stop looking at code reliably
My timeline is on fire, all my favourite creators talking about tech and new/old ideas!
Wonder if TypeScript will get something good out of the whole discussion, some proof system or (test) integrations… 🤞
Week 2 trying to replace Agents "markdown specs":
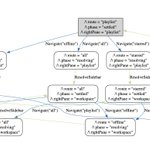
Model TLA+ -> run proof -> graph in .dot -> generate tests -> implement code.
This design can run and get verified, and it is much more readable than any wall of text.


I think the burnout from working with LLMs comes from the language itself.
I bet most devs have high non-verbal and abstract reasoning, using english the WRONG API.
We NEED more non-verbal interfaces for AI, both as input and output.
Graph programming should be here. NOW.
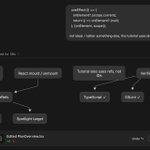
Annotations are quite close btw
is just that they are not shown nicely (as text-reply) in the UI
but it is basically the same idea, a message should be able to reference multiple parts of another message
Dear @thsottiaux @OpenAI I crave for a more "divergent" conversacional chat (voice and text) experience 🫶 where I can branch the conv, same context, just better ergonomics for branching.
Currently i ditched the chat and am using obsidian to talk lol
Dear @thsottiaux @OpenAI I crave for a more "divergent" conversacional chat (voice and text) experience 🫶 where I can branch the conv, same context, just better ergonomics for branching.
Currently i ditched the chat and am using obsidian to talk lol
Codex/ChatGPT, should be just like Telegram:
Messages should allow reply and quote-selected-text , this would simplify a lot the conversation thread.
Also, make the replies like blocks so i can reply to specific sections, the replies are huge, i often want reply to multiple parts simultaniously
I'd love multi-selected-text-reply (?) for lack of a better name.
now that all devs are product managers for llms, i finally can agree with the pm strategies for getting things done comming up.
my fav example of the week: @mattpocockuk /wayfinder
Dear @obsdmd team,
Please make it possible to open obsidian without any vault selected (i dont like to open the last vault selected, often times i open obsidian to open a different vault).
Also, make it possible to "switch" vaults, currently "open vault" keeps the previous vault also open, a bit tedious to close it.
if you are programming with agents, use jj (jujutsu)
jj is to git what typescript is to javascript
1. *Every* file change auto committed
2. Catch up with “jj diff”
3. Review edits with “jj interdiff”
4. Profit
Best workflow, thank me later 👋
Weekly limits reached twice yesterday, I think the bug is there or they massively decresed the weekly tokens? is this inflation or something?

Codex usage limits will be fully reset again in the next hour and we will credit one additional reset into your bank for your own usage over the next 24 hours.
We investigated reports that Codex usage was being consumed faster than expected. There wasn't one central issue, but a few smaller problems compounded for some users.
Here's what we found and changed:
- Actual usage: Auto-review had become more proactive, another change was triggering more subagent work, and background suggestions could run twice or retry too frequently after failures. We reverted the changes and fixed suggestion scheduling, duplicate generation, and retry behavior. This should reduce unnecessary background token consumption while preserving the work users explicitly request.
- Usage reporting: Auto-review was incorrectly appearing as GPT‑5.4 usage, and failed or rate-limited requests were still shown as turns. Auto-review now appears as its own category, and only successful requests count toward the turn graphs. Rate-limited requests were never charged, but they were being displayed incorrectly.
- Immediate relief: We reset usage limits while rolling out the fixes, then shipped hotfixes across the CLI, desktop app, and usage backend.
- What to expect: New usage data should be clearer and actual consumption should be lower. Historical charts may still show auto-review under GPT‑5.4 because older turn data was not relabeled. Features that intentionally perform more work; such as /goal, subagents, and higher reasoning levels will still naturally use more capacity.
All fixes are now deployed, and we've added more detailed monitoring so we can detect background-usage regressions sooner. We'll continue watching the results closely.
Thank you for building and doing all sorts of things with Codex.
Discovered the 2nd hand servers world and bought a server to use as homelab
I can’t believe it took me this long, having a homelab is AMAZING.
Feels so enabling!
Yesterday I told codex to write some stuff and use a decryption library i wrote by hand a while ago
The end result failed at decryption every now and then
Turns out it wrote its own implementation, I corrected it by using my library
It worked 100% of the time, what a feeling.
I wish everything in @OpenAI Codex was keybindindable, i want to move stuff around like a videogame.
also better voice control, i should be able to bail a voice transcription
Dear Codex team I'd love to have these:
- Transcription while dictating
- Custom dictation shortcut that works outside the app so i dont even have to focus the app
- A shortcut to focus the textarea (this one specially, like cmd+L on chrome)
@thsottiaux @ajambrosino 🫶
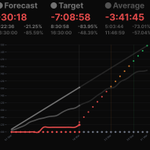
The best version of my Cumulative Line Graph so far.
It packs a lot of info!
This gives me a clear view of what I have to do to catch up with my project and reach my goals.

