




Whats next for Clude Memory Model?
Todays JEV announcement couldn't have come at a better time. We've been thinking about what's next for us.
Congrats to Diogo @CompleteSkeptic and @typesafeai on raising $870M at a $7.5B valuation!
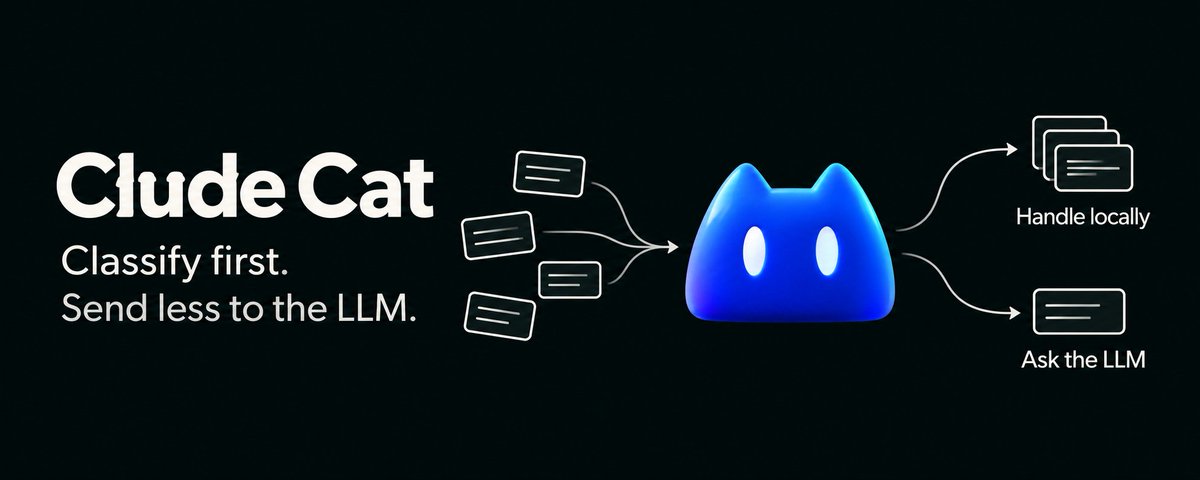
We've loved using JEV at Clude. It's helped us cut costs significantly and got us thinking about building further on our own Clude memory model to filter out the raw noise before passing data to JEV.
Through fine-tuning our own model we soon realized how expensive training a niche high performance model could be. But we also discovered just how good our own memory model was becoming at doing exactly what we needed to save on costs!
What started as a way to solve our own problem has turned into something we think is worth pursuing.
Back to building!
gm. actions speak louder than words.
back to building.
gm, ICYMI this is a video recap of what we have built and achieved with @cludeproject so far. We let our actions demonstrate our long term commitment:
+ invested +$100K to training our own SOTA memory model and now live exclusively on Tencent
+ bought back ~1000 SOL to date and relocked (17% of supply)
+ shipped our PMP as the first multi-chain Tokenized Memory infra live onchain
+ won various notable grants, partnerships and working with a few SG listed corporate clients
+ more to come with details in the video below:

We spent over $100K and trained on 49M examples across about 3M synthetic life scripts to build a 4B memory model that runs fully local and private.
Details here:
We spent over $100K (compute, dead ends, the lot) and trained on 49M examples across about 3M synthetic life scripts to get a 4B memory specialist that runs fully local. Extract, temporal, reconcile, abstain. LoRA on a 4B base, INT4 is a couple GB on disk, a few GB hot. Comfortable on a 16GB laptop. Phone packaging soon and what we're working on next.
This isn’t just “smarter chat.” I see it as a deployment bet:
memory as a software component on the machine that holds the data. No per-write API tax. Nothing leaves the device.
Frontier labs memory remembers you inside their product. Coding agents already get rich context. Your health notes, dose changes, shift logs, ambient scraps with other people’s names in them? That stuff either lives in a silo or nowhere. We want the model next to the notes you own, something that is really personalised.
Security context is the quiet part. CONTINUITY’s point is that agent stacks drop, widen, or reinterpret authorization as work crosses tools. Private memory only works if provenance survives the whole path: who wrote it, what it authorizes, what you’re allowed to do when two records disagree. Reconcile and abstain aren’t features, it's integrity and something we've pushed from a Private AI perspective.
Imagine;
1️⃣ Offline plant handover where two valve readings conflict and there is no outbound net. Surface both. Don’t silently keep the newer row.
2️⃣A clinician’s notes on a device that can’t phone home. Dose flipped twice, third source disagrees. Refuse the confident answer.
3️⃣Ambient capture on a laptop. Thousands of fragments a day. High write volume plus privacy is where local stops being a hobby and starts being the only sane architecture.
We also killed our own vanity number. Hit 100% on our bench. Four regexes hit 100% too on 2.7M training examples. We rebuilt so phrasing carries no label. Bench ships with an attack: bag-of-words above chance means we automatically reject it.
Model lands at 41.4%. Shortcuts around 25%.
Weights + gated bench going up on Hugging Face soon. Come try to break it.
At Clude, we believe your memories should belong to you. World's first fine-tuned memory model coming soon.
Congratulations to our friends at @AskVenice and @ErikVoorhees for leading the way on Private AI.
At Clude, we believe your memories should belong to you.
That is why we are building a super lightweight, personalized AI memory model that runs fully locally, stays private, and will be released on Hugging Face.
Details on the first phase of our fine-tuned memory model is in the article:
We’re here for the long term and will keep building.
We continue to back ourselves and doubled down:
We’re here for the long term and will keep building.
We have reinvested more of our own revenue into training Clude’s memory model. This is on top of the $35K of inference grants we have received from Google and Solana.
Now we’re fixing the remaining bugs, tightening the model, and preparing it for Hugging Face.
Fully offline. Fully local.
Built for memory from the model up.
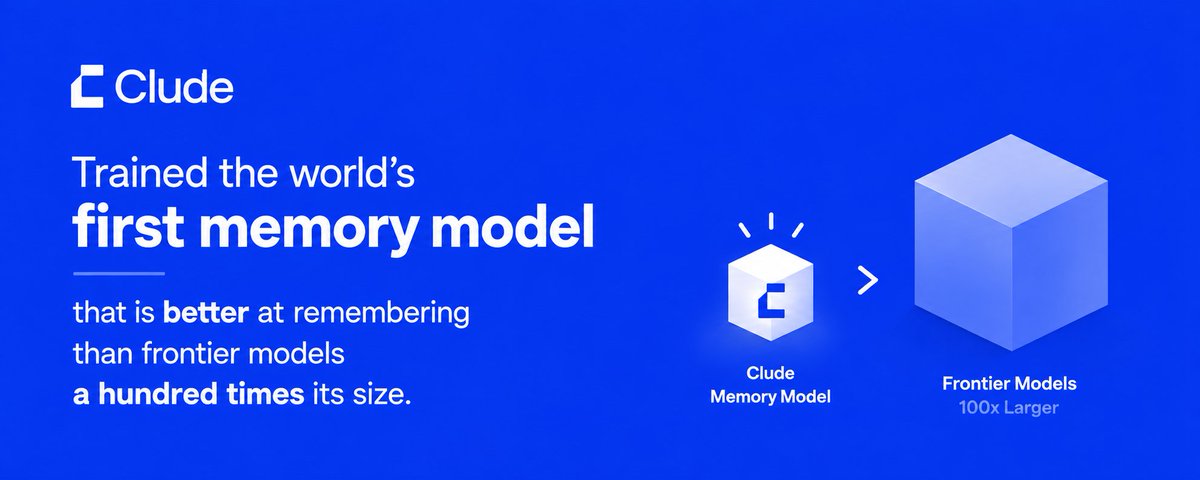
Clude Memory Model Update:
We’ve now trained our 4B specialist memory model on 4.9M examples across nine memory operations.
Clude Memory Model Update:
We’ve now trained our 4B specialist memory model on 4.9M examples across nine memory operations.
The results are encouraging.
Clude scores 89.7 across our MemOpsEval benchmark, ahead of Claude Sonnet at 88.9 and Gemini Flash at 85.0.
More importantly, it performs best where persistent memory tends to break; temporal reasoning and reconciling contradictory information.
We’ve also learned a few things along the way.
Performance largely saturated around 1.2M training examples. Splitting evaluation by synthetic life history, rather than individual examples, matters enormously.
The model now runs quantized locally, with no per-memory-operation API cost.
Next is per-user adapters and continuous refresh from confirmed memories and corrections.
We’ll publish a more detailed technical write-up update after.


CludeAI retweeted

🔐 Just locked 70,991,606 $Clude tokens with @Streamflow_Fi
It's on-chain. You can check the amount, time-period and recipients.
Check it out👇
app.streamflow.finance/contr…

This is what Clude is about:
1. The enterprise side builds the business, generating revenue and cash flow.
2. The crypto side lets us stress-test the technology in public while expanding distribution and proving the value of Tokenized Memory.
We intend to keep doing more of both.
Why did we build the @AnsemClone for the Black Bull community?
We actually did not build it simply as a viral marketing stunt. Although onboarding @blknoiz06 and putting our technology in front of a much larger audience was clearly part of the calculation.
We wanted the experiment to do two jobs at once:
1. Grow distribution through earned attention
2. Prove the technology in public, at scale
The main reason we built it was to show our Tokenized Memory stack operating at real scale, in real time.
The clone is built from 245K memories and growing.
This gives us a live demonstration of what a Company Brain could look like when it contains the history, relationships, contradictions and changing opinions of a real community.
A growing number of enterprise AI products are beginning to talk about the “Company Brain.”
Most are demonstrated using clean corporate datasets, controlled use cases and predictable environments. Those demos can be useful, but they rarely show how the technology behaves when the data is large, messy and alive.
Instead of testing our stack in a sandbox where the inputs had already been cleaned and the difficult variables removed, we pushed it into a live environment where the technology had to deal with the dataset as it actually existed.
Real companies are not clean, small datasets either.
They are fragmented conversations, undocumented decisions, changing relationships, conflicting information and years of accumulated context.
A Company Brain that only works inside a polished demo does not understand the company. And a small, curated dataset is not scale.
We wanted real size.
This is also how we intend to operate going forward.
Clude Labs is building an enterprise AI business that continues to grow steadily in the background. That work is commercially important. It is what produces revenue and cash flow. But it does not always make compelling content for a crypto audience trained on speed, novelty and constant dopamine.
Unfortunately most updates would read like LinkedIn slop. Much of my day consists of private meetings with clients under NDA. But we will have more to share on this soon.
Crypto gives us a different medium but it is also what gave birth to Clude Labs.
It gives us a public frontier for live R&D, where we can test the stack against difficult datasets and use cases with real users almost instantly. It also makes the value of Tokenized Memory visible at scale.
So the tldr of what Clude @cludeproject is:
1. The enterprise side builds the business, generating revenue and cash flow.
2. The crypto side lets us stress-test the technology in public while expanding distribution and proving the value of Tokenized Memory.
We intend to keep doing more of both.

First Community MMO AI Clone is now LIVE on X.
Say hello to the @AnsemClone of The Black Bull $ANSEM @blknoiz06 community
We have now shipped the @AnsemClone so just tag him and he will respond based on its +210K Black Bull Memory feed trained by the community in real time. Its basically like if @aixbt_agent became a Black Bull.
@blknoiz06 take a look and let us know what u think?
Also featuring @ansem @PumpfunEco @theunipcs with the top engagement solana:9cRCn9rGT8V2imeM2BaKs13yhMEais3ruM3rPvTGpump posts currently in the last 24hrs in our live posts tracker.
Ansemption:
@blknoiz06 @ansem @AnsemClone solana:9cRCn9rGT8V2imeM2BaKs13yhMEais3ruM3rPvTGpump

The first MMO AI with billions of tokenized memories feeding a live community hivemind being built in real time. Clude has joined the Black Bulls. @blknoiz06
🐂🧠
Watch the Black Bull grow a brain! 🐂🀄️🧠
The first memecoin Clone co-created by its community and made tangible.
Clude @cludeproject turns every solana:9cRCn9rGT8V2imeM2BaKs13yhMEais3ruM3rPvTGpump post into a tokenized memory on Solana, feeding the live network behind the Ansem Clone.
165K memories now shine as stars and growing in real time. Brightest = most liked.
Find yours: clude.io/ansem
@blknoiz06 is there a Black Bull Builders grant we can apply for to scale this into the first MMO AI with billions of tokenized memories feeding a live community hivemind?
Clone yourself
What is Clude Clone? It's a AI version of you that runs on your Mac.
It learns how you write, think, and decide from your own screen, meetings, and apps, then drafts replies and answers questions as you.
Runs locally. Your data stays on your device. You approve everything.
It remembers. Clude quietly captures what you see and do, meetings, connected apps, your desktop, into a private memory that lives entirely on your Mac. Nothing is uploaded.
It learns you. That memory gets distilled into a model of your voice, your relationships, and how you make decisions. It shows you what it's picked up, you confirm or correct it. It gets sharper every time.
It acts as you. Ask it to reply as me, or ask your clone a question directly. It responds in your voice, grounded in what you actually know, always behind your approval. Powered by Hermes
It stays yours. Local-first. Honestly labeled as an AI clone. Nothing leaves your device unless you opt in, and even then, only a distilled profile, never your raw data.
Not a generic chatbot. Your actual voice, learned from your actual work.
A total of $35K as the first step to fund our compute for training the world's first memory model has begun.
Step 3: Compute Credits go brrr... 🖨️🖨️🖨️
To recap, we have now received a total of $35K in grants to fund our memory model training. These grants are also equity-free and token-free as well.
$10K from @SolanaFndn through @SuperteamSG
$25K from @GoogleCloud_SG
Will share more details around the progress of this next week as the immediate outcomes already look quite promising. We are quite excited to build the world's first memory model!
Example of what training the model currently looks like below:
