

@clockworkio
Account based inUnited States
About this account
- Account based in
- United States
- Connected via
- Web
Account-level information from X, not a live location or the device used for a specific post.
https://xitter.cf/t.co/BXAeZpbDtP builds software that optimizes GPU clusters for fault tolerance, deterministic performance and increased utilization.
Palo Alto, California
Joined April 2021
- Tweets392
- Following112
- Followers98
- Likes244




Pinned Tweet
At scale, failures are routine. Losing the work has been routine too. Not anymore.
LinkedIn runs Clockwork.io in production. Together.ai is bringing TorchPass to its GPU cluster customers. SemiAnalysis measured the payback: goodput loss cut from 14% to under 3%.
Today we're launching an industry first, in preview: TorchPass Snapshots in addition to Asynchronous Application checkpoints. And announcing $31M in new funding.
🔹 TorchPass Snapshots: save a whole running training job, across every node, with no code changes. Free the GPUs now. Resume later. Nothing lost. Platform teams stop waiting for application owners to add checkpointing.
🔹 Async Application Checkpoints: checkpoint while you train, not instead of training. Save more often, lose less when something breaks, and get fresh weights to Reinforcement Learning rollouts sooner.
Our AI fault tolerance is already proven in production:
✅ LinkedIn runs Clockwork.io LinkPass across its AI infrastructure fleet.
"In aggregate, Clockwork.io prevents tens of thousands of GPU-hours of downtime per month across our fleet." Raghu Hiremagalur, SVP, CTO Infrastructure, LinkedIn.
✅ @togethercompute is bringing TorchPass to market as a service on its GPU Clusters.
"Our customers grade us on goodput, the share of their GPU-hours that actually move the model forward." Pavneet Singh Ahluwalia Ahluwalia, Product Lead, Together.ai
✅ WhiteFiber is expanding Clockwork.io across its global GPU footprint. "We bring clusters up faster, and a customer's first training run lands on a fabric validated end-to-end, not just powered on." Tom Sanfilippo, CTO, WhiteFiber.
Quantifiable payback: "In our ClusterMAX, TorchPass cuts training goodput loss from 14% to under 3% for a gold-rated neocloud." Dylan Patel, @SemiAnalysis_ , @dylan522p. More than 11 points of GPU capacity back, measured independently.
New funding: $31M with @PremjiInvest, @Wing_VC, Seligman Ventures, New Enterprise Associates (@NEA), @etisalatandae
Pressure tested at scale with some of the world’s largest enterprises, neoclouds and hyperscalers. The job never stops.
Stop paying for job restarts. Preview access opens today, and we'll kill a GPU and a link live at PyTorch Conference with Together.ai. Schedule a demo and preview access in the first comment 👇
#AIInfrastructure #FaultTolerance #DistributedTraining #GPU #PyTorch
𝐀𝐧𝐲𝐨𝐧𝐞 𝐫𝐮𝐧𝐧𝐢𝐧𝐠 𝐥𝐚𝐫𝐠𝐞 𝐭𝐫𝐚𝐢𝐧𝐢𝐧𝐠 𝐣𝐨𝐛𝐬 𝐤𝐧𝐨𝐰𝐬 𝐭𝐡𝐞 𝟐𝐚𝐦 𝐩𝐚𝐠𝐞: 𝐨𝐧𝐞 𝐥𝐢𝐧𝐤 𝐟𝐥𝐚𝐩, 𝐆𝐏𝐔 𝐟𝐚𝐮𝐥𝐭, 𝐨𝐫 𝐧𝐨𝐝𝐞 𝐟𝐚𝐢𝐥𝐮𝐫𝐞, 𝐚𝐧𝐝 𝐭𝐡𝐞 𝐞𝐧𝐭𝐢𝐫𝐞 𝐣𝐨𝐛 𝐢𝐬 𝐝𝐨𝐰𝐧.
One dead rank stalls every collective until the NCCL watchdog fires. Then checkpoint and restart: 45-90 minutes across every GPU in the job.
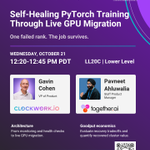
Next week at PyTorch Conference North America, Together AI’s Pavneet Ahluwalia and Clockwork’s Gavin Cohen walk through a training failover system built to keep the job running through all of it, and how to tell when live migration beats checkpoint-restart.
🗣️ 𝐓𝐨𝐠𝐞𝐭𝐡𝐞𝐫 𝐀𝐈 + 𝐂𝐥𝐨𝐜𝐤𝐰𝐨𝐫𝐤 𝐣𝐨𝐢𝐧𝐭 𝐬𝐞𝐬𝐬𝐢𝐨𝐧
Self-Healing PyTorch Training Through Live GPU Migration
Wed Oct 21 · 12:20 PM PDT · Room LL20CD
⏰ 𝐑𝐢𝐠𝐡𝐭 𝐚𝐟𝐭𝐞𝐫, 𝐰𝐚𝐭𝐜𝐡 𝐢𝐭 𝐡𝐚𝐩𝐩𝐞𝐧: 𝐍𝐞𝐯𝐞𝐫 𝐇𝐢𝐭 𝐙𝐞𝐫𝐨
Lin She, Clockwork.io
Wed Oct 21 · 12:45 PM PDT · Demo Theater, Community Expo
𝑆𝑒𝑒 𝑖𝑡 𝑖𝑛 𝑎𝑐𝑡𝑖𝑜𝑛 𝑎𝑠 𝑤𝑒 𝑝𝑢𝑙𝑙 𝑎 𝑛𝑒𝑡𝑤𝑜𝑟𝑘 𝑐𝑎𝑏𝑙𝑒 𝑎𝑛𝑑 𝑎 𝑝𝑜𝑤𝑒𝑟 𝑐𝑎𝑏𝑙𝑒 𝑓𝑟𝑜𝑚 𝑎 𝑟𝑢𝑛𝑛𝑖𝑛𝑔 𝑗𝑜𝑏, 𝑜𝑛 𝑐𝑎𝑚𝑒𝑟𝑎.
📍 𝐁𝐨𝐨𝐭𝐡 𝐏𝟖, 𝐂𝐨𝐦𝐦𝐮𝐧𝐢𝐭𝐲 𝐄𝐱𝐩𝐨. Bring your failure modes. Book a 1:1 or a private live TorchPass demo.
#PyTorchConference #DistributedTraining #FaultTolerance #GPUClusters #NCCL


➡️ Book time: na2.hubs.ly/H08qh5Z0
Read the press release on X: na2.hubs.ly/H08byd60
Schedule the unstoppable demo: clockwork.io/contact/
Last night we kicked off @CoreWeave 's Fully Connected 2026 — a reception with robots pouring drinks, games, and some of the sharpest full-stack AI infra engineers all in one room.
𝐃𝐚𝐲 𝟏 𝐤𝐢𝐜𝐤𝐬 𝐨𝐟𝐟 𝐭𝐨𝐝𝐚𝐲 𝐰𝐢𝐭𝐡 𝐢𝐧𝐬𝐩𝐢𝐫𝐞𝐝 𝐢𝐧𝐧𝐨𝐯𝐚𝐭𝐢𝐨𝐧𝐬 𝐢𝐧 𝐩𝐫𝐨𝐝𝐮𝐜𝐭𝐢𝐨𝐧 𝐚𝐜𝐫𝐨𝐬𝐬 𝐞𝐯𝐞𝐫𝐲 𝐢𝐧𝐝𝐮𝐬𝐭𝐫𝐲, and culminates with 𝐚 𝐫𝐞𝐚𝐥 𝐁𝐚𝐭𝐭𝐥𝐞 𝐨𝐟 𝐭𝐡𝐞 𝐁𝐨𝐭𝐬.
Catch us at the Clockwork booth in Pioneer Pavilion and see how we are built for production scale reliability, keeping AI runs alive through infra failures.
#FullyConnected #AIInfra #Battleofthebots #CoreweaveEvent
𝐀𝐈 𝐤𝐞𝐞𝐩𝐬 𝐦𝐨𝐯𝐢𝐧𝐠 — 𝐞𝐯𝐞𝐧 𝐰𝐡𝐞𝐧 𝐚 𝐆𝐏𝐔 𝐟𝐚𝐢𝐥𝐬 𝐨𝐫 𝐚 𝐥𝐢𝐧𝐤 𝐝𝐫𝐨𝐩𝐬.
At @CoreWeave's Fully Connected (Sept 29–Oct 1, San Francisco), we're showing what Workload-Aware Fault Tolerance actually looks like: FleetLens audits the fleet and pinpoints the fault. TorchPass and LinkPass keep distributed workloads running.
𝑊𝑒 𝑑𝑜𝑢𝑏𝑙𝑒-𝑑𝑎𝑟𝑒 𝑦𝑜𝑢 𝑡𝑜 𝑐𝑜𝑚𝑒 𝑠𝑒𝑒 𝑖𝑡 𝑖𝑛 𝑎𝑐𝑡𝑖𝑜𝑛.
🔗 Book time with the team: na2.hubs.ly/H080KZ30
#FullyConnected #AIInfrastructure #GPU #TorchPass #YOCO #LinkPass #workloadaware #faulttolerance #DARE
𝐖𝐞 𝐝𝐨𝐮𝐛𝐥𝐞-𝐝𝐚𝐫𝐞 𝐲𝐨𝐮: 𝐮𝐧𝐰𝐢𝐧𝐝 𝐚𝐧𝐝 𝐨𝐮𝐭-𝐜𝐨𝐦𝐩𝐮𝐭𝐞 𝐚𝐭 𝐭𝐡𝐞 𝐬𝐚𝐦𝐞 𝐭𝐢𝐦𝐞. 🍷 🧀
Join the Clockwork team at the Wine & Cheese Bar — good pours, good bites, and a live look at GPU fault tolerance that doesn't cost you speed. Bring your worst failure story; we'll show you the 1.8-hour recovery tax nobody budgets for — and how to erase it.
📅 Tuesday, Sept 29 · 5:00–7:00 PM · Pioneer Pavilion
𝐃𝐀𝐑𝐄 to have fun and learn. See you there.
@CoreWeave
#FullyConnected #AIInfrastructure #DARE

𝐃𝐞𝐭𝐞𝐜𝐭𝐢𝐨𝐧, 𝐫𝐞𝐦𝐞𝐝𝐢𝐚𝐭𝐢𝐨𝐧, 𝐜𝐡𝐞𝐜𝐤𝐩𝐨𝐢𝐧𝐭𝐢𝐧𝐠 — 𝐧𝐞𝐜𝐞𝐬𝐬𝐚𝐫𝐲, 𝐛𝐮𝐭 𝐧𝐨𝐭 𝐞𝐧𝐨𝐮𝐠𝐡 𝐟𝐨𝐫 𝐬𝐭𝐫𝐨𝐧𝐠 𝐠𝐨𝐨𝐝𝐩𝐮𝐭.
At AI Infra Summit, Clark Zinzow of @togethercompute laid out the four goodput pain points they see most:
• 𝐶ℎ𝑒𝑐𝑘𝑝𝑜𝑖𝑛𝑡 𝑟𝑒𝑠𝑡𝑜𝑟𝑒 + 𝑟𝑒𝑐𝑜𝑚𝑝𝑢𝑡𝑒 — even on high-performance scale-out storage systems, restoring can take minutes, while recomputing progress since the last checkpoint adds tens more.
• 𝐻𝑜𝑡-𝑠𝑝𝑎𝑟𝑒 𝑡𝑟𝑎𝑑𝑒𝑜𝑓𝑓𝑠 — always-on spares are expensive to hold idle; cold spares are too slow to pull into the cluster.
• 𝐶ℎ𝑒𝑐𝑘𝑝𝑜𝑖𝑛𝑡 𝑓𝑟𝑒𝑞𝑢𝑒𝑛𝑐𝑦 — checkpoint more often to lose less, and the overhead eats into your goodput.
• 𝐺𝑟𝑎𝑦 𝑓𝑎𝑖𝑙𝑢𝑟𝑒𝑠 — every health check passes, yet the job quietly slows or stalls.
How we close all four is in Part 4, linked in the comments.
#AIInfraSummit

We dare you: pull a link. Kill a GPU. Then watch the job keep running.
At @CoreWeave's Fully Connected AI Cloud conference, stop by the Clockwork booth and see how AI jobs survive planned and unplanned failures. LinkPass reroutes around the dead link, TorchPass live-migrates the work to a healthy GPU — no rollback, no recompute, no lost progress. SemiAnalysis clocked it: 405 minutes vs. 818 minutes for checkpoint-restart. 2× faster, zero lost steps.
📍Fully Connected 2026 · Sept 29–Oct 1 · San Francisco · Clockwork booth
Take the dare. We'll be ready.
#FullyConnected #AIInfrastructure #GPU

Checkpoint-and-restart isn't fault tolerance. It's a tax on goodput — pay to restore, then pay again to recompute.
At #AIInfraSummit with @togethercompute : move a live job off failing GPUs, no rollback. Benchmarked by SemiAnalysis, TorchPass recovers in 405 min vs 818 min (checkpoint restart).
Next clip in the thread.
Fault tolerance isn't a niche concern for a handful of frontier labs anymore. It's the conversation every team running AI workloads at scale is having.
𝐇𝐞𝐫𝐞'𝐬 𝐭𝐡𝐞 𝐧𝐮𝐚𝐧𝐜𝐞 𝐦𝐨𝐬𝐭 𝐭𝐞𝐚𝐦𝐬 𝐚𝐫𝐞 𝐬𝐭𝐢𝐥𝐥 𝐦𝐢𝐬𝐬𝐢𝐧𝐠: detection and checkpointing alone don't ensure strong goodput.
At AI Infra Summit, we showed what that looks like in practice: a network link and a GPU both fail mid-run on a synchronized workload, and the job keeps advancing instead of rolling back. No full restart, no lost work.
On the Data & Models stage, Clark Zinzow (@togethercompute) and Prashanth Thinakaran (Clockwork Systems, Inc.) took the same message further in their joint session, 𝐏𝐫𝐞𝐬𝐞𝐫𝐯𝐢𝐧𝐠 𝐏𝐫𝐨𝐠𝐫𝐞𝐬𝐬 𝐚𝐧𝐝 𝐆𝐨𝐨𝐝𝐩𝐮𝐭: 𝐖𝐨𝐫𝐤𝐥𝐨𝐚𝐝-𝐀𝐰𝐚𝐫𝐞 𝐅𝐚𝐮𝐥𝐭 𝐓𝐨𝐥𝐞𝐫𝐚𝐧𝐜𝐞 𝐟𝐨𝐫 𝐃𝐢𝐬𝐭𝐫𝐢𝐛𝐮𝐭𝐞𝐝 𝐓𝐫𝐚𝐢𝐧𝐢𝐧𝐠. Together AI on health checks and remediation, Clockwork on active job recovery through checkpoint-free live migration — a packed room hearing exactly why.
Reliability has become everyone's problem to solve. Health checks catch it. Live migration keeps it running.
See it for yourself - link in comments.
🎉 And congrats to our raffle winners, including Jason Wilder and Sunil Tagare — thanks for being part of the conversation this week.
#AIInfrastructure #FaultTolerance #GPUClusters #MLOps #Goodput #AIInfraSummit2026
🔗Interactive Demo: na2.hubs.ly/H07W06P0

𝐖𝐡𝐞𝐭𝐡𝐞𝐫 𝐲𝐨𝐮 𝐫𝐮𝐧 𝐢𝐧𝐟𝐫𝐚, 𝐛𝐮𝐢𝐥𝐝 𝐨𝐫 𝐭𝐫𝐚𝐢𝐧 𝐦𝐨𝐝𝐞𝐥𝐬, 𝐨𝐫 𝐦𝐚𝐧𝐚𝐠𝐞 𝐭𝐡𝐞 𝐩𝐥𝐚𝐭𝐟𝐨𝐫𝐦 — 𝐬𝐞𝐞 𝐟𝐨𝐫 𝐲𝐨𝐮𝐫𝐬𝐞𝐥𝐟 𝐰𝐡𝐚𝐭 𝐡𝐚𝐩𝐩𝐞𝐧𝐬 𝐰𝐡𝐞𝐧 𝐬𝐨𝐦𝐞𝐭𝐡𝐢𝐧𝐠 𝐚𝐜𝐭𝐮𝐚𝐥𝐥𝐲 𝐛𝐫𝐞𝐚𝐤𝐬.
Bring your hardest failure scenario to Booth #821 — where GPU downtime never gets the time of day.
Independently verified. Don't take our word for it.
📆 AI Infra Summit 2026 | Sept 15–17 | Santa Clara
Book a 1:1 demo → spots are limited.
#AIInfraSummit2026 #pulledlink #AIInfrastructure #AIworkloads #distributedtraining #GPUinfrastructure #GPU