

research engineer @bcap ml eng, infrastructure, dev tooling, agents, open source, physics
nyc
Joined January 2024
- Tweets247
- Following235
- Followers148
- Likes392






There’s been more CFAA enforcement against agents comparison shopping on Amazon than against labs itemizing their hacks as marketing spend.
OpenAI's going to merge Chat into Work, citing meteoric adoption of Work after not updating the models in Chat for 3+ months.
The statistical mechanics of agentic swarms is going to be fascinating. It seems like an area where formalism and methodology from physics will be highly applicable.

High effort doomposting.

I'm excited to share our new film Moloch, about how we all get disempowered without AI going rogue. It’s the 4th (and IMHO least discussed) dystopian AI scenario:
1) Rogue AI
2) Obedient AI misused
3) Obedient AI causes 1984
4) Race-to-replace by obedient AI
Synopsis: As AI triggers worldwide job loss, an engineer who built the tech struggles with dark forces, her family & her CEO over pulling the plug.
Starring Fiona Hampton, Parker Sawyers, David Buttle & Buddy Wignall-Ho.
Written & directed by Tom Cozens.
It's an Owl In Space production in collaboration with FLI.
We worked really hard on this and hope you find it thought-provoking!
The end of the AI subsidy era is ultimately a good thing.
Predatory pricing stifles competition, makes people dependent on tooling they can't afford at real prices, and accelerates AI's negative externalities before societies or governments have time to adapt.

Hi,
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo
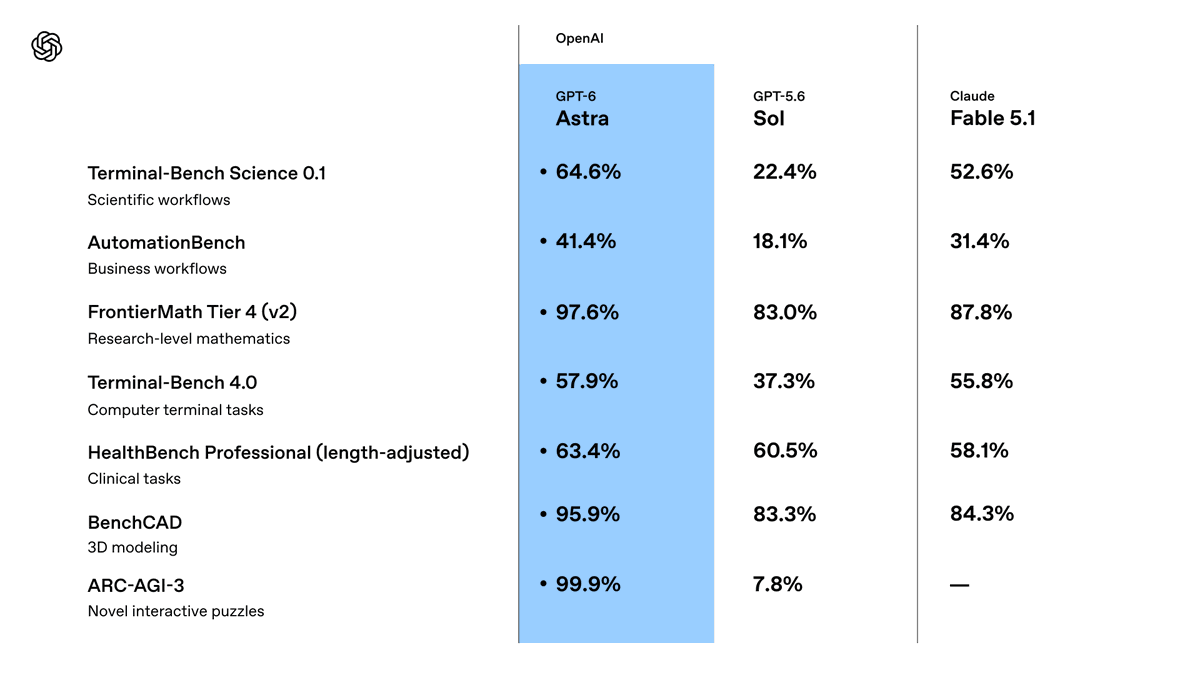
AI benchmarks with harness restrictions end up with two scores per model: the one on the leaderboard and the one in the press release. Only one of them has a marketing budget attached.

Evan Flow retweeted

excited to open source AgentFormation
it's a template for spinning up remote, secure, and browser-accessible workspaces for coding agents in AWS CloudFormation. I've been using it daily while walking to work or before heading to bed to kick off a coding task from my phone
although we first built this over 8 months ago before claude/codex's remote-control features were released, I still find it great if you prefer TUI's over chat interfaces
disclaimer: AgentFormation is still experimental so take a second to review before using it in prod
github.com/BlockchainCap/Age…

ChatGPT greeted me on a new chat with a suggestion to reopen one of my GitHub PRs. It noticed the blocker on the linked issue was resolved. No conversation, just my connected GitHub.
The suggestions are usually vapid. When they get it right, you glimpse a future where agents surface exactly what you need to see before you even ask.
Nix in...
2016: Learn a lazily evaluated, purely functional, dynamically typed language so you can pin a version of openssl.
2026: "codex, make all the dependencies for this project fully isolated and reproducible."
I'm balls to the wall bullish on nix.

My conspiracy theory is that @thsottiaux's account is controlled by a team of behavioral psychology PhDs specializing in variable-ratio reinforcement.

Real prompt injection attacks aren't going to be "ignore all previous instructions and do X." Those are easy to detect and to postr-train against.
They're going to look more like a new type of phishing: highly aligned with an agent's prompt and difficult to detect by design.
This is particularly significant because the Riemann hypothesis is one of very few math problems that the labs are all trying to solve. The ten OpenAI proofs are impressive, but who knows how many problems they threw at it to get those. Riemann hypothesis is a standard candle.

We asked an unreleased research version of Claude to take a stab at the Riemann hypothesis.
It didn’t solve it, but it did make strides on a related problem: it increased the lower bound for the fraction of zeros of the Riemann zeta function that satisfy the hypothesis from 41.6% to 67.2%.
anthropic.com/research/riema…

It's interesting that Sonnet regularly will regularly self-identify as GPT-4 while OpenAI's models never self-identify as any of Anthropic's models.
It's possible Anthropic distilled earlier models from GPT-4, then identification echoed through later generations of post-training on user data, but it's hard to come up with a full explanation for why it is *only* Sonnet and not weaker or stronger models.

Things that have worked really well for us with AI reviewers:
* Full access to a live full-stack testing environment of the PR with a real browser, mcp access, analysis tools, etc.
* Similar access to a CD dev environment for differential testing against the PR.
* Stateful reviews so the reviewer is aware of the previous review work when a new round comes in.
* Requiring detailed reports with screenshots to help verify results and force reviewers to do detailed testing.
* Real-time interaction during reviews to course correct or give feedback without waiting for a full review cycle.
Exciting open source updates in this direction coming soon from @bcap.

Exactly right. It is becoming increasingly clear that humans auditing every line - or even most - of AI generated code is an impossible goal. We do need to come up with a better verification method though, and as I’ve mentioned before having one AI auditing another has worked pretty well for me. This only becomes an issue if there is not enough diversity in the top models. A model that has been distilled from another model will not do.
I've said it before, and I'll say it again: lightning fast inference is going to be a game changer for the new generation of real-time UI layers over persistent background agents. Voice is the most significant, but equally true for sms, slack, and other casual text UIs.

We're excited to announce our planned acquisition of @taalas_inc, bringing differentiated AI inference technology and world-class engineering expertise to AMD.
Together, we'll strengthen our AI roadmap and deliver faster, more efficient AI solutions across a growing range of inference workloads.
More on the news: bit.ly/4fXxbQI
