
Adobe Research | PhD from OregonState | Computer Vision, 3D Reconstruction, Scene Understanding
San Jose, CA
Joined October 2009
- Tweets28
- Following117
- Followers153
- Likes92


Nice work!

Our AutoFocusFormer (CVPR 2023) provides a differentiable manner to learn to downsample to the most important tokens in an image. yet, the efficiency of the implementation has limited its gains mostly to FLOPS benefits rather than actual speed. My student David Smerkous will present AFFMAE in ECCV 2026 which explored visual pretraining with AutoFocusFormer. David made significant code optimizations for AutoFocusFormer that led to 5x inference speed at 1024x1024 resolution, 50% reduction in memory cost, as well as improved accuracy vs. a ViT encoder by learning to tokenize only to the important locations in an image!
Paper: arxiv.org/abs/2602.16249
Code: github.com/najafian-lab/affm…
If you are at ECCV: Friday Sep 11th, Poster Session 3: Poster # 74


Thank Zhenjun for advertising this work! Project page: arthurhero.github.io/project…

Softmax-GS: Generalized Gaussians Learning When to Blend or Bound
@chenziwee, @totoro97_, @HaoTan5, @zexiangxu, @fuxinli2
tl;dr: softmax-based color-merging mechanism for overlapping Gaussians with controllable competition strength
arxiv.org/abs/2604.27437


Amazing work! This can enable so many futurisitc applications!

Introducing Ego2Web from Google DeepMind and UNC Chapel Hill, accepted to #CVPR2026.
AI agents can browse the web. But can they act based on what you see? Existing benchmarks focus only on web interaction while ignoring the real world.
Ego2Web bridges egocentric video perception and web execution, enabling agents that can see through first-person video, understand real-world context, and take actions on the web grounded in the egocentric video.
This opens a path toward AI assistants that operate seamlessly across physical and digital environments. We hope Ego2Web serves as an important step for building more capable, perception-driven agents.
🧵👇
Introducing Long-LRM++ — for feed-forward, high-res, detail-preserving scene reconstruction
✨ Up to 64 960×540 inputs
🔍 Readable text
📉 4× fewer Gaussians
⚡ Real-time rendering
📷 End-to-end from unposed inputs w/ DA3 poses in 11s (w/⬆️ quality than DA3’s own GS predictor ;)
Dear co-authors: Hao(@HaoTan5), Peng, Zexiang (@zexiangxu), Fuxin(@fuxinli2)
Paper link: arxiv.org/pdf/2512.10267
Project page: arthurhero.github.io/project…
Code coming soon...
Will be presented in CVPR 2026 Findings!
Ziwen Chen retweeted

Do we really need massive curated 3D scene data for interactive world generation?
#SAM3D, #WorldGen say yes.
We say no.
I-Scene learns better spatial knowlesge using only 25K randomly composed instances.
🔑 Key insight:
We reprogram the instance generator to infer support, proximity, and symmetry from purely geometric cues for generating interactive scenes.
🧠 Scene-context attention
👁️ View-centric space
🧱 Random composition beats expensive curation
🌐 luling06.github.io/I-Scene-p…
💻 github.com/LuLing06/I-Scene-…
🧵 Details below [1/6]
Ziwen Chen retweeted

CSRankings counts publication in top conferences to rank professors/universities. But this encourages researchers to pursue quantity rather than quality.
We propose impactrank.org/, a new university ranking system that tries to measure quality instead of quantity of publications.
How can we measure the quality of the publications? We believe that 1) The quality of research is best understood and evaluated by peers in the same research area;
2) With careful and informed use, LLMs can reveal the implicit quality judgments that peers convey through their citation practices and writing across large volumes of scholarly work.
Hence, we developed the new ranking system where we analyze research papers from major AI conferences with LLMs.
For each paper, we ask an LLM what are the 5 most important papers to this paper. In other words, the five works that most strongly influence the study. By doing this, we trace which papers and authors are consistently seen as inspirational and foundational to new discoveries in the field.
We ran the model on all papers from top conferences in machine learning, computer vision, natural language processing and information retrieval from 2020 - 2025, and filtered references to only have those from 2000 onwards.
Next, we map these influential authors to their affiliated universities using the CSRankings name–affiliation database. Each time a paper is recognized as one of the “top five references” in another work, its authors and their institutions receive credit. To keep the scoring fair, points are divided by the number of co-authors, ensuring balanced recognition across collaborations.
The result is a new kind of academic ranking: one that rewards universities not just for publishing often, but for producing research that endures, inspires, and drives the field forward. This approach highlights scholarly influence and provides students, researchers, and institutions with a clearer picture of where the most impactful work is happening.
Note that we believe that CSRankings had substantially improved university rankings in computer science by replacing subjective, reputation-based measures, such as those in US News, with more objective indicators, but the LLM era allows us to do something potentially better!
Due to computational resource limits, we were only able to run it with a small 7B language model. It is also a project primarily led by undergraduate and master students from Oregon State University and University of California Santa Cruz. As a result, the system is very much a work in progress and will inevitably contain errors and blind spots. We actively welcome community feedback, new collaborators and contributions of GPU compute so that we can run larger LLMs, obtain more reliable results and improve the methodology.


Long-LRM will be presented tomorrow at #ICCV2025 Poster Session 1 (11:30 AM) as a Highlight Paper!
🚀The first generalizable GS–based approach for high-res, wide-coverage 3D reconstruction in 1 second.
Come check it out & chat with us!
🧩Code & weights: github.com/arthurhero/Long-L…
Amazing work from Ziqiao! The cleanest GS-based dynamic object reconstruction solution so far

Can we scale 4D pretraining to learn general space-time representations that reconstruct an object from a few views at any time to any view at any other time?
Introducing 4D-LRM: a Large Space-Time Reconstruction Model that ...
🔹 Predicts 4D Gaussian primitives directly from multi-view tokens (no motion vectors, no HexPlane);
🔹 Uses a clean, minimal Transformer backbone;
🔹 Generalizes with fast, high-quality feedforward rendering at any view and infinite frame rate.
Check out more interactive demos and scaling behaviors on our homepage/paper.
👉Website: 4dlrm.github.io/
👉Paper: arxiv.org/abs/2506.18890
Great work! Further boosted performance of Long-LRM😆

💥 Think more real data is needed for scene reconstruction? Think again!
Meet MegaSynth: scaling up feed-forward 3D scene reconstruction with synthesized scenes. In 3 days, it generates 700K scenes for training—70x larger than real data!
✨ The secret? Reconstruction is mostly non-semantic! No need to rely heavily on real or highly realistic synthetic data.
🌐 Project: hwjiang1510.github.io/MegaSy…
(1/4)
Ziwen Chen retweeted

Novel view synthesis has long been a core challenge in 3D vision. But how much 3D inductive bias is truly needed? —Surprisingly, very little!
Introducing "LVSM: A Large View Synthesis Model with Minimal 3D Inductive Bias"—a fully transformer-based approach that enables scalable, generalizable, and fully data-driven novel view synthesis, from sparse posed inputs. 🧵(1/6)
Project Page: haian-jin.github.io/projects…
Hate waiting 10 minutes for 3D GS to render your favorite indoor or outdoor scenes? ⏳ Our feed-forward solution, Long-LRM, cuts it down to just 1 second! ⚡️ With a straightforward mix of Mamba2 and transformer, it scales up to 32 high-res input images. arthurhero.github.io/project…
Many thanks to my mentor team @zexiangxu @HaoTan5 @KaiZhang9546 @Sai__Bi @fujun_luan @YicongHong at Adobe Research and my PhD advisor @fuxinli2 and the DL3DV dataset team @LuLing26466911 ❤️❤️ This project would not have been possible without their support!
167!
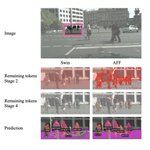
Want to find those super far away cars which are butchered by too much downsampling? Check out end-to-end adaptive downsampling! Even with 32x stride we kept enough information to segment small objects! Check us out this morning at poster 167! #CVPR2023 tinyurl.com/mr9pj62j


#CVPR2023 Want to zoom in and segment tiny tiny people in the background without doubling input resolution? Say goodbye to grid-like strided convolutions, and instead use hierarchical, adaptive downsampling from AutoFocusFormer (AFF)! github.com/apple/ml-autofocu…

Removal of a grid representation enables AFF to use finer-grained downsampling rates and to achieve significant improvements on small object recognition. Notably, AFF-Small backbone achieves 44.0 AP + 66.9 PQ on Cityscapes, on par with Swin-Large, but with 78% fewer params!

Collaborators from @Apple and @OregonState : Kaushik @kaushikpatnaik Shuangfei @zhaisf Alvin @lvinwan Ren @jrenzhile AlexS @alexschwing AlexC @AlexColburn_ Fuxin @fuxinli2 🙏 arxiv: arxiv.org/abs/2304.12406 Apple ML: machinelearning.apple.com/re…

