
https://xitter.cf/t.co/vlD2sAhx3c
localhost
Joined September 2023
- Tweets882
- Following19
- Followers960
- Likes1.9K

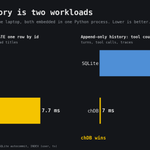





Field notes on ReplacingMergeTree from a real NSE price pipeline, with the trap reproduced in chDB: re-inserted keys stay duplicated until a merge, so any count or avg without FINAL is off. And it never retires a key you stop writing.
hikmahtechnologies.com/blog/…
The OneLake Iceberg bench now keeps a chDB lessons log. Two worth copying: size the filesystem cache to the disk, not the data (too big is ENOSPC mid-query, not eviction), and cap max_memory_usage so a heavy query fails cleanly, not the runner.
github.com/djouallah/lakehou…

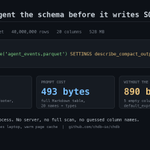
MCP tip: before an agent queries s3('.../*.parquet'), let it price the scan. Format One lists objects without reading them:
SELECT count(), formatReadableSize(sum(_size))
FROM s3('.../*.parquet', One)
Public hits bucket: 100 files, 13.73 GiB, 1.2s in chDB. Too big? Sample one.
chDB retweeted
80–200 TB a day, in a single partition 📈
Jump Trading's logs are its record of every order and trade, and it has run them on ClickHouse for 7+ years. Arnaud Adant on why they chose it, at Open House San Francisco 2026 👇
Try ClickHouse on your own data, free with $300 in ClickHouse Cloud credits → clickhou.se/4s2Nhyc
Loams is building a ClickHouse HTTP service on sandboxed chDB workers and measured the boot cost: 136.5 ms p50 from spawn to first SELECT 1, 1.1-1.4 ms for a second connection in a booted worker, and user/net/mount/pid namespaces add almost nothing.
github.com/ostrium-labs/loam…

chDB chdb-core nightly builds are out.
Daily wheels from main, which now syncs with ClickHouse master. macOS and Linux, x86_64 and arm64, Python 3.9+. Not for production.
pip install --pre --extra-index-url chdb-nightly.vercel.app/simp… chdb-core
github.com/chdb-io/chdb-core…
Agent memory tip: store embeddings as Array(BFloat16), not Array(Float32).
chDB, 1M memories, 384-d, exact cosine top-10:
Float32: 1.44 GiB, 156 ms
BFloat16: 739 MiB, 112 ms
Same top-10 in 19 of 20 random queries; the 20th swapped 1 of 10.
One type change in CREATE TABLE.
Summing token usage from Claude Code transcripts? Dedupe first.
One API response is logged once per content block, with the same message id and identical usage. On 1.9 GB of local JSONL: 76k usage lines, only 35k responses. A naive sum puts output tokens 2.7x too high.
An options analytics pipeline (Kafka, ClickHouse, Postgres, FastAPI) tests each ClickHouse migration and query in embedded chDB, on synthetic data with known true vols. Two settings match clickhouse-connect's output; a lock covers FastAPI's thread pool.
github.com/Suleyman040/optio…

Sonde watches AI agents via OpenTelemetry, ClickHouse and Grafana. Its SQL tests replay agent spans into embedded chDB exactly as the collector writes them, then run every view, dashboard panel, alert and documented query against it. No server needed.
github.com/OlivMartins/sonde

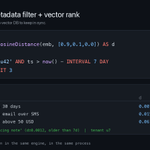
Filtered vector search can quietly return fewer rows than you asked for.
chDB, 500k agent memories, 384-d, HNSW index. Nearest 10 from the last 7 days (7.8% of rows):
default: 1 row, 5 ms
vector_search_filter_strategy='prefilter': 10 rows, 79 ms
HNSW picks 10, WHERE drops 9.
chDB retweeted
WalShadow, ClickHouse Managed Postgres on Google Cloud and the chdb Postgres extension all shipped the week of Open House NYC.
Sai Srirampur and Kaushik Iska's recap covers all three, plus the live demo: clickhou.se/4hLZzaI

A new database/sql driver for embedded chDB in Go gives each pooled connection its own chDB session, so one writer and several readers query in parallel in one process. No cgo, and a sibling HTTP driver runs the same code against a ClickHouse server.
github.com/tiny-obs/chdb-sql

An MCP data server doesn't need a connector per source. Two tools are enough:
describe(src): DESCRIBE file('t.parquet')
query(sql): chdb.query(sql, 'Markdown')
Swap file() for s3(), url(), postgresql(), iceberg(). DESCRIBE on a public S3 Parquet: 105 columns, under 3s cold.
nano, a Rust SIEM, lists embedded chDB as the query engine in its deployment docs. Hosted tenants each get their own chDB process over signed Parquet in R2. Self-hosted runs chDB lake query workers over Iceberg on RustFS.
nano.rs/docs/concepts/deploy…
@dansec_