

Building Glassray | PhD in AI
United Kingdom
Joined June 2010
- Tweets2.4K
- Following449
- Followers500
- Likes918





Chamath Palihawadana retweeted

Yesterday I heard first hand from @CompleteSkeptic his vision for Jev. This is everything I learnt:
1. LLMs keep repeating the same patterns in language because of mode dropping where they’re incentivised to always say the more rewarded set of phrases.
2. Most of agentic use is yet to come from computer to computer or agent to agent communication. Think about a website, most of what’s going on is machine to machine except the rendering of the UI which is machine to human. Same will happen with LLMs.
3. LLMs have been optimised for code generation and not automation / machine execution. We need different types of models for that.
4. Jev, OpenAI and Anthropic are all tied at ~0% progress of automatic the worlds meaningful tasks, and that’s pretty embarrassing but also just the start.
Fun fact: his company was named because it was the coolest .ai domain available and they needed one fast. Same happened for Glassray.

A production agent run that passes every output check and is still wrong. From the Super44 case study.

1
2
68
@glassrayai's check reads that gap: it compares the reply against the tool inputs and outputs in the trace. A forecast in the reply with no forecast in the tool output is a deviation.

1
1
14
No error, no failed eval, and a merchant planning the day around a forecast with no data behind it.
Case study: glassray.ai/customers/super4…

1
6
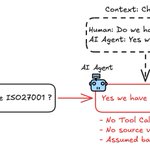
An AI answers a question about your company. The answer looks right.
But did it actually check?
Something similar came up earlier in the conversation, so it answers from that context and skips checking the company’s documents.

1
4
60
The answer might even be correct. But related information doesn’t verify a new claim.
Checking the final answer can miss that shortcut. You also need to check which documents the AI consulted and whether they support the answer.
1
30
At @glassrayai, we check the steps behind the answer to catch skipped lookups and claims based on the wrong documents.
Full write-up on how we approached this:
glassray.ai/blog/judge-the-t…

15
If you use an LLM to check your AI agent's answers, you probably don't know whether it's working. We didn't.
We wrote the correct answers by hand for 24 real traces, then scored our checker against them. It was missing two of three real failures.
2
3
65
We tested four models as the checker. gpt-4.1 gave the same 24 results in all three runs. gpt-5.4-mini went 0 catches, then 2, then 1 on identical inputs.
1
33
Full method and a checklist to run this yourself: glassray.ai/blog/cheap-model…

13
Chamath Palihawadana retweeted

Same 50 traces. Same digest. Same prompt.
Claude Sonnet 4.6: $3.45/1k
gpt-4o-mini: $0.11/1k
We're moving our highest-frequency LLM call to gpt-4o-mini, same search results.
But the cheapest, Gemini 2.5 Flash-Lite, broke.
Full writeup: glassray.ai/blog/cheap-model…

Really enjoyed being part of this. It was great to see so many people passionate about building the next generation of AI 🙌

Great event yesterday by @glassrayai, @vercel & @joinsequel
Finally an easy way to watch your traces and catch the moment your agent goes off track - before a customer does.
That's what we're building at @glassrayai. Proud of the team.

3
142
We put Claude on the night shift at @glassrayai.
It picks up tickets overnight, opens PRs, and responds to @greptile feedback until the PR is cleaner for human review.
The goal is not autonomous engineering. Just better focus for the hard problems.
linkedin.com/pulse/we-put-cl…

Chamath Palihawadana retweeted

PhD studentships for September 2022 at School of Computing, Robert Gordon University buff.ly/3NpfY2x


Call for papers: AI-CyberSec Workshop 2021.
On behalf of all the organizers, I am pleased to invite you to submit your contributions to the Artificial Intelligence and Cybersecurity Workshop (AI-CyberSec-2021)
sites.google.com/view/ai-cyb…
#artificialintelligence #cybersecurity #ai
