

decoding the universe find a new book to read at https://xitter.cf/t.co/yYUmV9IMxF
Joined November 2021
- Tweets671
- Following117
- Followers145
- Likes874





Pinned Tweet
Released Qwen3.8-27B-Escha-W2-Vision
A hybrid combining Escha W2 language weights (10.15 GB) with Qwen’s original vision tower (0.92 GB) - 11.07 GB total.
huggingface.co/centraly/Qwen…


So OpenAI is killing Terra, what a foreshadowing

Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
Openai really made a mistake by releasing astra in such way that it nukes our weekly usage with 1-2 days. Most people are forced to look around and give chance to alternatives because of this.
Is there anything more lame then announcing your model and showing the results and then saying, but only selected will have access to it for the now. Wish they would stop with this.
Centraly retweeted

MTP is now live for Escha Qwen3.8-27B W2!
Decode speed has been one of the bigger challenges with running a dense 27B model, and MTP was at the top of the most requested add-ons.
So we shipped it.
With MTP speculative decoding:
RTX 4090: 67.3 → 129.3 tok/s (1.92×)
RTX 5080 16GB: 61.7 → 109.2 tok/s (1.77×)
RTX 4080 16GB: 52.8 → 93.4 tok/s (1.77×)
Same Escha W2 model, using Qwen3.8’s pretrained MTP head. No separate draft model needed.
MTP is included with the model and supported in the latest Escha SGLang runtime. Turn it on with SPEC=1.
Model: huggingface.co/EschaLabs/Qwe…
Runtime update: huggingface.co/EschaLabs/esc…


Escha 2-bit Qwen3.8-27B is live!
The full model is 10.15GB on disk, runs at 82.6 tok/s on a single RTX 5090 with our custom SGLang runtime, and averages ~100% of FP8 performance across 8 benchmarks we've run so far.
We wanted to get this into people’s hands ASAP, and had limited time to run benchmarks. For the ones we did run, one surprising finding is LiveCodeBench v6:
Escha W2: 86.81
FP8: 85.16
This was the single benchmark that showed crack on the previous 2-bit Qwen3.6-35B MoE (62.6 vs. 67.0 FP8). Nice win as we continue to improve!
Model: huggingface.co/EschaLabs/Qwe…
Runtime: huggingface.co/EschaLabs/esc…
Apache-2.0 model and runtime.
We’re also planning to open-source the full runtime stack, with GGUF releases for both the 27B dense and 35B MoE models coming soon.
As always, please share your results. We want to see the bangers and the flops - both help us make the next one better.


Centraly retweeted
Escha 2-bit Qwen3.8-27B is live!
The full model is 10.15GB on disk, runs at 82.6 tok/s on a single RTX 5090 with our custom SGLang runtime, and averages ~100% of FP8 performance across 8 benchmarks we've run so far.
We wanted to get this into people’s hands ASAP, and had limited time to run benchmarks. For the ones we did run, one surprising finding is LiveCodeBench v6:
Escha W2: 86.81
FP8: 85.16
This was the single benchmark that showed crack on the previous 2-bit Qwen3.6-35B MoE (62.6 vs. 67.0 FP8). Nice win as we continue to improve!
Model: huggingface.co/EschaLabs/Qwe…
Runtime: huggingface.co/EschaLabs/esc…
Apache-2.0 model and runtime.
We’re also planning to open-source the full runtime stack, with GGUF releases for both the 27B dense and 35B MoE models coming soon.
As always, please share your results. We want to see the bangers and the flops - both help us make the next one better.
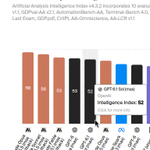
xitter.cf/centraly22/status/2085… Holy shit, it scored 52


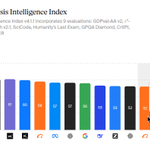
People are not ready for Qwen3.8 27B to score ~50 on AA. xitter.cf/ElainaNotes/status/208…

"Other Qwen3.8-series models to be released would *include Qwen3.8-27B"
"The *other model(s) in Qwen3.8-series would be released later on sperate page(s) as well"
This wording seems to imply that the Qwen3.8 series includes more than just the 2.4T and 27B models. Looking forward to seeing models at other parameter scales released too! 😻

