

Singapore
Joined November 2010
- Tweets1K
- Following765
- Followers3.7K
- Likes2.4K






Pinned Tweet
1/3 The physical world does not pause while a robot thinks.
In our new technical report, “Has GPT-6-Astra Achieved Embodied Intelligence?”, we study its capabilities across 12 benchmarks and 8 real-world robot configurations.
With access to training demonstrations through in-context learning and up to 10× the execution budget, GPT-6-Astra brings several benchmarks close to saturation, without updating its weights. Its ability to recognise failed actions and recover through further interaction is a meaningful advance.
But this also raises a question: what does success measure when an agent is given more time to correct itself?
🧵

Chen Change Loy retweeted

We developed PhysLDM, a high-quality neural simulator based on latent diffusion models (LDMs)!
Highlights:
- A spatiotemporal VAE that compresses dynamic 3D deformable meshes into a compact latent space.
- An LDM that models both global motion and local deformation.
- Fully differentiable, enabling challenging inverse problems!
We hope PhysLDM will make 3D simulation more accessible and ML-friendly!
Awesome work by Yu Zhang @yucrazing !
🌐 Project: yucrazing.github.io/physldm
📄 Paper: arxiv.org/abs/2610.07609

Chen Change Loy retweeted

1/5 Ropedia Super Week Day 1
How can robots learn to predict the physical world before acting in it?
Today, we're kicking off Ropedia Super Week with Ropedia W0, a world model exploring how human experience can help robots learn to predict what will happen next.
Here's what we're building.
This motivates benchmarks grounded in human needs, without in-domain demonstrations, and with a clock that keeps ticking.
Technical report: arxiv.org/abs/2610.22471
Project page: sensenova.ai/has-gpt-6-astra…
Code: github.com/OpenSenseNova/Sen…

Chen Change Loy retweeted
Ropedia Super Week | Oct 19–23
6 breakthroughs. 5 days. A showcase of how first-person human data can advance embodied AI, from spatial reasoning to action and control.
Here's the lineup. ↓
Mon: Ropedia W0, our latest robot world model.
Tue: HoliWorld + EgoXperience, our spatial data pipeline & full-stack data-to-model framework.
Wed: S-Agent 2.0, our evidence-driven spatial reasoning agent.
Thu: DONIC, our generalist controller for two dexterous hands.
Fri: Ropedia A0, our code-driven robot self-improvement framework.
Tomorrow, we'll take a closer look at our projects.
Follow Ropedia for a first look.

Chen Change Loy retweeted

DINOv2 has never seen a caption, and Qwen3 has never seen an image. We still aligned their embedding spaces without a single image-caption pair.
It even works when the images and the captions come from different datasets.
Project page: dominik-schnaus.github.io/un…
⬇️
Chen Change Loy retweeted

The surprising effectiveness of video diffusion models for hand motion reconstruction
Blog: huggingface.co/blog/Xingang-…

Chen Change Loy retweeted

Our ancestors picked up a rock. They saw a hammer, a blade, and a way to survive. Humans didn’t conquer the world with bare hands -- we did it with tools. 🛠️
Behind every tool we reach for is a tiny act of intelligence: "What do I need? What should I use? What do I do next?"
It's not just knowing what something IS. It’s imagining what it could DO. Can current AI models reason the same way?
Meet #EgoTools , collab with @ropedia_ai.
🔗 ropedia.github.io/egotools/
Chen Change Loy retweeted

🚀 Excited to share our new work: VLANeXt Family: A Systematic Study of VLA Models from Core Recipes to Emerging Paradigms! @KangLiao929 @ccloy
Starting from 500+ controlled experiments, we systematically revisit the design space of Vision-Language-Action (VLA) models and distill 12 practical recipes for building strong VLAs.
Beyond the original VLANeXt, we further ask: Do these recipes still hold as VLA paradigms evolve? We extend VLANeXt along four emerging directions:
• Model Scaling
• Latent Action Models (LAMs)
• JEPA-style Predictive Representation Learning
• World Action Models (WAMs)
Together, these variants form the VLANeXt Family, providing a unified framework for studying both current and emerging VLA paradigms.
👀 Page: dravenalg.github.io/projects…
📄 Paper: arxiv.org/abs/2602.18532v5
💻 Code: github.com/DravenALG/VLANeXt
Feedback and discussions are very welcome! 🤖
Ever wished you could change the focus and aperture after taking a photo?
Our work AnyBokeh, led by my student @itsmag11 Xinyu Hou, explores this with physics-guided bokeh editing from a single image, even one that already contains defocus blur!
The key idea is to use the existing blur as a cue to the image’s optical characteristics. This guides a generative editor to refocus the image and adjust depth of field, without first reconstructing an all-in-focus image.
Take a look at the examples: itsmag11.github.io/AnyBokeh/
Code available at: github.com/itsmag11/AnyBokeh

Most bokeh editors want a sharp photo first. We thought: 𝘄𝗵𝘆 𝗻𝗼𝘁 𝘂𝘀𝗲 𝘁𝗵𝗲 𝗼𝗽𝘁𝗶𝗰𝗮𝗹 𝗰𝗹𝘂𝗲𝘀 𝗮𝗹𝗿𝗲𝗮𝗱𝘆 𝗶𝗻 𝘁𝗵𝗲 𝗯𝗹𝘂𝗿? 🔍
Meet AnyBokeh! Edit bokeh directly in blurred photos. No all-in-focus detour. No test-time calibration. ✨
#NeurIPS2026
Chen Change Loy retweeted

Most bokeh editors want a sharp photo first. We thought: 𝘄𝗵𝘆 𝗻𝗼𝘁 𝘂𝘀𝗲 𝘁𝗵𝗲 𝗼𝗽𝘁𝗶𝗰𝗮𝗹 𝗰𝗹𝘂𝗲𝘀 𝗮𝗹𝗿𝗲𝗮𝗱𝘆 𝗶𝗻 𝘁𝗵𝗲 𝗯𝗹𝘂𝗿? 🔍
Meet AnyBokeh! Edit bokeh directly in blurred photos. No all-in-focus detour. No test-time calibration. ✨
#NeurIPS2026
Chen Change Loy retweeted

I created the Slop Index: a satirical citation index that calculates how much "slop" a researcher produces. It punishes having many papers with low citation counts.
You can calculate your own slop index at slop-index.com.

Code as policy, world, or editor: agents can write programs to control robots, represent worlds, and edit visual content.
My student Zunnan @zngmail2 has curated Awesome Code-as-X github.com/kkakkkka/awesome-…, connecting research across these areas through a shared idea: programs as executable, inspectable, and revisable representations. A useful reading list for those exploring this direction. Contributions welcome.
🤖 Made with AI

Chen Change Loy retweeted
Today, we’re pleased to announce the Ropedia Academic Partner Program, supporting researchers advancing Physical AI, robotics, and embodied intelligence.
Academic partners will gain access to HOMIE Gen2 to capture real-world multimodal data and explore new possibilities in robot learning and embodied AI.
We believe the future of Physical AI will be built together across academia and industry.
Join us today and let's build together: ropedia.com/collaboration

Chen Change Loy retweeted

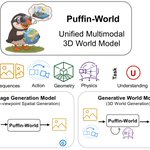
Introducing Puffin-World: Scaling a Unified Multimodal Model with Native 3D World States.
Puffin-World represents the physical world through three complementary native states: physics, geometry, and appearance. It unifies gravity-aware camera understanding, free-viewpoint simulation, 3D world generation and reconstruction, and closed-loop exploration within a single model.
The open release includes code, models, and Puffin-16M: 15M vision-language-camera triplets, 1M diverse camera trajectories, and camera-grounded annotations for approximately 44.5M images across 28 public datasets.
Explore Puffin-World: kangliao929.github.io/projec…
#PuffinWorld #EmbodiedAI #WorldModels #3DVision #SpatialAI #RobotLearning #OpenSourceAI #ACERobotics

Our Puffin-World technical paper is now available.
From one image or text prompt, it generates camera-controlled views with appearance, geometry and physical grounding, then reconstructs them into an explorable 3D world—all in one unified model.
Paper: arxiv.org/abs/2609.04196
Blog: huggingface.co/blog/KangLiao…
Dataset: kangliao929.github.io/projec…
Code: github.com/KangLiao929/Puffi…

Beyond plausible pixels: physically grounded 3D worlds.
Puffin-World is a unified multimodal model that jointly represents appearance, geometry, and physics to perceive, simulate, generate, and reconstruct 3D worlds. Its Omni-Camera representation enables physically grounded viewpoint control, while Puffin-16M scales training across diverse camera configurations and challenging trajectories.
Code, models and data are open.
Blog: huggingface.co/blog/KangLiao…

Chen Change Loy retweeted

🚀 ACE-Data-0 — a large-scale synchronized multimodal dataset🚀
👁️ Ego & multi-view exo videos
🧍 Human motion
✋ Hand motion
📦 Object motion
🎙️ Audio
🧤 Tactile sensing
They are all aligned on a unified timeline and a shared coordinated system
📖 Blog: ace-data-engine.github.io/AC…
📄 Tech report: arxiv.org/abs/2607.28625
🤗 Hugging Face: huggingface.co/datasets/ACER……