

Korpuslinguistik, Lexikographie und natürliche Sprachverarbeitung. Manchmal auch Datenjournalismus.
Jakarta
Joined April 2009
- Tweets16.2K
- Following1.1K
- Followers1.1K
- Likes8.3K


Mochamad Wahyu Hidayat retweeted

1312.

ALT 1312 merupakan tahun kabisat yang diawali hari Sabtu dalam kalender Julian, serta berdasarkan Masehi (M atau CE) dan Anno Domini (AD). Tahun 1312 masuk dalam milenium ke-2 dan abad ke-14. Angka romawi dari 1312 adalah MCCCXII.
Mochamad Wahyu Hidayat retweeted

📢 My blog post about fully open synthetic data generation pipelines with Llama3 is out!
Wanna learn how to build preference datasets from scratch using OSS models with the learnings from the @argilla_io team?
Check out the post, including code & data!
huggingface.co/blog/dvilasue…

Mochamad Wahyu Hidayat retweeted

Hahaha. If even his close capitalist bud rather invest this much in Switzerland, you'd think there's problems in investing in Indonesia. xitter.cf/cinnamongirlc/status/1…

Mochamad Wahyu Hidayat retweeted

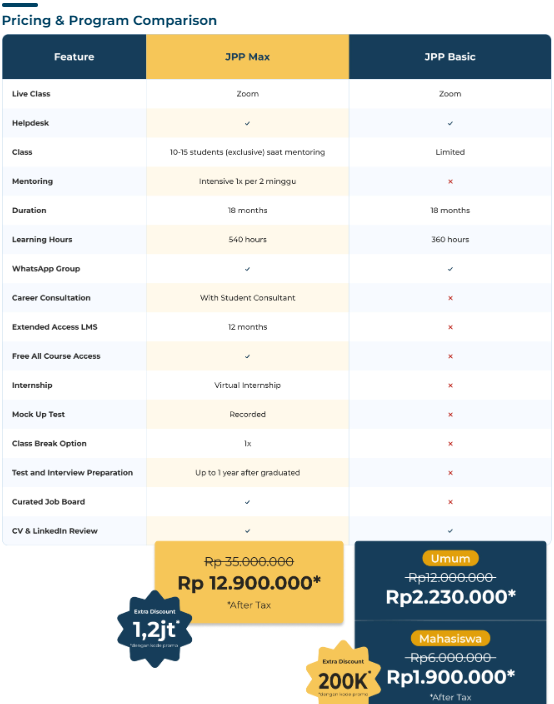
Apa persepsi kalian kalau denger istilah Airflow?
Possibly, mungkin kalian akan berpikir soal ventilasi, aerodinamika, dan hal-hal lainnya yang berkaitan dengan angin atau udara. Haha.
Just FYI, Airflow yang mau kami bahas sekarang ini di konteks Data Engineering.

Mochamad Wahyu Hidayat retweeted
If you go to chrome://settings/adPrivacy you can turn off the spyware that got inserted into the latest version of Chrome.
Mochamad Wahyu Hidayat retweeted
🦙🎈 @llama_index + Streamlit = A chatbot that understands YOUR data.
Learn how to augment #LLMs with custom data sources and build a smarter #chatbot in just 43 lines of code! 🤖
💬 Demo: buff.ly/3YPVes6
🧑💻 Start building: buff.ly/44p0p32

Mochamad Wahyu Hidayat retweeted
💼 Need help prepping for an interview?
Try @InterviewAI1—a Streamlit app by Haoxiang Jia and Todd Wang to get customized, targeted practice for every job posting: buff.ly/45lkJU8 💬
🤖 Learn how to build your own: buff.ly/45o3BwQ
#interview #ai #career

Mochamad Wahyu Hidayat retweeted

📢 We are giving away three copies of my book!
If you'd like a chance to win one, kindly Retweet this. All 'entries' by 15th August will be included in the draw whether in the UK or not.😊👍
Winners will be announced here and the book sent to you. 🥳📘
routledge.com/Insider-Guides…


Mochamad Wahyu Hidayat retweeted

50 Shades of Corpus Linguistics: Unveiling the Multifaceted Nature of Language Study
1. Corpus linguistics is a field of study that uses large, structured sets of texts, known as corpora, to analyze patterns of language use. (McEnery & Hardie, 2012)
2. Corpus linguistics is a methodological approach to linguistics that allows for the empirical examination of language as it is used in real-world contexts. (Biber, Conrad, & Reppen, 1998)
3. Corpus linguistics is a discipline that uses computational tools and software to analyze large amounts of text data, providing insights into language use that would be difficult to obtain through manual analysis. (Sinclair, 1991)
4. Corpus linguistics is a research paradigm that emphasizes the importance of context in understanding language, as it studies language as it is used in naturalistic, real-world situations. (Stubbs, 1996)
5. Corpus linguistics is a field that enables the study of language variation and change over time by comparing different corpora or different parts of the same corpus. (Baker, 2010)
6. Corpus linguistics is a branch of linguistics that provides empirical evidence for linguistic theories, as it allows researchers to test hypotheses against real-world language data. (Tognini-Bonelli, 2001)
7. Corpus linguistics is a discipline that has revolutionized the study of language teaching and learning, as it provides authentic examples of language use that can be used in the classroom. (O'Keeffe, McCarthy, & Carter, 2007)
8. Corpus linguistics is a field that has contributed to the development of lexicography, as corpora provide evidence of word usage, collocations, and semantic preferences. (Atkins & Rundell, 2008)
9. Corpus linguistics is a research approach that allows for the quantitative analysis of language, as it uses statistical methods to analyze patterns in large amounts of text data. (Biber, 1988)
10. Corpus linguistics is a discipline that complements traditional, introspective methods of linguistic analysis, as it provides objective, empirical data on language use. (Leech, 1992)
11. Corpus linguistics is a field that has contributed to the development of natural language processing and computational linguistics, as the algorithms used in these fields often rely on data from corpora. (Manning & Schütze, 1999)
12. Corpus linguistics is a discipline that allows for the study of language in its social context, as corpora often contain texts from a variety of social situations and registers. (Biber & Conrad, 2009)
13. Corpus linguistics is a field that has contributed to the study of discourse, as it allows for the analysis of patterns of language use in different types of discourse. (Baker, 2006)
14. Corpus linguistics is a research paradigm that emphasizes the importance of frequency in understanding language, as it allows researchers to identify frequent patterns of language use. (Ellis, 2002)
15. Corpus linguistics is a discipline that allows for the study of language across different modalities, as corpora can contain both written and spoken texts. (McCarthy & Carter, 2001)
16. Corpus linguistics is a field that has contributed to the development of translation studies, as parallel and multilingual corpora provide data on translation equivalents and strategies. (Zanettin, Bernardini, & Stewart, 2003)
17. Corpus linguistics is a research approach that allows for the study of language from a bottom-up perspective, as it starts with the data and builds theories based on the patterns observed in the data. (Tognini-Bonelli, 2001)
18. Corpus linguistics is a discipline that allows for the study of language from a top-down perspective, as it allows researchers to test hypotheses against the data. (Hunston, 2002)
19. Corpus linguistics is a field that has contributed to the study of pragmatics, as corpora provide data on how language is used to perform different speech acts and functions. (Carter & McCarthy, 2006)
Mochamad Wahyu Hidayat retweeted
Complete bullshit.
Pardon my french.

Nine humanoid robots gathered at the United Nations’ 'AI for Good' conference in Geneva for the world’s first human-robot press conference reut.rs/3PNvNor
Mochamad Wahyu Hidayat retweeted

Pro tip: if a machine learned model scores 100% on something, the metric is wrong, or the evaluation dataset is not robust, or the evaluation dataset is in the training data, or a combination of all of the above. At least in this point in time.
This quoted post is unavailable.
Mochamad Wahyu Hidayat retweeted

Hugging Face LLM Inference Container now supports Falcon 7B and Falcon 40B deployments on Amazon SageMaker🦅🚀 Falcon is the best performing open source LLM available today for commercial use under the Apache 2.0 license! 🤑
👉 philschmid.de/sagemaker-falc…
philschmid.de/sagemaker-falc…

Mochamad Wahyu Hidayat retweeted
MMS: Massively Multilingual Speech.
- Can do speech2text and text speech in 1100 languages.
- Can recognize 4000 spoken languages.
- Code and models available under the CC-BY-NC 4.0 license.
- half the word error rate of Whisper.
Code+Models: github.com/facebookresearch/…
Paper: scontent-lga3-2.xx.fbcdn.net…
Blog: ai.facebook.com/blog/multili…


Mochamad Wahyu Hidayat retweeted
Tired of cliché images of AI? This effort seems very cool.
betterimagesofai.org

Mochamad Wahyu Hidayat retweeted
1/ Thrilled to announce: Our new course ChatGPT Prompt Engineering for Developers, created together with @OpenAI, is available now for free! Access it here: deeplearning.ai/short-course…
Mochamad Wahyu Hidayat retweeted

Certainly, this paper deserves more attention.
arxiv.org/abs/2205.12628

