

Inference arena for open-source LLMs. Build the fastest correct server. Win real rewards.
Joined April 2026
- Tweets61
- Following15
- Followers705
- Likes304





Pinned Tweet
Cacheon is now open for submissions!
Check out our docs to get started mining today: cacheon.ai/docs

We're excited to be providing inference on the Liquid Inference exchange.
Token volume is picking up, so this presents a great opportunity to monetize our optimized catalog of models.
Prices are currently competitive but we expect to be out-competing and delivering on revenue.


More throughput. More ways to compete.
A 50% throughput gain on the same hardware, at equivalent quality, opens up new opportunities for teams building and serving AI:
→ Lower costs: offer more competitive prices, or make your own model cheaper to run and use
→ Compete on capacity: serve more demand before adding infrastructure.
→ Protect margins: stay viable as competitors reduce prices.
→ Make more workloads economical: bring previously expensive use cases within reach.
Whether your advantage is the model itself or how efficiently you serve it, better inference economics matter.
Why DeepSeek-V4.1-Flash for our next competition?
Because targeting a frontier open model keeps Cacheon at the leading edge.
Strong coding and agent performance. Native visual understanding. An architecture designed for efficiency.
How much faster can we run DeepSeek-V4.1-Flash on the same hardware?

A little summary of our performance progress so far on #SN14.
Speeds are measured using AIPerf which simulates multi-user concurrent workloads.
Can you do better? Submit your improved kernel and earn SN14-Alpha on Bittensor $TAO
Need a speed-boost? Reach out and we'll tailor to your needs.
🤖 Made with AI

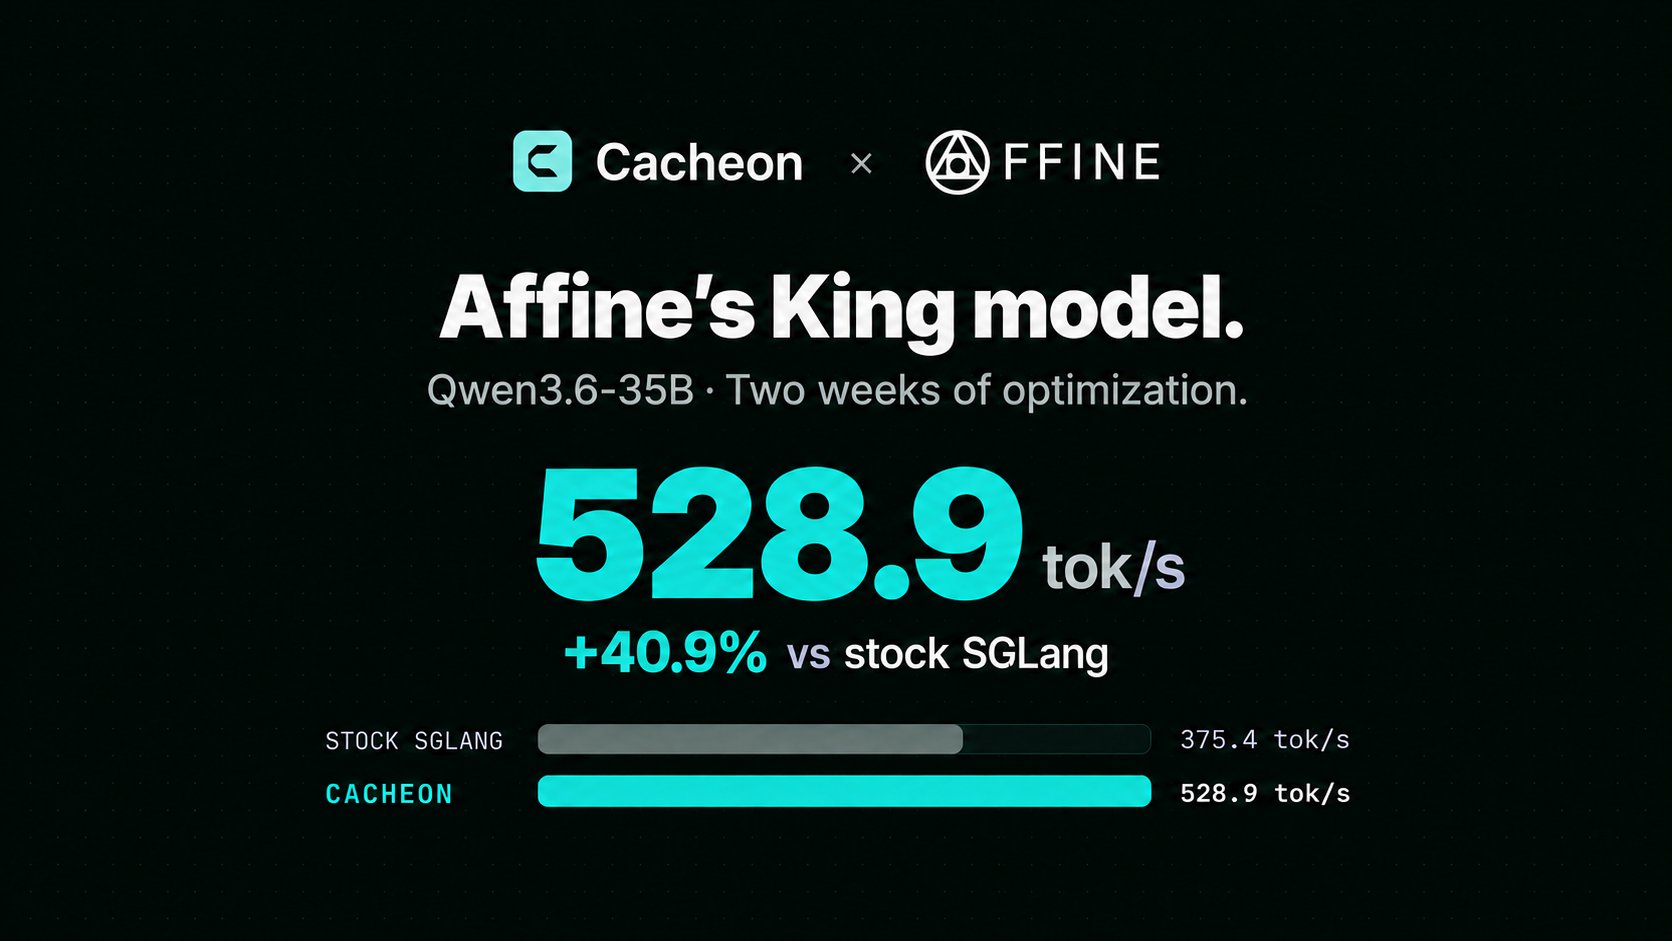
Affine's King model. Two weeks of optimization. 40.9% more throughput.
@affine_io became Cacheon’s first customer. These are the performance numbers behind that partnership.
We pushed Qwen3.6-35B to 528.9 tokens/s, up from 375.4 tokens/s on stock SGLang.
We’re building on this work as we bring Cacheon’s inference optimization to more customers and models.
$100k in revenue last month. @affine_io became our first customer.
We’re now working to monetize our Qwen and GLM-5.3 optimizations through licensing deals and our own inference service.
This quarter, we’re targeting more customers and expanding competitions to high-volume models - building a catalogue of kernels we can license or deploy ourselves.
There's more to come.
Keep calm and Cacheon.
Q3 is over. How are we doing against our roadmap?
The proof of concept is built:
✓ Multiple models optimized - MiniMax-M3., GLM-5.3 and Qwen3.6.
✓ Competitions run in parallel across models.
✓ Speed improvements evaluated end to end, with output-quality checks.
Different models suit different jobs. This progress opens a path to serving more workloads, with improvements judged on both speed and quality.
Q4’s focus: monetization and product–market fit.

AI inference is getting cheaper. But it’s consuming more and more of the AI compute stack.
McKinsey released a new report yesterday, estimating that by 2030, inference will account for ~60% of AI compute demand, versus ~40% for training.
That makes inference optimization increasingly consequential: every gain in throughput and utilization changes how much useful AI the same hardware can serve.
McKinsey’s full report ↓
mckinsey.com/industries/semi…

Great to see the work we’ve been doing with @affine_io get a moment on stage at @exploitsummit.
Here’s @const_reborn telling the story in his opening keynote ↓
GLM-5.3 hits a new milestone on Cacheon: ~12.5% above its earlier benchmark, measured under different test conditions.
On SN14 in $TAO Bittensor, miners optimize GPU operations to accelerate inference. We test changes with the full model running, and accepted work can support further improvements.
Our latest competition submission reached 1,242.8 tokens per second. We're contributing to raise the bar and challenge other miners to push GLM-5.3 further. Our team follows the same evaluation, submission-order and acceptance rules as every other miner. We'll continue contributing as long as our involvement helps advance the subnet. Any emissions we earn will fund development and operations.
In parallel, we're working to turn these advances into commercial opportunities, including collaborations with other subnets. We'll share more soon!

In our last competition, Cacheon miners pushed MiniMax M3 throughput to 2,337.9 tok/s: +32.2% vs the SGLang baseline.
What might that kind of performance improvement be worth commercially?
+32.2% throughput = ~61% more profit.
How? SemiAnalysis InferenceX™ models a B300 running MiniMax M3 on vLLM at $4.81 profit per chip-hour. Apply the same +32.2% throughput gain, with pricing and chip costs held constant, and modeled profit rises to $7.73 per chip-hour.
Why the difference? The GPU still costs $4.25 for the hour. More throughput means more capacity to sell without buying another chip-hour.
That's a scenario, not measured Cacheon profit. What is measured is the optimization: 2,337.9 tok/s, +32.2%, produced by Bittensor miners and passed through Cacheon's testing and reproduction.
Check the baseline. Run your own numbers.

Happy Labour Day!
We've been hard at work over the weekend.
Announcing our GLM-5.3 arena!
Miners can now submit kernel optimizations and get rewarded by the protocol.
GLM-5.3 presents a huge opportunity for production-use and monetization of the subnet.
More info: cacheon.ai
Another great result coming out of this competition's arena.
We've hit 2,274 tok/s on our MiniMax-M3 baseline
We're hard at work on integrating the next top model for our arena.
Cacheon focuses on production-ready models for real enterprise use-cases with evaluations only via end-to-end testing
We're excited for the submissions we'll get on our next arena. More to come.

ALT 2274 tokens per second or 28.6% improvement over SGLand on MiniMax-M3
