Research Scientist @google, building efficient multi-{lingual,modal,task} information retrieval models for search | PhD from @penn | BA from @columbia

New York
Joined May 2020
Given a request, AI systems generate long-form reports. Report evaluation relies on nuggets: essential & granular facts. Prior work on nugget generation treats them as short statements. Our #ICTIR2026 oral proposes DoGMaTiQ, an automated pipeline for Q&A nuggets. 1/6🧵
1
4
9
864
DoGMaTIQ scores for reports also best correlate with manual human scores, at system-level and at topic-level. More experiments are in our paper: circularity of LLMs for report generation + evaluation, as well as robustness to underperforming systems. 5/6🧵
1
30
In a world of geopolitical conflicts, how can AI help us navigate? Our #ACL2025-F work studies RAG robustness across 49 languages. TL;DR: 📈 boost robustness w/ multilingual RAG, 🤔 take care w/ low-resource citations 📜arxiv.org/abs/2410.01171 🤗huggingface.co/datasets/bord… 1/4 🧵
2
3
1
12
1,158
We study cross-lingual robustness over 4 LLMs and 2 IR models. We find A) multilingual RAG performs best; B) LLM’s citations varies widely across langs. Our further experiments investigate aspects of cross-lingual RAG from IR to LLM explanations. 3/4 🧵
1
118
This is the final paper of my PhD! Thanks to my many @upennnlp collaborators: @samarhdr, Chris, and the 7 wonderful students who I was fortunate to mentor. Please look out for our poster at ACL 2025 in Vienna. 4/4 🧵
3
122
🚀 How well can LLMs know you and personalize your response? Turns out, not so much! Introducing the PersonaMem Benchmark -- 👩🏻‍💻Evaluate LLM's ability to understand evolving persona from 180+ multi-session user-chatbot conversation history 🎯Latest models (GPT-4.1, GPT-4.5, o4-mini, Llama-4, Gemini 2.0, Deepseek-R1, Claude-3.7) all struggle in personalization! 🎨7 personalization skills tested in 15 scenarios 🌟Realistic long-context evaluation up to 1M tokens 👇 Check out what we discovered… (1/6)
2
12
4
33
4,827
Externally retrieving knowledge empowers LLMs for domain-adapted MT ⚖️🩺. But how is knowledge best represented, and how viable is generating it from an LLM itself? Our @GoogleAI paper investigates these questions through a careful experimental setup 📜. arxiv.org/abs/2503.05010
1
3
6
458
TL;DR - translation pairs > bilingual terminologies, generation especially boosts translations for small LLMs Our ablations highlight the need for more challenging domain-adapted MT datasets with modern LLMs. Thanks to collaborators Jiaming, @ebriakou & @ColinCherry!
88
We share Code-Guided Synthetic Data Generation: using LLM-generated code to create multimodal datasets for text-rich images, such as charts📊, documents📄, etc., to enhance Vision-Language Models. Website: yueyang1996.github.io/cosyn/ Dataset: huggingface.co/datasets/alle… Paper: arxiv.org/pdf/2502.14846 Code: github.com/allenai/pixmo-doc…
6
46
4
190
23,207
🚨 LLMs must grasp implied language to reason about emotions, social cues, etc. Our @GoogleDeepMind paper presents the Implied NLI dataset. Targeting social norms 🌎 and conversational dynamics 💬, we enhance LLM understanding of real-world implication! arxiv.org/abs/2501.07719
1
16
1
53
6,277
RAG enables LLMs to access external info 📖. But when this info is multiple languages 🌐, can LLMs reconcile differing viewpoints 🧐? We introduce BordIRlines, a dataset to study the robustness of cross-lingual RAG. 📃arxiv.org/abs/2410.01171 🗃️ huggingface.co/datasets/bord… 1/4 🧵
1
3
8
803
Using cross-lingually aligned queries, we analyze responses in a RAG setting. Responses can be "flipped" by varying passages' linguistic composition. We thus find these systems to be far from cross-lingually robust, as certain viewpoints can be amplified over others. 3/4 🧵
1
142
We'll be presenting this at the NLP for Wikipedia workshop @emnlpmeeting. This is ongoing work, and we'd love to hear feedback from the community! A shout-out to my collaborators Fiona and Adwait for their amazing first paper efforts, @samarhdr, and Chris. 4/4 🧵
126
Do LLMs' reasoning abilities come from training on code🤔? Many think so, but how does this hold across languages🌐? We study the interplay of code and reasoning in our recent work (#acl2024). 📃arxiv.org/abs/2403.02567 🗃️github.com/amazon-science/xs… 1/6 🧵
4
28
2
155
16,760
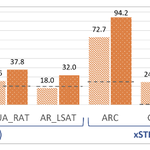
Results on BLOOM(Z) show that both techniques in tandem supercharge LLMs' complex reasoning across languages. Also, results on GPT-3 show that our code prompt format alone works well for API-based LLMs. 5/6 🧵
1
5
271
Check out our paper for more details and results, and we invite you to download and work with our xSTREET dataset! A huge thanks to my @AmazonScience collaborators: Tamer, @dbonadim, @nik0spapp, & Saab ~ 6/6 🧵
5
542