Creator of the MXFP4 vLLM build for Radeon AI PRO R9700. Fastest 4-bit LLM inference I've measured on RDNA4. https://xitter.cf/t.co/DKdA7a9iWk

Joined July 2009
Just saw Anthropic was possibly taking on another 60B in debt, so figured I would have Qwen Flash Next make a motion video on the current state of their debt and it's a good test of my engine I am working on also. The interest rate is double digits which doesn't signal a lot of confidence in these companies considering their valuations. #Anthropic #LocalAI #AIBubble
3
144
Nothing says "happily ever after" like 4 R9700 GPUs. I love the enthusiasm, but starting a marriage with a 5900 was a bold (and bad) choice. 💸 #AMDAI #R9700 @AIatAMD
1
6
405
Sure hope I am on the nice list this year. #R9700 #LocalAI #LocalLLM #launch80 #AMDAI
10
479
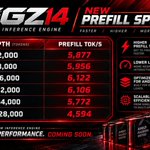
I have been working on a new inference engine that is solely focused on AMD hardware. As patching vLLM was never a long term solution. This is still a work in progress and realistically weeks away from release still. Here are the prefill results from BetterBench on my dual R9700's for Unsloth's Qwen3.8 27b nvfp4 . #AMDAI @AIatAMD #R9700 #LocalLLM #LocalAI
21
12
113
5,126
This is just 1 reason why local AI is 100% worth it. You can't put a price on having full control over your models in my opinion. #LocalAI #LocalLLM #OpenAI
7
298
I am seeing all these Opus 5.5 generated videos but Qwen3.8 27b can do the same thing locally on my R9700's. #AMDAI @AIatAMD #AMD #R9700 #LocalAI #LocalLLM #Qwen
27
8
2
150
10,584
OpenAI is reportedly planning a new $500 a month max plan and more than likely this is going to cause another shift in the allowed usage under current plans. My investment into local AI keeps looking better and better. Now is a great time to grab some R9700's! The price/value can't be matched on these IMO. #AMDAI @AIatAMD #LocalAI #LocalLLM
1
6
579
Comparison of Qwen3.8 27b vs ThinkingCap and Swift finetunes. I am going to test out ThinkingCap NVFP4 on my R9700's. So far I have been sticking to Unsloth NVFP4 though. #AMDAI #AMD #R9700 #LocalLLM #LocalAI
1
1
22
2,776
Can’t wait to get Qwen4 27B running on my R9700’s!! 3.8 has been absolutely amazing. #AMD #R9700 #Localllm #LocalAI #Qwen4
8
4
32
2,141
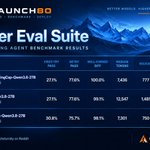
This is a great tool for being able to compare your LLM performance to other users. It came about in the Launch80 community as it was difficult to compare results with others and we needed a reliable way to do this. Now this is even more valuable as the content type and speed from drafters like DFlash2 can vary greatly based on that. After every run you will get a JSON and HTML file with the report. github.com/GGZ14/BetterBench #localLLM #LocalAI #BetterBench
2
2
10
676
First time crossing over 6,000 tok/s prefill on my dual R9700's on Qwen3.8 27b NVFP4. I still remember reaching 3,000, 4,000 and then over 5,000 on these dense models. Everytime I keep thinking it's at the peak, but they keep getting faster. @AIatAMD @RadeonPRO #AMD #R9700 #localLLM #localAI
13
7
6
94
8,828
Single AMD R9700 owners kept commenting on my posts. I am excited to share the new release with optimizations for 1xr9700. Decode speeds up 2x @ 153 tok/s. Prefill up to 3600 tok/s and concurrency @ 8 requests reaching 471 tok/s! It's amazing how much performance was left on the table for 1xr9700 and this is faster than 2xr9700 was even getting a month ago. github.com/GGZ14/vllm-mxfp4 #AMDAI @AIatAMD #AMD #R9700 #vLLM #localAI #localLLM #launch80
11
10
2
88
5,837
Until now, Radiance and ggz14 mxfp4 builds have lacked optimizations for single AMD R9700 owners. Tomorrow, that changes. Early numbers are showing a massive uplift in both decode and prefill performance. #AMDAI @AIatAMD #R9700 #MXFP4 #NVFP4 #vLLM #localAI #localLLM
15
712
Slowly unlocking maximum performance on my AMD R9700's. This was measured on Unsloth's NVFP4 of Qwen3.8 27b. NVFP4 -> MXFP4 at loading time now on github.com/GGZ14/vllm-mxfp4 #AMDAI @AIatAMD #LocalAI #NVFP4 #MXFP4
1
1
11
512
NVFP4 Qwen3.8 27b - AMD R9700's running @ 5,809 tok/s Prefill and 276 tok/s decode. This leverages the MXFP4 fast path I built on vLLM Radiance. github.com/GGZ14/vllm-mxfp4 #AMDAI @AIatAMD #localLLM #amd
9
13
4
70
5,101
This works via a online conversion during model load time. It adds maybe 30-45 seconds to model loading
1
410
New functionality coming today to our vLLM MXFP4 build. #AMDAI @AIatAMD #R9700 #LocalAI
1
1
7
253
6 months of chasing peak performance on 2x Radeon AI PRO R9700 GPUs has paid off: a custom MXFP4 build hitting 280 tokens/sec. Every experiment, all the details: codeberg.org/ggz14/radiance-… #AMDAI #AMD @AIatAMD #localAI
1
5
176
Qwen3.8 27b int5 on vLLM. Pelican riding a bike prompt #localllm #vLLM #mxfp4 #amd #r9700
1
1
5
339