
Previously core team member of AlphaFold2, AlphaTensor, and FunSearch at Google DeepMind. Now starting something new
London
Joined July 2009
- Tweets1.2K
- Following464
- Followers836
- Likes908





Bernardino Romera-Paredes retweeted

Exciting times for @hivergeai and the UK's AI startup ecosystem!

Cheers to the UK’s AI builders. 🇬🇧
Tonight in London, @JensenHuang announced new investments in @boltz_bio, @ForesightWorks, @hivergeai, @PrimaMente, and Riverlane.
From new medicines to quantum computing, there’s plenty to build.

Bernardino Romera-Paredes retweeted

Cheers to the UK’s AI builders. 🇬🇧
Tonight in London, @JensenHuang announced new investments in @boltz_bio, @ForesightWorks, @hivergeai, @PrimaMente, and Riverlane.
From new medicines to quantum computing, there’s plenty to build.
🤖 Made with AI
Bernardino Romera-Paredes retweeted

I get the feeling we'll be discovering many more unruly truths... perhaps, in due time, with a bird's eye view of these new territories we will start to understand and appreciate a higher order harmony

A week of essays on AI and the future of maths (Tao, Buzzard, Gowers, Christian), and I keep thinking of a one-page Ted Chiang story in Nature from 2000.
Superhuman minds make the discoveries. Humans are left with hermeneutics: interpreting them


Reading all those recent beautiful essays by Terry Tao, Kevin Buzzard and @wtgowers, I could not resist, but write up my deeply personal perspective on how I perceive and see things:
docs.google.com/document/d/e…
"Catching Crumbs from the Table", Ted Chiang, Nature 405, 517 (2000): nature.com/articles/35014679

Agentes de IA han resuelto el problema de Navier-Stokes, uno de los problemas más importantes de las matemáticas. Y ha sido gracias a los avances de Diego Córdoba y Luis Martínez-Zoroa. Ni una noticia en @elpais @elmundoes y demás. A ver si al menos @LaRevuelta_TVE los invita

Ayer fui un poco impaciente con la prensa. Hoy ya están en las noticias
- elmundo.es/papel/lideres/202…
- elpais.com/ciencia/2026-09-1…

Bernardino Romera-Paredes retweeted

Thankfully the 🇪🇺 AI act prevents Anthropic behavior with regards to sabotage, concentration of power, etc.
Wait no 🤦♂️
Bernardino Romera-Paredes retweeted

We’re excited to announce our collaboration with @NVIDIA, @Quantinuum and @AWS. Read more in our latest blog post: hiverge.ai/blog/quantinuum-n…

Bernardino Romera-Paredes retweeted

What if every quantum researcher had an army of students to help write quantum algorithms? LLMs are starting to serve as such a resource. We’ve partnered with @HivergeAI to use AI for quantum algorithm discovery, exploring practical quantum chemistry. quantinuum.com/blog/automate…

Bernardino Romera-Paredes retweeted

Really happy to share our new paper on using AlphaEvolve for mathematical exploration at scale, written with Javier Gómez-Serrano, Terence Tao, and @GoogleDeepMind's Bogdan Georgiev. We tested it on 67 problems and documented all our successes and failures. 🧵

Underpromise, overdeliver

- TTA: Skip for easy examples
- Thermal throttling: Sleep for 8s between runs (only affects average not record time)
Note: The authors reported a time of 2.02 seconds. My reproduction (torch 2.7.0; hardware seen below) had a min time of 1.99s.
Code: github.com/hiverge/cifar10-s…
3/3

Bernardino Romera-Paredes retweeted
We challenged our intern @ramadan_al76760 (zero prior AI experience) to beat the CIFAR-10 training speed record using @hivergeai's algorithmic discovery engine.
Result: Sub-2-second (!!) training for the first time ever.
New CIFAR-10 training speed record: 94% in 1.99 seconds on one A100
Previous record: 2.59 seconds (Nov. 10th 2024)
New record-holder: Algorithmic discovery engine developed by @hivergeai
Changelog:
- Muon: Vectorize NS iter and reduce frequency of 'normalize weights' step
1/3

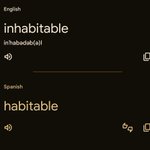
Falsest friend conjecture:
"Inhabitable" is the only word (or else the longest one) such that:
- it has the exact same spelling in two different languages (English & Spanish)
- it means the exact opposite thing in each


We took on the challenge and we’ve put our system to work on the nanoGPT benchmark. @hivergeai tech discovered new algorithmic improvements beyond the existing optimizations.
Check out the results in the PR github.com/KellerJordan/modd… and read our blogpost hiverge.ai/blog/introducing-…!


Love this project: nanoGPT -> recursive self-improvement benchmark. Good old nanoGPT keeps on giving and surprising :)
- First I wrote it as a small little repo to teach people the basics of training GPTs.
- Then it became a target and baseline for my port to direct C/CUDA re-implementation in llm.c.
- Then that was modded (by @kellerjordan0 et al.) into a (small-scale) LLM research harness. People iteratively optimized the training so that e.g. reproducing GPT-2 (124M) performance takes not 45 min (original) but now only 3 min!
- Now the idea is to use this process of optimizing the code as a benchmark for LLM coding agents. If humans can speed up LLM training from 45 to 3 minutes, how well do LLM Agents do, under different kinds of settings (e.g. with or without hints etc.)? (spoiler: in this paper, as a baseline and right now not that well, even with strong hints).
The idea of recursive self-improvement has of course been around for a long time. My usual rant on it is that it's not going to be this thing that didn't exist and then suddenly exists. Recursive self-improvement has already begun a long time ago and is under-way today in a smooth, incremental way. First, even basic software tools (e.g. coding IDEs) fall into the category because they speed up programmers in building the N+1 version. Any of our existing software infrastructure that speeds up development (google search, git, ...) qualifies. And then if you insist on AI as a special and distinct, most programmers now already routinely use LLM code completion or code diffs in their own programming workflows, collaborating in increasingly larger chunks of functionality and experimentation. This amount of collaboration will continue to grow.
It's worth also pointing out that nanoGPT is a super simple, tiny educational codebase (~750 lines of code) and for only the pretraining stage of building LLMs. Production-grade code bases are *significantly* (100-1000X?) bigger and more complex. But for the current level of AI capability, it is imo an excellent, interesting, tractable benchmark that I look forward to following.
Quietly building, testing, iterating. Today we’re out of stealth. Excited to finally share what we’ve been building at @hivergeai: an algorithm factory that creates new algorithms, optimised for real-world impact. Stay tuned!

Thrilled to announce @hivergeai. Our goal is to build algorithmic superintelligence.
See how we accelerate AI training and solve large-scale planning problems: hiverge.ai/blog/introducing-…

Amazing team, amazing work!

After 1.5 years of work, I'm so excited to announce AlphaEvolve – our new LLM + evolution agent!
Learn more in the blog post: deepmind.google/discover/blo…
White paper PDF: storage.googleapis.com/deepm…
(1/2)

Bernardino Romera-Paredes retweeted

Excited to share our latest work on EvoTune, a novel method integrating LLM-guided evolutionary search and reinforcement learning to accelerate the discovery of algorithms! 1/12🧵
This was a fun planning challenge, I wish there were more like this one. Thanks for organising!

The Beluga™ Competition results are in!
🏆Congrats to teams led by @ber24 , Daniel Gnad & Jean Jodeau!
Thanks also to the hundreds who registered & explored the challenge.
👉Check the winning teams bit.ly/3Yr3Nuu
#TrustworthyAI #ExplainableAI

Bernardino Romera-Paredes retweeted

Our team @GoogleDeepMind has released AlphaTensor-Quantum, a new method that improves quantum circuits by reducing T gates needed for quantum ops such as those used in Shor’s alg & chemistry sims. A step towards scalable Quantum Computing that can transform Science&Security.

In @NatMachIntell, we show how our AI system AlphaTensor-Quantum can make quantum computing more efficient. 🖥️⚡
By optimizing quantum circuits, it’s helping run calculations faster to save resources and accelerate discoveries. ↓ goo.gle/4iHAITd
