iOS · macOS · visionOS · Server-Side Swift engineer. AI-native Apple apps + open-source #OmniFocus MCP server.
Singapore
Joined March 2010
- Tweets773
- Following1.1K
- Followers442
- Likes5.7K






I was reminded of this quote today and needed the reminder.

"Eat food, not too much, mostly plants." More Evidence That Nutrition Studies Don’t Always Add Up - The New York Times nyti.ms/2DJIayn
Brent Deverman retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
My Mom: "Then it said copy to clipboard. I don't even know what that is."
Take a moment out of your day today to teach your mom the @Apple clipboard. Extra credit if you can get her to understand #clipboard history in #macOS 27.
Innovative content still trickling onto the @Apple Vision Pro!

#Remnants — The first immersive horror film on Apple Vision Pro.
Written & directed by Ti West.
Watch on Oct 16 only on Apple Vision Pro.

ALT An image of a person screaming in red. Text on the top reads “REMNANTS in Apple Immersive.” Text on the bottom reads “10.16.26 WRITTEN & DIRECTED BY TI WEST.”
If I was in #Singapore, I would be at this meetup at the end of this month.

First Nerds.sg meetup is happening this month, Friday, October 30.
I’ll send more details by tomorrow, including venue and speaker. Only 50 slots available, next one I’ll try and open it up to more.
I’m considering asking S$50 from confirmed attendees and give the money back at the door. I don’t plan on making money from it but I want to avoid flakes.

Brent Deverman retweeted
Amazon banning agents is the first opportunity I've seen since Amazon was founded for a startup to create an Amazon competitor. People will want agents to buy stuff for them. It will be one of the main use cases. And they won't want to use some Amazon-supplied agent to do it.
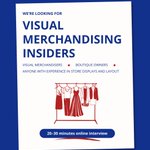
We are looking for owners of retail boutiques, and people with experience in visual merchandising. This is for our final project from @Apple Developer Academy in #Bali related to visual merchandising.
If you meet this criteria please comment below and I'll follow up.
#merchandising #retail #ios #iphone #shopping – at Kuta, Indonesia

I ran into the need for my agents to directly edit markdown files for a client in @Google drive and I am glad this is fixed.


Didn’t get in but was still setting up my Grok @bot this weekend.

Grokbot Workshop Bali ✅🌴
230+ registered
130 accepted
104 showed up, laptops open 💻
Students, founders and creators, many of them non-tech, building their first bots at Universitas Udayana today 🤖
Thanks @SpaceX, @BaliSquad199997
Couldn't get a seat? Next one's coming 👀


I hope this includes a new interface for managing these permissions rather than bolting it onto the current one.

"As AI agents become increasingly capable and autonomous, the risks associated with this level of access will grow substantially."
I hope this is fine-grained permissions, not making it more annoying to grant permissions, but I worry it'll be the latter
developer.apple.com/news/?id…

Brent Deverman retweeted

Google: “[Swift] has matured into a viable systems and cloud language, pairing Rust-like data-race safety with predictable, reference-counted performance.” Announcing their Swift-based cloud SDK for backend services: cloud.google.com/blog/topics…


Hope I'm in town.
Nerds of Singapore, I am planning the first Nerds.sg meetup and I need some help finding a venue. I'm shooting for 50 ish people. Preferably central, easy to get to, and an open space with a kitchen area. If you have a lead, let me know here or shoot me an email: [email protected]
PS: If you're obsessed with startups, design, technology, biotech, or anything else nerdy, register.
Good policy for most teams to follow.

We instituted an official AI Writing Policy at @Clay.
Massive thanks to @sophiebits on our engineering team who wrote this.
Originally this was just for eng, but other teams found it so helpful we expanded it company-wide.
Here are the four guiding principles:
1. You must stand behind every idea and sentence
It is your responsibility to make sure that the entire document is representative of your own thoughts before you share it.
2. Writing is thinking
Spending time on the writing process teaches you more about your topic. If you circumvent this process, you will walk away with a poorer understanding of the subject matter.
3. More time should be spent writing a document than consuming it
If you generate a document from a short prompt then ask your readers to go through the longer output, you are disrespecting their time. They can talk to ChatGPT themselves if they want to.
4. Longer is not better
AI makes it easy to generate long docs, and it loves padding them with sentences that say nothing. If you're producing docs from a short prompt, consider just sharing the prompt.
You can read (and borrow) the full policy below. Hopefully we all communicate a bit more clearly now :)

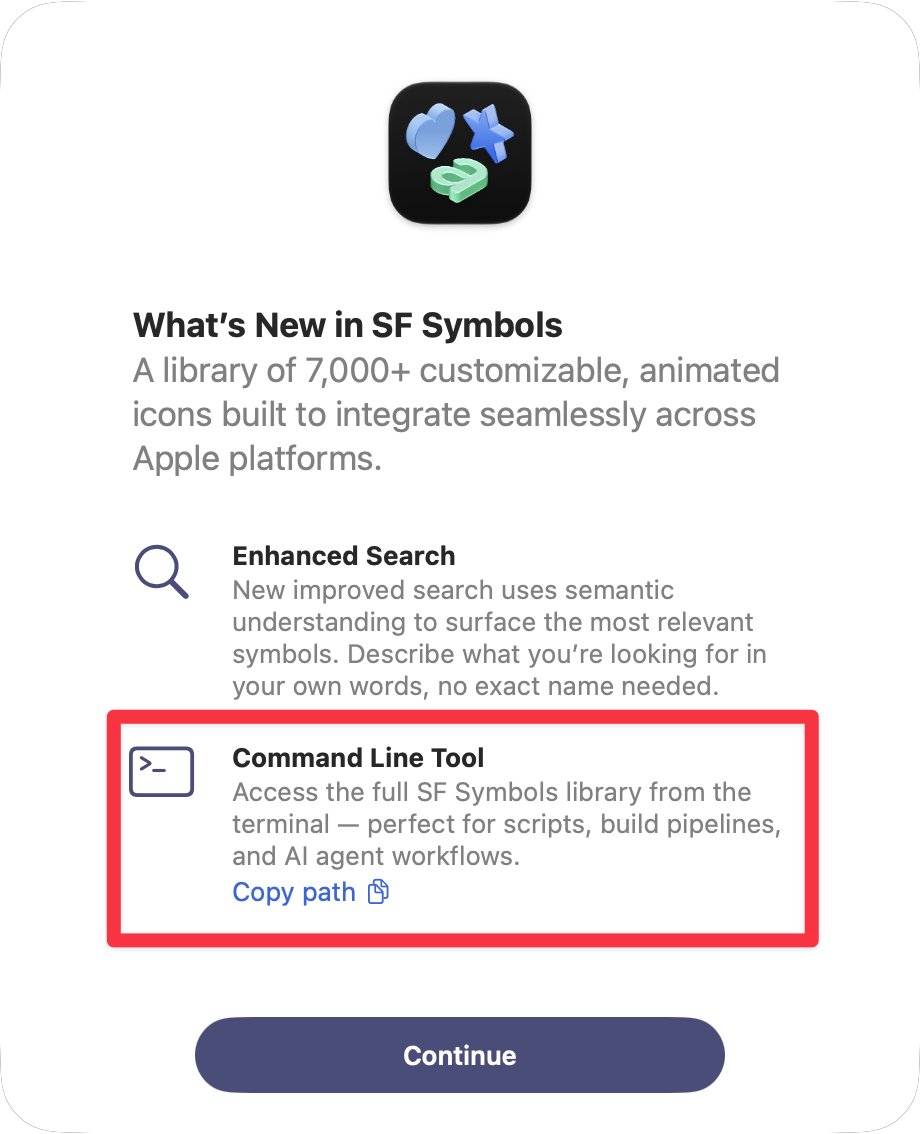
Wow that’s a great spot! Remember everyone’s CLI is due to be turned into @dhh by Friday.

原來 SF Symbols 27 有個 CLI
可以 search 跟 export
請給你的 agent 服用~
'/Applications/SF Symbols.app/Contents/Executa…'