
Pre-training @AnthropicAI On leave from PhD at MIT with Aleksander Madry
Joined September 2022
- Tweets25
- Following244
- Followers198
- Likes86




Ben Cohen-Wang retweeted

A statement on the comments from Secretary of War Pete Hegseth.
anthropic.com/news/statement…

Popular reasoning benchmarks just reward correct answers (they don't penalize guessing). This incentivizes models that guess when they're not sure which (beyond hurting usability) seems like it would encourage hallucinations more broadly. Is this why o3 etc. hallucinate a lot?
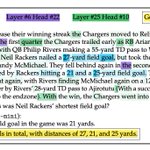
It can be helpful to pinpoint the in-context information that a language model uses when generating content (is it using provided documents? or its own intermediate thoughts?). We present Attribution with Attention (AT2), a method for doing so efficiently and reliably! (1/8)

AT2 makes it practical to, for example, produce citations for an existing RAG system.
Check out our demo which uses AT2 for citations in an LLM-powered search tool: bencw99.github.io/at2-citati… (7/8)

With @YungSungChuang, @aleks_madry!
For more, check out:
Python package: github.com/MadryLab/AT2
Paper: arxiv.org/abs/2504.13752
Demo: bencw99.github.io/at2-citati…

Increasingly, LLMs cite sources for claims they make, but are the sources they cite actually what they are using?
In work led by @YungSungChuang, we design a reward to quantify this, and use this reward to (automatically) improve citation quality!
🧵

(1/5)🚨LLMs can now self-improve to generate better citations✅
📝We design automatic rewards to assess citation quality
🤖Enable BoN/SimPO w/o external supervision
📈Perform close to “Claude Citations” API w/ only 8B model
📄arxiv.org/abs/2502.09604
🧑💻github.com/voidism/SelfCite


We introduce ContextCite, a tool that can help us understand when and how an LLM uses in-context information!
w/ @harshays_, @kris_georgiev1, @aleks_madry
Check out our demo:
huggingface.co/spaces/contex…
Thread ⤵️

How is an LLM actually using the info given to it in its context? Is it misinterpreting anything or making things up?
Introducing ContextCite: a simple method for attributing LLM responses back to the context: gradientscience.org/contextc…
w/ @bcohenwang, @harshays_, @kris_georgiev1
Ben Cohen-Wang retweeted

Models often fail under distribution shifts—can pre-training on a large and diverse dataset and then fine-tuning on a task-specific dataset help?
W/ @bcohenwang, @josh_vendrow we show that this depends on the specific failure mode. In particular, pre-training can help with extrapolation, but does not address failures that stem from dataset biases.

Ben Cohen-Wang retweeted
Will your model identify a polar bear on the moon? How would you know?
Dataset Interfaces let you generate images from your dataset under whatever distribution shift you desire!
arxiv.org/abs/2302.07865 gradientscience.org/dataset-…
W/ @josh_vendrow @saachi_jain_ @logan_engstrom

Ben Cohen-Wang retweeted
Our paper on immunizing images to diffusion model-powered malicious manipulation is out arxiv.org/abs/2302.06588! This approach, combined with policy incentives, aims to raise the cost of such unauthorized image editing.
w/ @hadisalmanX @Alaa_Khaddaj @gpoleclerc @andrew_ilyas
